Related Experiment Video
Updated: Nov 24, 2025

Author Spotlight: Integrated Multi-Omics Analysis for Unveiling Multicellular Immune Signatures in Clinical Heart Attack Cohorts
Published on: September 20, 2024
Fast Multi-View Clustering via Nonnegative and Orthogonal Factorization

Abstract:
The rapid growth of the number of data brings great challenges to clustering, especially the introduction of multi-view data, which collected from multiple sources or represented by multiple features, makes these challenges more arduous. How to clustering large-scale data efficiently has become the hottest topic of current large-scale clustering tasks. Although several accelerated multi-view methods have been proposed to improve the efficiency of clustering large-scale data, they still cannot be applied to some scenarios that require high efficiency because of the high computational complexity. To cope with the issue of high computational complexity of existing multi-view methods when dealing with large-scale data, a fast multi-view clustering model via nonnegative and orthogonal factorization (FMCNOF) is proposed in this paper. Instead of constraining the factor matrices to be nonnegative as traditional nonnegative and orthogonal factorization (NOF), we constrain a factor matrix of this model to be cluster indicator matrix which can assign cluster labels to data directly without extra post-processing step to extract cluster structures from the factor matrix. Meanwhile, the F-norm instead of the L2-norm is utilized on the FMCNOF model, which makes the model very easy to optimize. Furthermore, an efficient optimization algorithm is proposed to solve the FMCNOF model. Different from the traditional NOF optimization algorithm requiring dense matrix multiplications, our algorithm can divide the optimization problem into three decoupled small size subproblems that can be solved by much less matrix multiplications. Combined with the FMCNOF model and the corresponding fast optimization method, the efficiency of the clustering process can be significantly improved, and the computational complexity is nearly O(n) . Extensive experiments on various benchmark data sets validate our approach can greatly improve the efficiency when achieve acceptable performance.
More Related Videos
 12:27
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
 06:01
Visualization and Quantification of High-Dimensional Cytometry Data using Cytofast and the Upstream Clustering Methods FlowSOM and Cytosplore
Published on: December 12, 2019
Related Concept Videos
 01:14
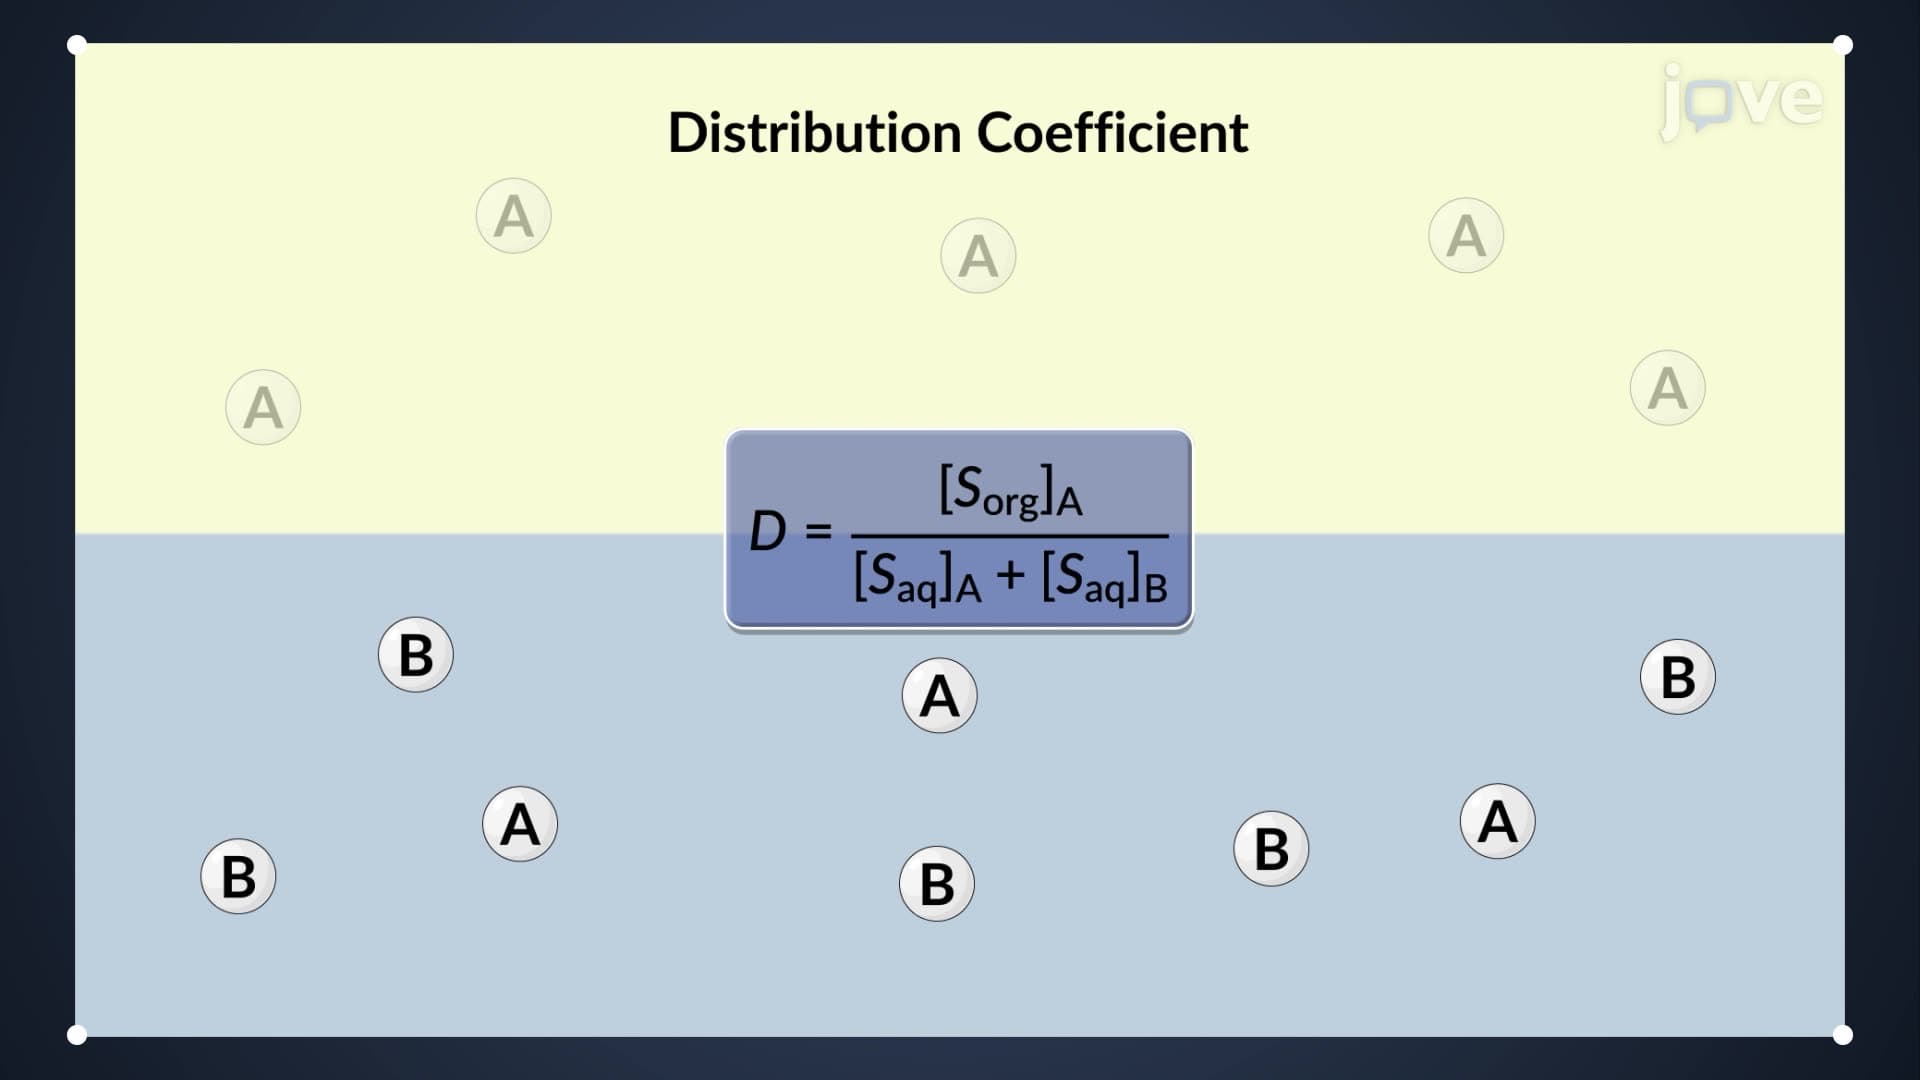
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...
 01:08
Vector Algebra: Method of Components
In many applications, the magnitudes and directions of...
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:05
Collisions in Multiple Dimensions: Introduction
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:06
Collisions in Multiple Dimensions: Problem Solving
A small car of mass 1,200 kg traveling east at 60 km/h collides at an intersection with a truck of mass 3,000 kg traveling due north at 40 km/h. The two vehicles are locked together. What is the...