Related Experiment Video
Updated: Nov 20, 2025
Heuristic Mining of Hierarchical Genotypes and Accessory Genome Loci in Bacterial Populations
Published on: December 7, 2021
Alignment-free Genomic Analysis via a Big Data Spark Platform
Umberto Ferraro Petrillo1, Francesco Palini1, Giuseppe Cattaneo2
1Dipartimento di Scienze Statistiche, Università di Roma - La Sapienza, Rome 00185, Italy.

Motivation:
Alignment-free distance and similarity functions (AF functions, for short) are a well-established alternative to pairwise and multiple sequence alignments for many genomic, metagenomic and epigenomic tasks. Due to data-intensive applications, the computation of AF functions is a Big Data problem, with the recent literature indicating that the development of fast and scalable algorithms computing AF functions is a high-priority task. Somewhat surprisingly, despite the increasing popularity of Big Data technologies in computational biology, the development of a Big Data platform for those tasks has not been pursued, possibly due to its complexity.
Results:
We fill this important gap by introducing FADE, the first extensible, efficient and scalable Spark platform for alignment-free genomic analysis. It supports natively eighteen of the best performing AF functions coming out of a recent hallmark benchmarking study. FADE development and potential impact comprises novel aspects of interest. Namely, (i) a considerable effort of distributed algorithms, the most tangible result being a much faster execution time of reference methods like MASH and FSWM; (ii) a software design that makes FADE user-friendly and easily extendable by Spark non-specialists; (iii) its ability to support data- and compute-intensive tasks. About this, we provide a novel and much needed analysis of how informative and robust AF functions are, in terms of the statistical significance of their output. Our findings naturally extend the ones of the highly regarded benchmarking study, since the functions that can really be used are reduced to a handful of the eighteen included in FADE.
Availabilityand Implementation:
The software and the datasets are available at https://github.com/fpalini/fade.
Supplementary Information:
Supplementary data are available at Bioinformatics online.
Related Concept Videos
 02:02
Genomics
 02:54
Evolutionary Relationships through Genome Comparisons
 02:34
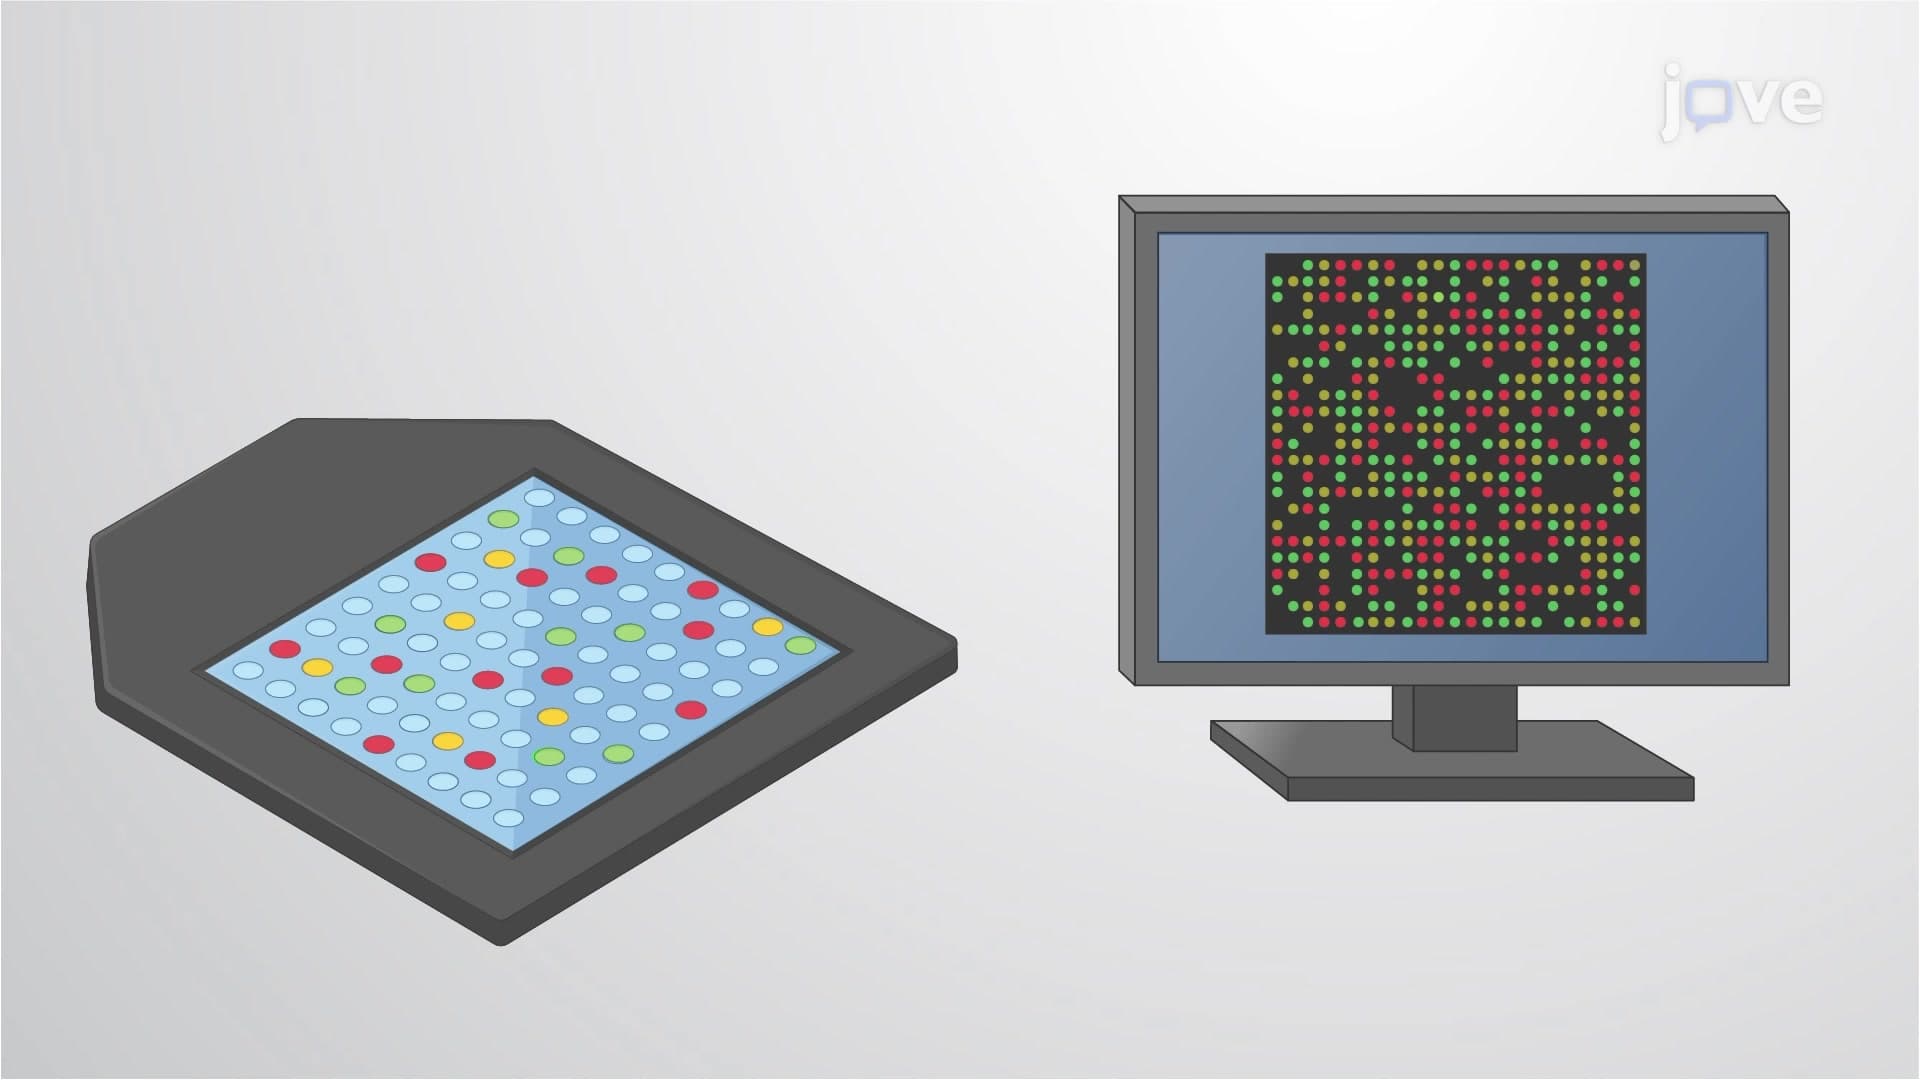
DNA Microarrays