Related Experiment Video
Updated: Nov 18, 2025
Photorealistic Learned Landscapes for Augmented Reality
Published on: June 27, 2025
Outdoor Inverse Rendering From a Single Image Using Multiview Self-Supervision

Abstract:
In this paper we show how to perform scene-level inverse rendering to recover shape, reflectance and lighting from a single, uncontrolled image using a fully convolutional neural network. The network takes an RGB image as input, regresses albedo, shadow and normal maps from which we infer least squares optimal spherical harmonic lighting coefficients. Our network is trained using large uncontrolled multiview and timelapse image collections without ground truth. By incorporating a differentiable renderer, our network can learn from self-supervision. Since the problem is ill-posed we introduce additional supervision. Our key insight is to perform offline multiview stereo (MVS) on images containing rich illumination variation. From the MVS pose and depth maps, we can cross project between overlapping views such that Siamese training can be used to ensure consistent estimation of photometric invariants. MVS depth also provides direct coarse supervision for normal map estimation. We believe this is the first attempt to use MVS supervision for learning inverse rendering. In addition, we learn a statistical natural illumination prior. We evaluate performance on inverse rendering, normal map estimation and intrinsic image decomposition benchmarks.
Related Concept Videos
 01:20
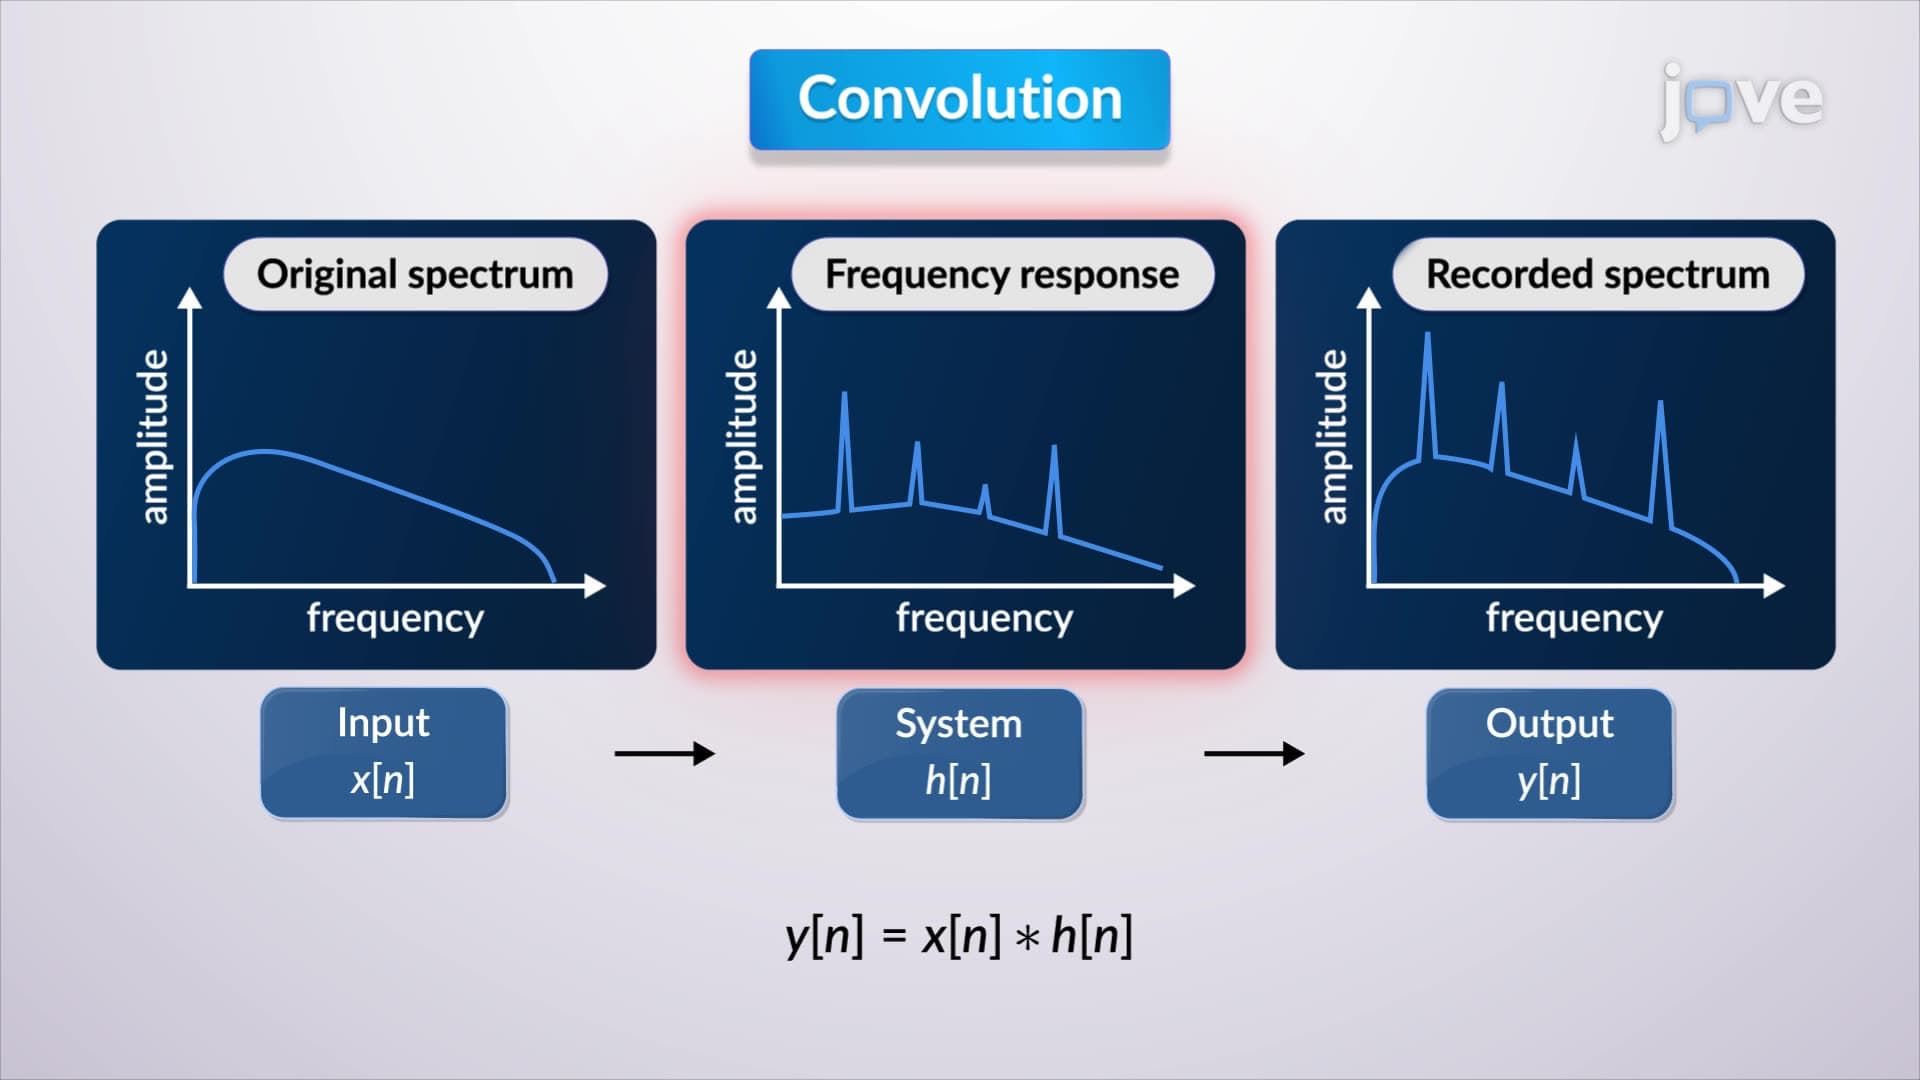
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:15
Depth Perception and Spatial Vision
 01:29
Relative Motion Analysis using Rotating Axes-Problem Solving
Here, in order to determine the magnitude of velocity and acceleration for point...
 02:16
Light Acquisition
 01:25
Relative Motion Analysis using Rotating Axes
However, to express the relative position of point B relative to point A, an additional frame of reference, denoted as x'y', is necessary. This additional frame not only translates but also rotates relative to the fixed frame, making it...
 01:18
Uniform Depth Channel Flow: Problem Solving