Related Experiment Video
Updated: Nov 10, 2025

Performing Data Mining And Integrative Analysis Of Biomarker in Breast Cancer Using Multiple Publicly Accessible Databases
Published on: May 17, 2019
Weight-Based Framework for Predictive Modeling of Multiple Databases With Noniterative Communication Without Data
Ji Ae Park1, Min Dong Sung1, Ho Heon Kim1
1Department of Biomedical System Informatics, Yonsei University College of Medicine, Seoul, Republic of Korea.

Background:
Securing the representativeness of study populations is crucial in biomedical research to ensure high generalizability. In this regard, using multi-institutional data have advantages in medicine. However, combining data physically is difficult as the confidential nature of biomedical data causes privacy issues. Therefore, a methodological approach is necessary when using multi-institution medical data for research to develop a model without sharing data between institutions.
Objective:
This study aims to develop a weight-based integrated predictive model of multi-institutional data, which does not require iterative communication between institutions, to improve average predictive performance by increasing the generalizability of the model under privacy-preserving conditions without sharing patient-level data.
Methods:
The weight-based integrated model generates a weight for each institutional model and builds an integrated model for multi-institutional data based on these weights. We performed 3 simulations to show the weight characteristics and to determine the number of repetitions of the weight required to obtain stable values. We also conducted an experiment using real multi-institutional data to verify the developed weight-based integrated model. We selected 10 hospitals (2845 intensive care unit [ICU] stays in total) from the electronic intensive care unit Collaborative Research Database to predict ICU mortality with 11 features. To evaluate the validity of our model, compared with a centralized model, which was developed by combining all the data of 10 hospitals, we used proportional overlap (ie, 0.5 or less indicates a significant difference at a level of .05; and 2 indicates 2 CIs overlapping completely). Standard and firth logistic regression models were applied for the 2 simulations and the experiment.
Results:
The results of these simulations indicate that the weight of each institution is determined by 2 factors (ie, the data size of each institution and how well each institutional model fits into the overall institutional data) and that repeatedly generating 200 weights is necessary per institution. In the experiment, the estimated area under the receiver operating characteristic curve (AUC) and 95% CIs were 81.36% (79.37%-83.36%) and 81.95% (80.03%-83.87%) in the centralized model and weight-based integrated model, respectively. The proportional overlap of the CIs for AUC in both the weight-based integrated model and the centralized model was approximately 1.70, and that of overlap of the 11 estimated odds ratios was over 1, except for 1 case.
Conclusions:
In the experiment where real multi-institutional data were used, our model showed similar results to the centralized model without iterative communication between institutions. In addition, our weight-based integrated model provided a weighted average model by integrating 10 models overfitted or underfitted, compared with the centralized model. The proposed weight-based integrated model is expected to provide an efficient distributed research approach as it increases the generalizability of the model and does not require iterative communication.
More Related Videos
 06:55
Inverse Probability of Treatment Weighting Propensity Score using the Military Health System Data Repository and National Death Index
Published on: January 8, 2020
 09:43
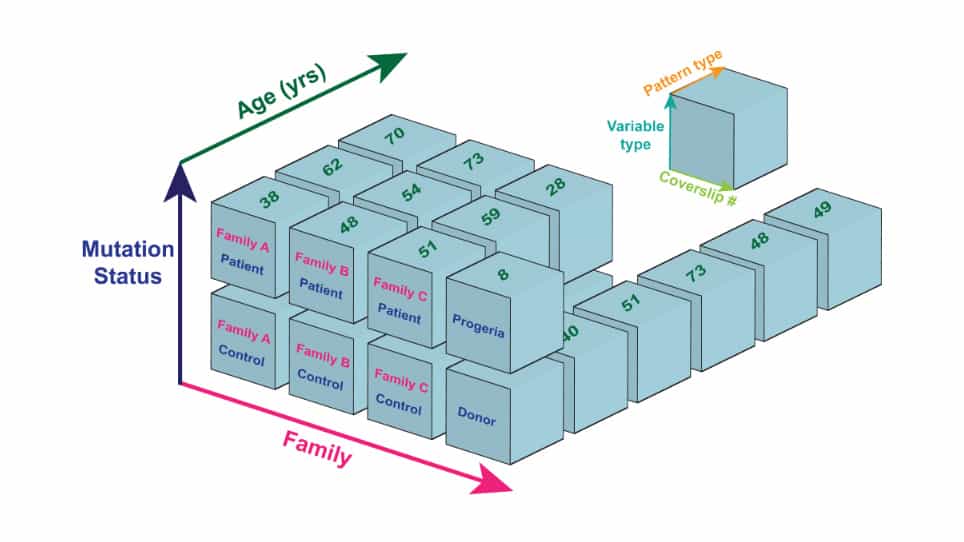
Databases to Efficiently Manage Medium Sized, Low Velocity, Multidimensional Data in Tissue Engineering
Published on: November 22, 2019
Related Concept Videos
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:12
Analysis of Population Pharmacokinetic Data
 00:59
Model-Independent Approaches for Pharmacokinetic Data: Noncompartmental Analysis
One important characteristic of noncompartmental analyses is that drug exposure increases proportionally with increasing doses. This...
 01:14
Analysis Methods of Pharmacokinetic Data: Model and Model-Independent Approaches
The model approach uses mathematical models to describe changes in drug concentration over time. Pharmacokinetic models help characterize drug behavior in patients, predict drug concentration in the body fluids, calculate optimum dosage regimens, and evaluate the risk of toxicity. However, ensuring that the model fits the experimental data accurately...