Related Experiment Video
Updated: Nov 8, 2025


An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
On the Rates of Convergence From Surrogate Risk Minimizers to the Bayes Optimal Classifier

Abstract:
In classification, the use of 0-1 loss is preferable since the minimizer of 0-1 risk leads to the Bayes optimal classifier. However, due to the nonconvexity of 0-1 loss, this optimization problem is NP-hard. Therefore, many convex surrogate loss functions have been adopted. Previous works have shown that if a Bayes-risk consistent loss function is used as a surrogate, the minimizer of the empirical surrogate risk can achieve the Bayes optimal classifier as the sample size tends to infinity. Nevertheless, the comparison of convergence rates of minimizers of different empirical surrogate risks to the Bayes optimal classifier has rarely been studied. Which characterization of the surrogate loss determines its convergence rate to the Bayes optimal classifier? Can we modify the loss function to achieve a faster convergence rate? In this article, we study the convergence rates of empirical surrogate minimizers to the Bayes optimal classifier. Specifically, we introduce the notions of consistency intensity and conductivity to characterize a surrogate loss function and exploit this notion to obtain the rate of convergence from an empirical surrogate risk minimizer to the Bayes optimal classifier, enabling fair comparisons of the excess risks of different surrogate risk minimizers. The main result of this article has practical implications including: 1) showing that hinge loss (SVM) is superior to logistic loss (Logistic regression) and exponential loss (Adaboost) in the sense that its empirical minimizer converges faster to the Bayes optimal classifier and 2) guiding the design of new loss functions to speed up the convergence rate to the Bayes optimal classifier with a data-dependent loss correction method inspired by our theorems.

Related Concept Videos
 00:59
Propagation of Uncertainty from Random Error
 01:12
Relative Risk
 01:19
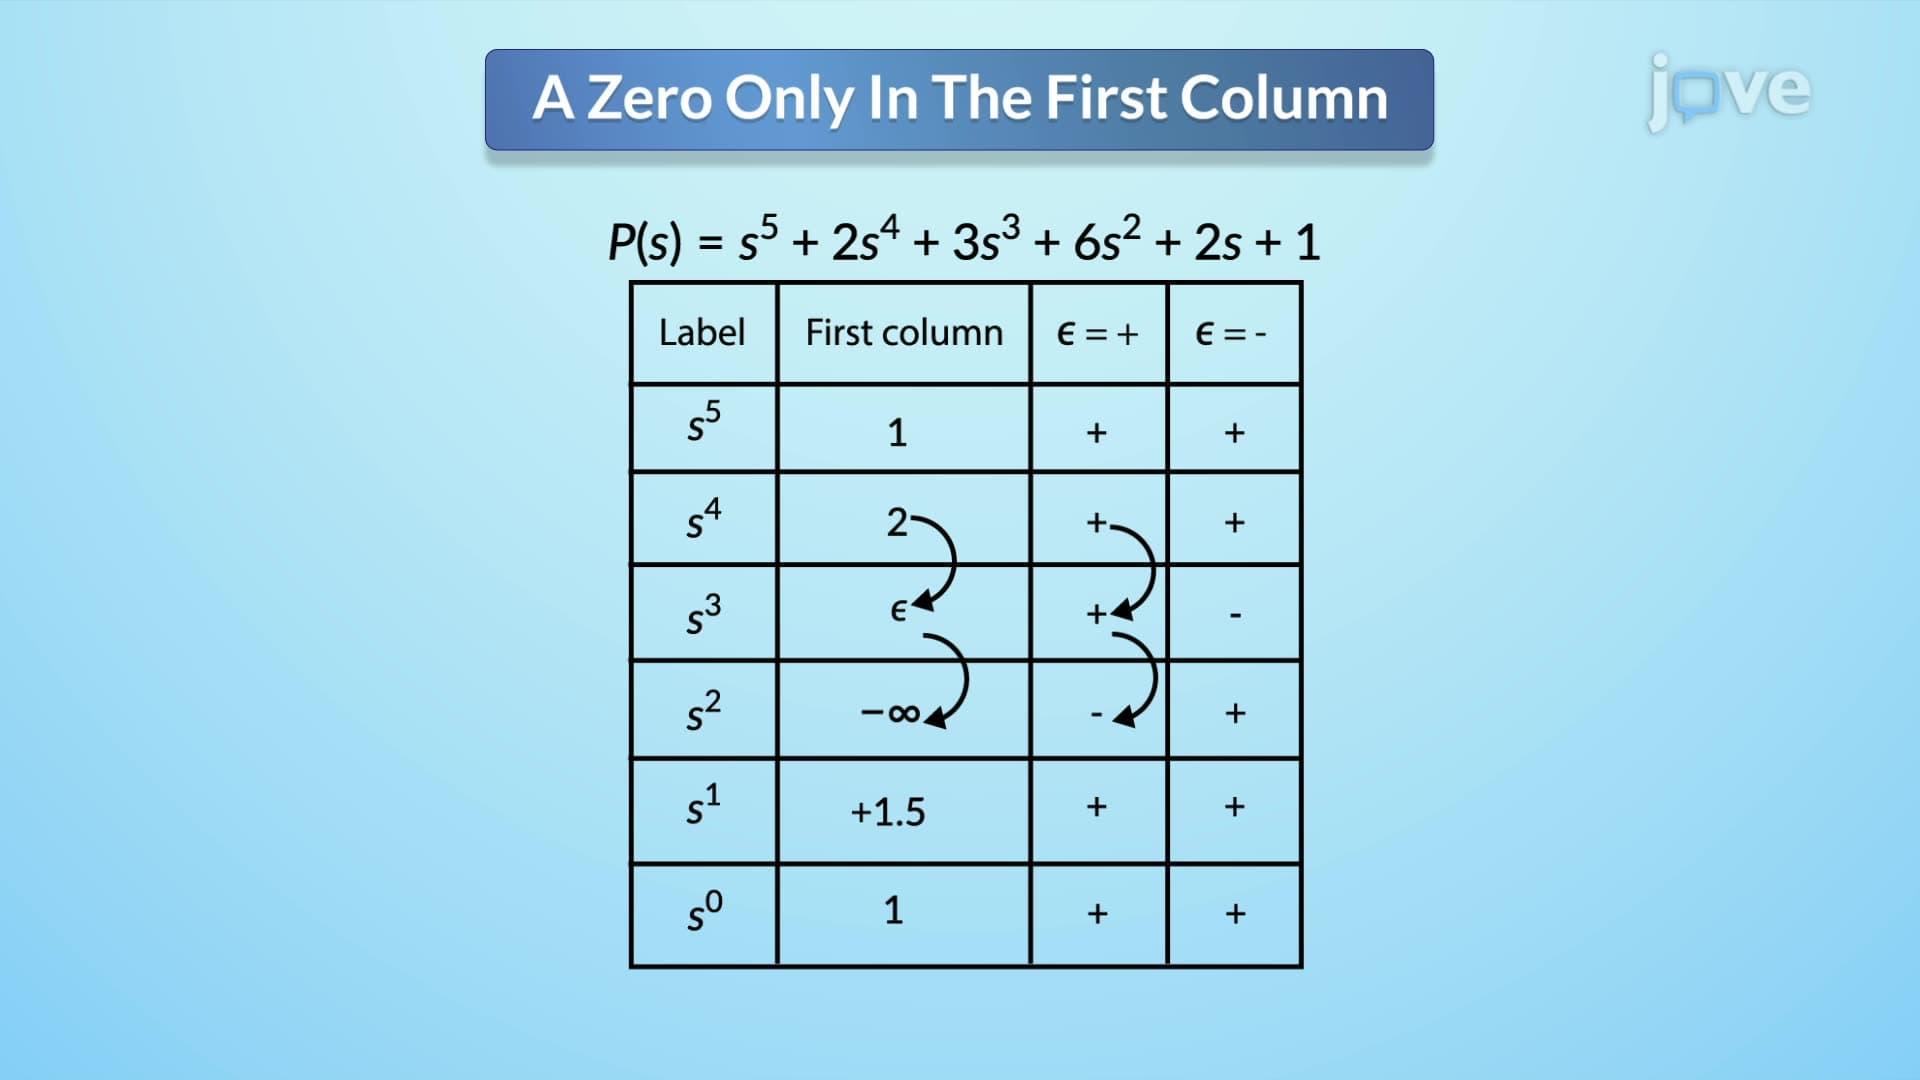
Routh-Hurwitz Criterion II
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first...
 01:10
Propagation of Uncertainty from Systematic Error
 01:15
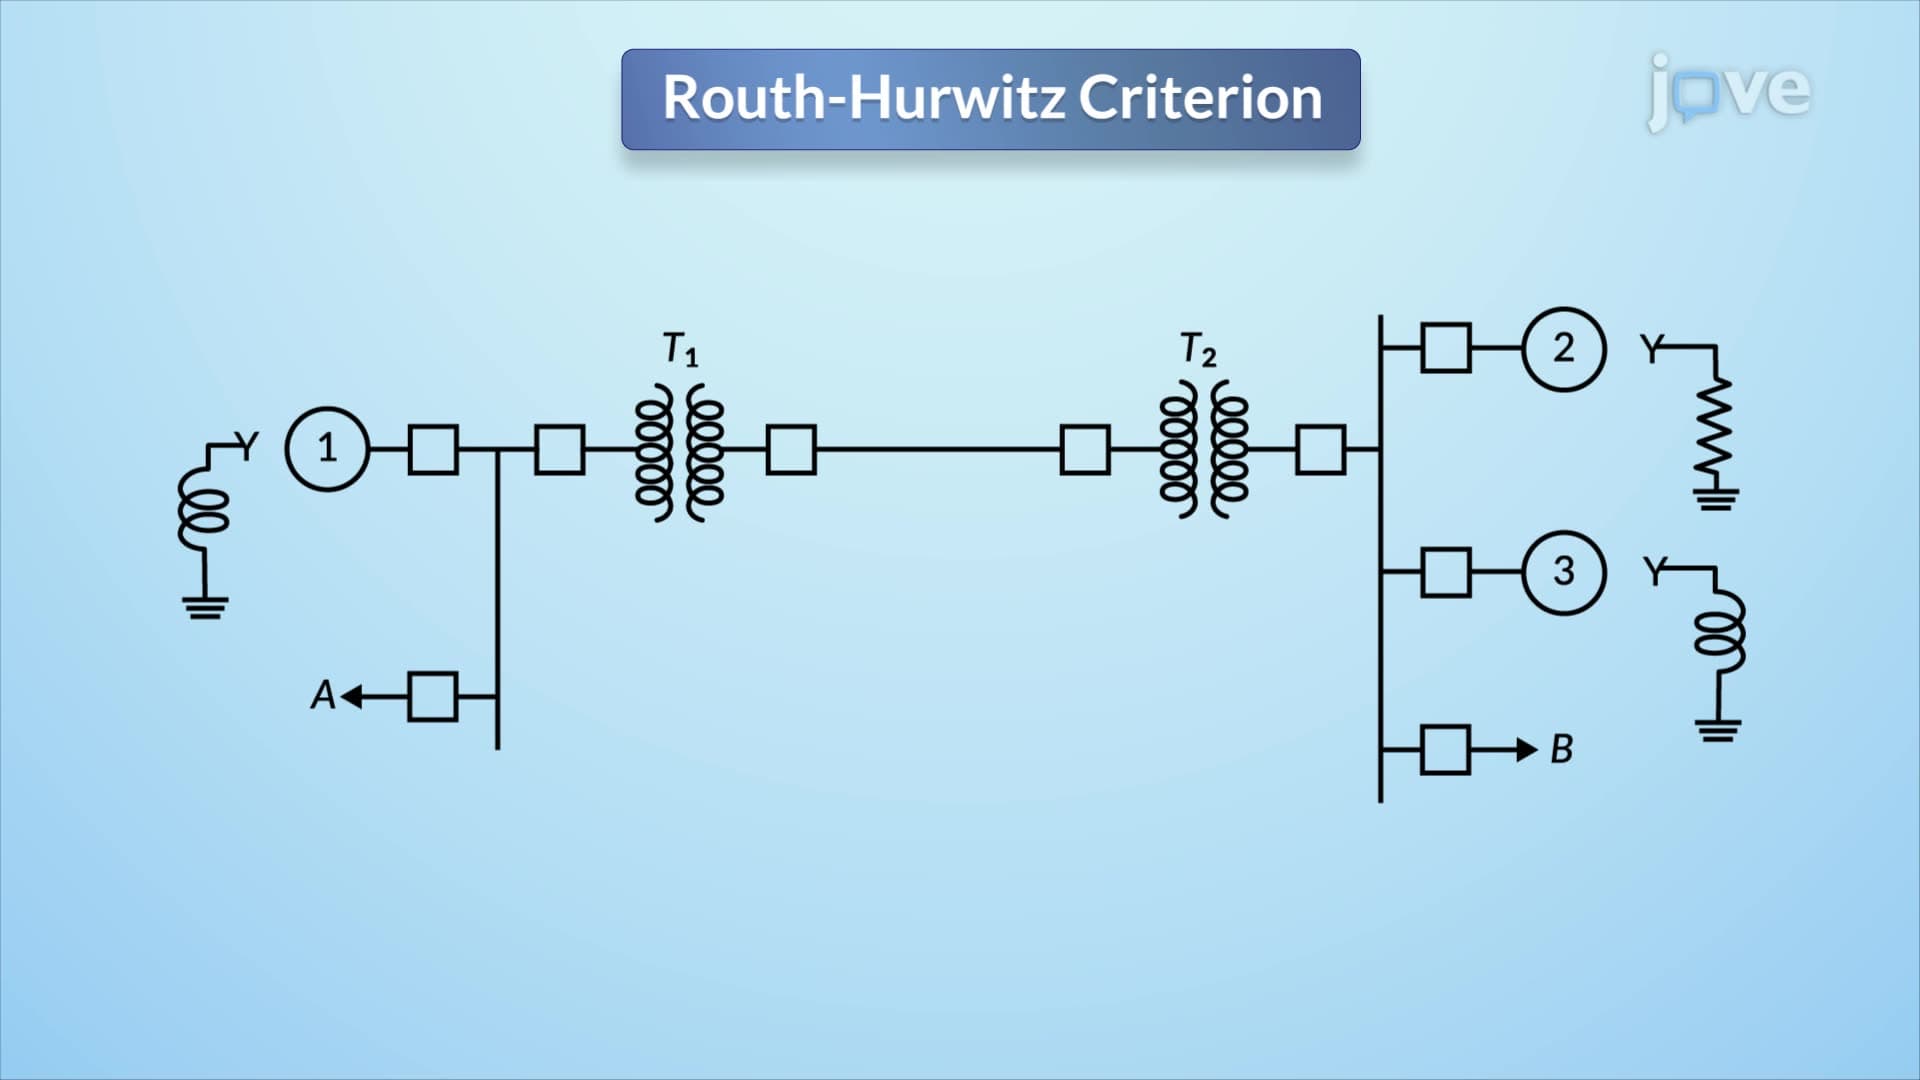
Routh-Hurwitz Criterion I
To apply the Routh-Hurwitz criterion, a Routh table is constructed. The table's rows are labeled with powers of the complex frequency variable s, starting from the...
 01:20
Region of Convergence of Laplace Tarnsform
Consider a decaying exponential signal that begins at a specific time. When deriving its Laplace transform, the time-domain variable is replaced with a complex variable. This...