Related Experiment Video
Updated: Nov 2, 2025

Isolation and Identification of Waterborne Antibiotic-Resistant Bacteria and Molecular Characterization of their Antibiotic Resistance Genes
Published on: March 3, 2023
Confidence interval methods for antimicrobial resistance surveillance data
Erta Kalanxhi1, Gilbert Osena1, Geetanjali Kapoor1
1Center for Disease Dynamics, Economics and Policy (CDDEP), Washington, DC, USA.

Background:
Antimicrobial resistance (AMR) is one of the greatest global health challenges today, but burden assessment is hindered by uncertainty of AMR prevalence estimates. Geographical representation of AMR estimates typically pools data collected from several laboratories; however, these aggregations may introduce bias by not accounting for the heterogeneity of the population that each laboratory represents.
Methods:
We used AMR data from up to 381 laboratories in the United States from The Surveillance Network to evaluate methods for estimating uncertainty of AMR prevalence estimates. We constructed confidence intervals for the proportion of resistant isolates using (1) methods that account for the clustered structure of the data, and (2) standard methods that assume data independence. Using samples of the full dataset with increasing facility coverage levels, we examined how likely the estimated confidence intervals were to include the population mean.
Results:
Methods constructing 95% confidence intervals while accounting for possible within-cluster correlations (Survey and standard methods adjusted to employ cluster-robust errors), were more likely to include the sample mean than standard methods (Logit, Wilson score and Jeffreys interval) operating under the assumption of independence. While increased geographical coverage improved the probability of encompassing the mean for all methods, large samples still did not compensate for the bias introduced from the violation of the data independence assumption.
Conclusion:
General methods for estimating the confidence intervals of AMR rates that assume data are independent, are likely to produce biased results. When feasible, the clustered structure of the data and any possible intra-cluster variation should be accounted for when calculating confidence intervals around AMR estimates, in order to better capture the uncertainty of prevalence estimates.
More Related Videos
 06:54
Author Spotlight: Understanding and Detecting Environmental Antimicrobial Resistance by Combining Culture-Based Techniques and Genomics
Published on: July 19, 2024
 09:59
Application of the Intelligent High-Throughput Antimicrobial Sensitivity Testing/Phage Screening System and Lar Index of Antimicrobial Resistance
Published on: July 21, 2023
Related Concept Videos
 01:21
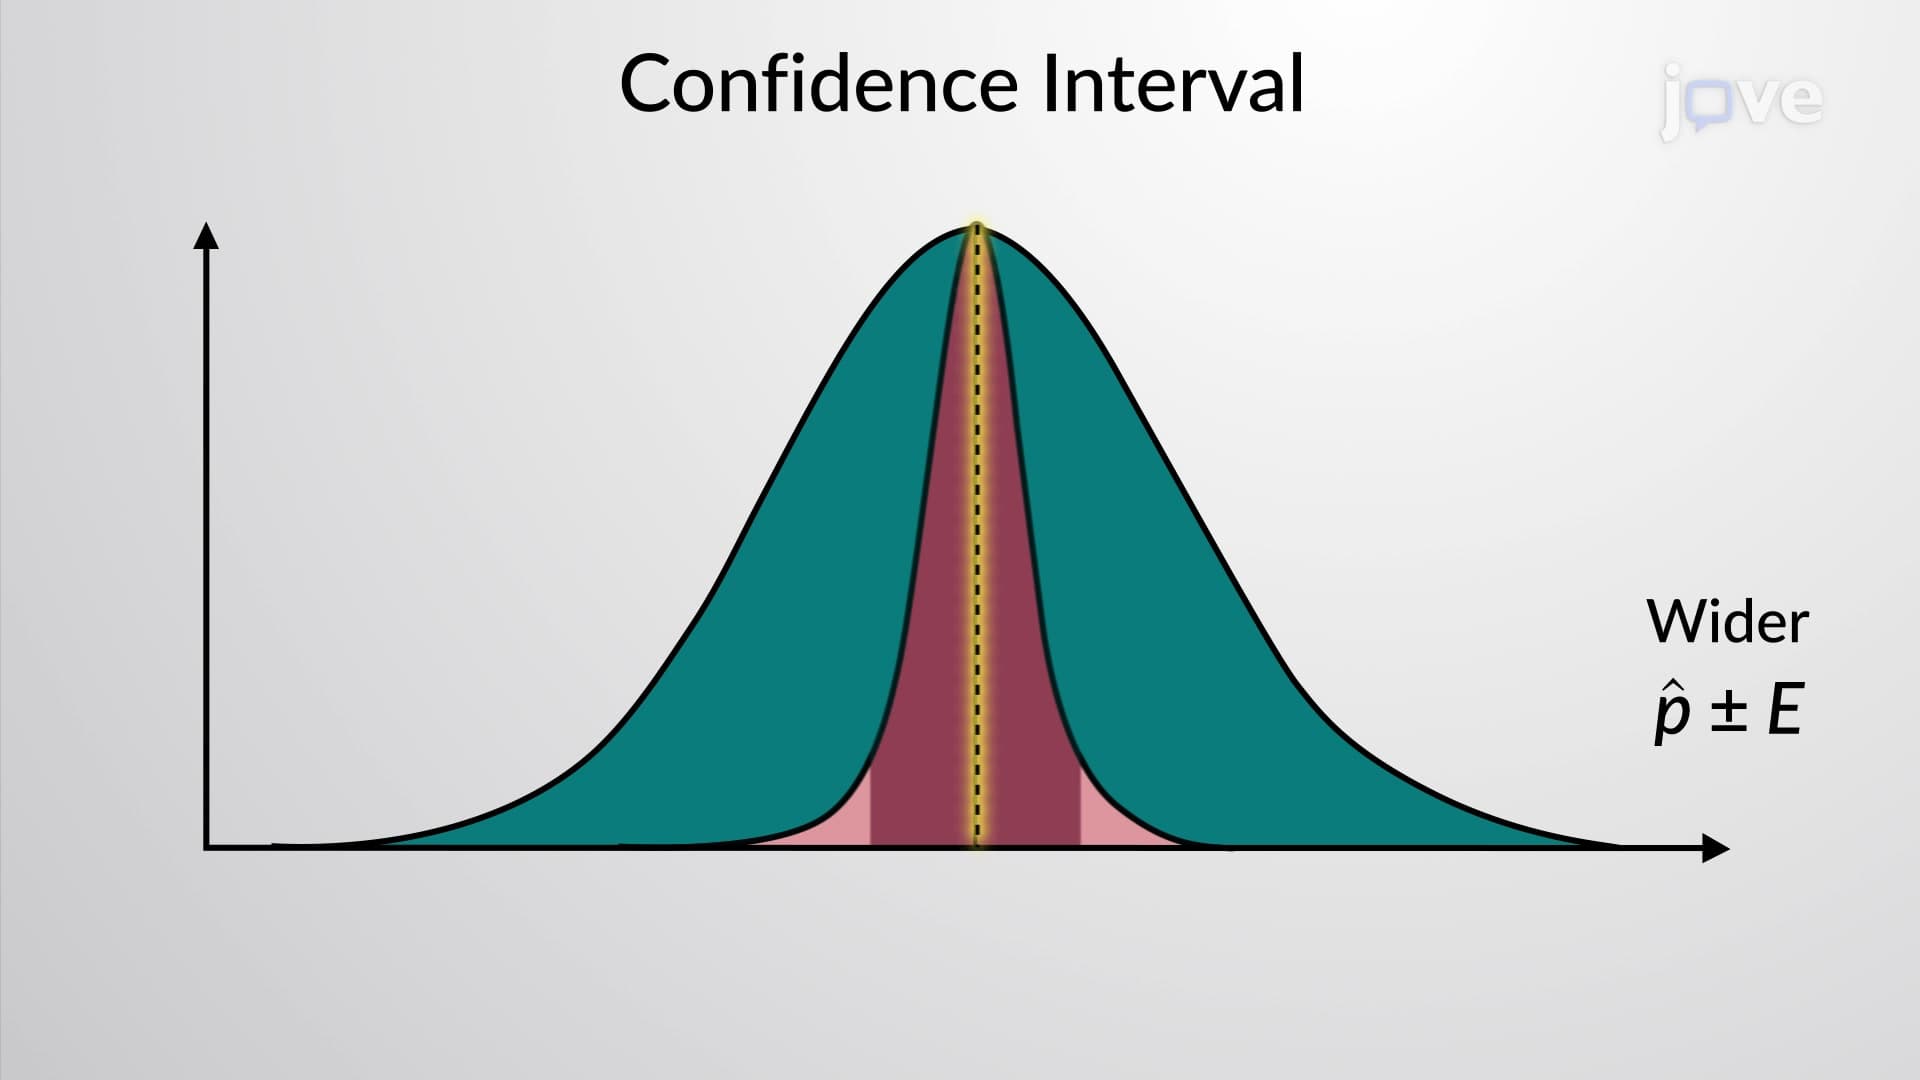
Confidence Intervals
A...
 01:19
Interpretation of Confidence Intervals
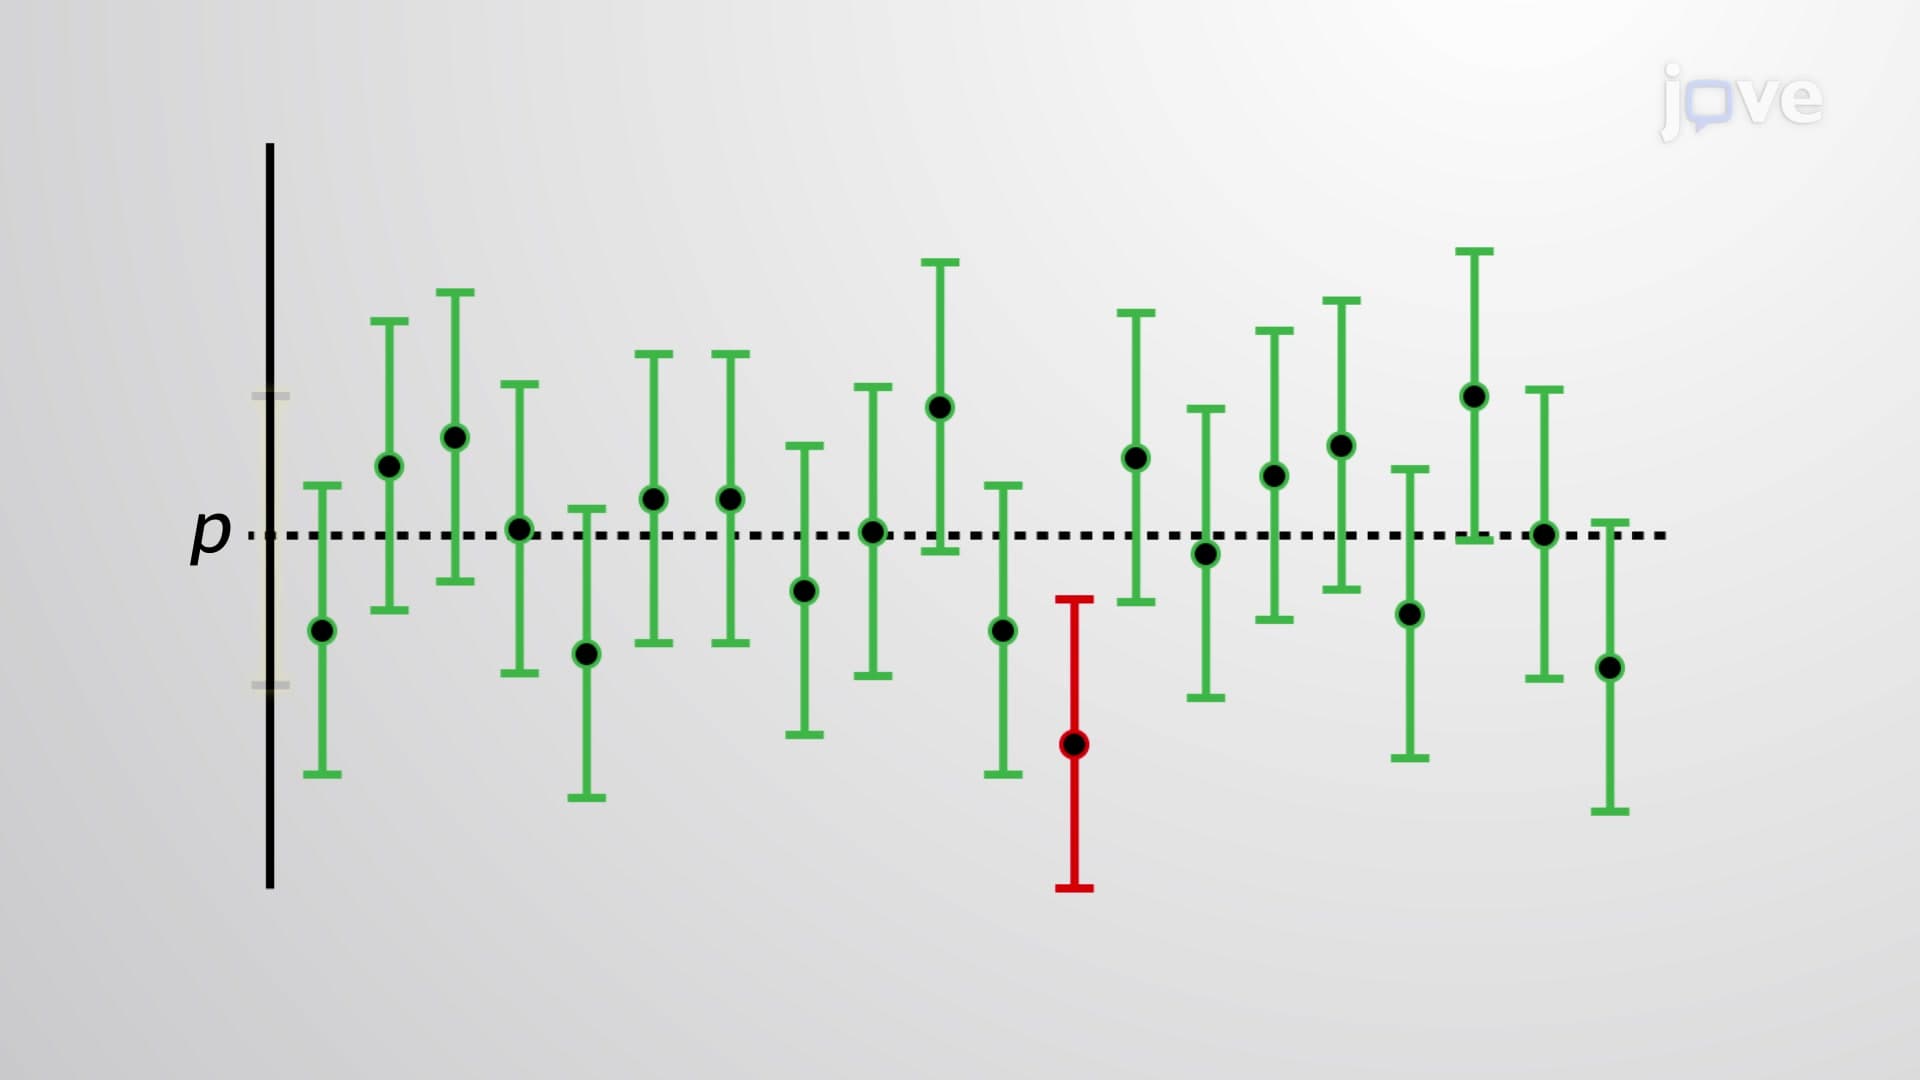
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
 00:54
Uncertainty: Confidence Intervals
 01:28
Antimicrobial Effectiveness
 01:24
Confidence Coefficient