Benchmark datasets incorporating diverse tasks, sample sizes, material systems, and data heterogeneity for materials informatics
Related Experiment Video
Updated: Oct 25, 2025
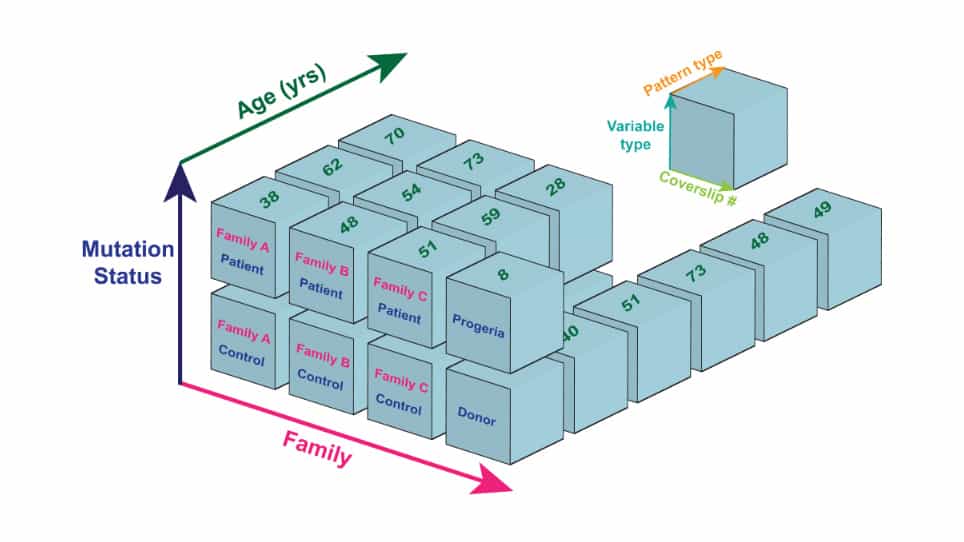
Databases to Efficiently Manage Medium Sized, Low Velocity, Multidimensional Data in Tissue Engineering
Published on: November 22, 2019
Ashley N Henderson1, Steven K Kauwe1, Taylor D Sparks1
1Materials Science & Engineering Department, University of Utah, Utah 84112, USA.

Abstract:
Materials discovery via machine learning has become an increasingly popular method due to its ability to rapidly predict materials properties in a time-efficient and low-cost manner. However, one limitation in this field is the lack of benchmark datasets, particularly those that encompass the size, tasks, material systems, and data modalities present in the materials informatics literature. This makes it difficult to identify optimal machine learning model choices including algorithm, model architecture, data splitting, and data featurization for a given task. Here, we attempt to address this lack of benchmark datasets by assembling a unique repository of 50 different datasets for materials properties. The data contains both experimental and computational data, data suited for regression as well as classification, sizes ranging from 12 to 6354 samples, and materials systems spanning the diversity of materials research. Data were extracted from 16 publications. In addition to cleaning the data where necessary, each dataset was split into train, validation, and test splits. For datasets with more than 100 values, train-val-test splits were created, either with a 5-fold or 10-fold cross-validation method, depending on what each respective paper did in their studies. Datasets with less than 100 values had train-test splits created using the Leave-One-Out cross-validation method. These benchmark data can serve as a basis for a more diverse benchmark dataset in the future to further improve their effectiveness in the comparison of machine learning models.

Related Concept Videos
 01:17
Systematic Sampling Method
Systematic sampling is one of the simplest methods...
 01:19
Sample Size Calculation
The sample size for the given experiment or sampling effort is fundamental to any study design. Sample size decides the number of...
 01:13
Data Collection by Experiments
An example of the experimental method is a public...
 01:15
One-Way ANOVA: Unequal Sample Sizes
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:15
Study Design in Statistics
Does aspirin reduce the risk of heart attacks? Is one brand of fertilizer more effective at growing roses than another? Is fatigue as dangerous to a driver as the influence of alcohol? Questions like these are answered using randomized experiments with proper...