Related Experiment Video
Updated: Oct 25, 2025
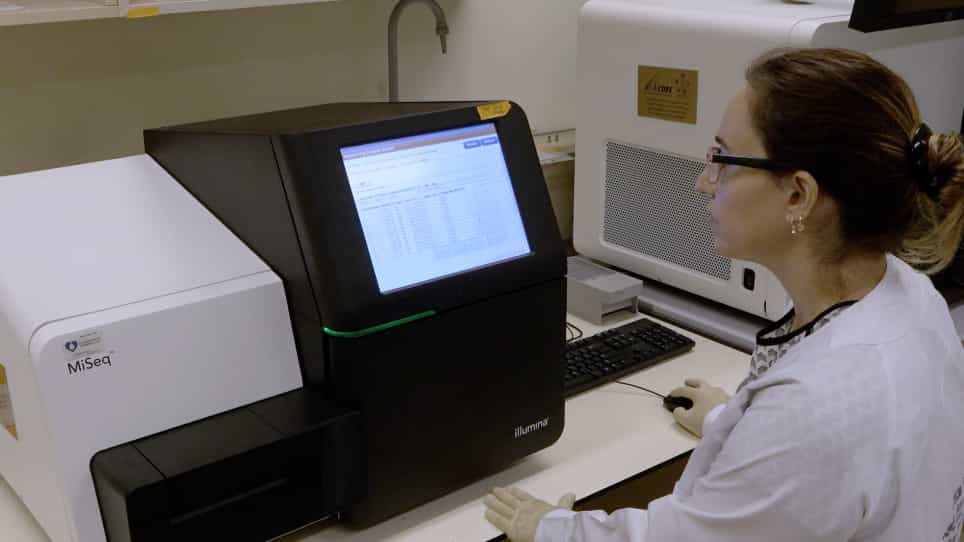

T and B Cell Receptor Immune Repertoire Analysis using Next-generation Sequencing
Published on: January 12, 2021
Immune2vec: Embedding B/T Cell Receptor Sequences in ℝ Using Natural Language Processing
Miri Ostrovsky-Berman1,2, Boaz Frankel1,2, Pazit Polak1,2
1Bioengineering, Faculty of Engineering, Bar Ilan University, Ramat Gan, Israel.

The adaptive branch of the immune system learns pathogenic patterns and remembers them for future encounters. It does so through dynamic and diverse repertoires of T- and B- cell receptors (TCR and BCRs, respectively). These huge immune repertoires in each individual present investigators with the challenge of extracting meaningful biological information from multi-dimensional data. The ability to embed these DNA and amino acid textual sequences in a vector-space is an important step towards developing effective analysis methods. Here we present Immune2vec, an adaptation of a natural language processing (NLP)-based embedding technique for BCR repertoire sequencing data. We validate Immune2vec on amino acid 3-gram sequences, continuing to longer BCR sequences, and finally to entire repertoires. Our work demonstrates Immune2vec to be a reliable low-dimensional representation that preserves relevant information of immune sequencing data, such as n-gram properties and IGHV gene family classification. Applying Immune2vec along with machine learning approaches to patient data exemplifies how distinct clinical conditions can be effectively stratified, indicating that the embedding space can be used for feature extraction and exploratory data analysis.
The adaptive branch of the immune system learns pathogenic patterns and remembers them for future encounters. It does so through dynamic and diverse repertoires of T- and B- cell receptors (TCR and BCRs, respectively). These huge immune repertoires in each individual present investigators with the challenge of extracting meaningful biological information from multi-dimensional data. The ability to embed these DNA and amino acid textual sequences in a vector-space is an important step towards developing effective analysis methods. Here we present Immune2vec, an adaptation of a natural language processing (NLP)-based embedding technique for BCR repertoire sequencing data. We validate Immune2vec on amino acid 3-gram sequences, continuing to longer BCR sequences, and finally to entire repertoires. Our work demonstrates Immune2vec to be a reliable low-dimensional representation that preserves relevant information of immune sequencing data, such as n-gram properties and IGHV gene family classification. Applying Immune2vec along with machine learning approaches to patient data exemplifies how distinct clinical conditions can be effectively stratified, indicating that the embedding space can be used for feature extraction and exploratory data analysis.
Related Concept Videos
 01:28
Diversity of Antigen Receptors
Before encountering any antigen, lymphocytes express these receptors. On B cells, the antigen receptor is a membrane-bound antibody molecule called BCR; on T cells, it is a T cell receptor or TCR. B and T cell receptors are composed of two...
 02:28
Leaky Scanning
 01:24
B Cell Activation and Differentiation
When naive B cells encounter a specific antigen that can bind to the B cell receptor (BCR) on their surface, they undergo sensitization to respond to the antigen's presence. Sensitization begins with...
 01:22
T Cell Activation and Clonal Selection
Naive T cells that have not yet encountered an antigen express two primary CD...
 02:26
tRNA Activation
02:26tRNA Activation