Related Experiment Video
Updated: Oct 24, 2025
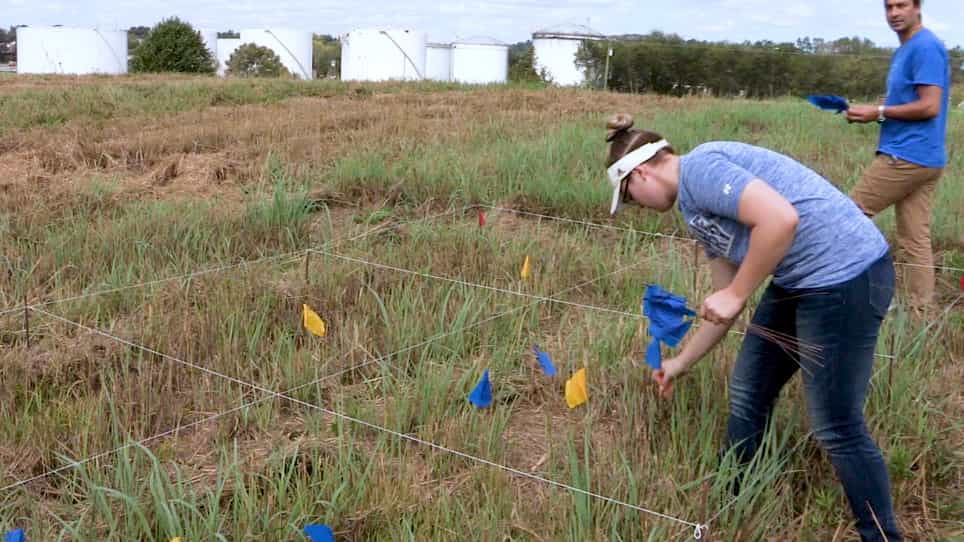

Sampling Soils in a Heterogeneous Research Plot
Published on: January 7, 2019
A multifunctional matching algorithm for sample design in agricultural plots
N Ohana-Levi1, A Derumigny2, A Peeters3
1Independent Researcher, Variability, Ashalim 85512, Israel.

Abstract:
Collection of accurate and representative data from agricultural fields is required for efficient crop management. Since growers have limited available resources, there is a need for advanced methods to select representative points within a field in order to best satisfy sampling or sensing objectives. The main purpose of this work was to develop a data-driven method for selecting locations across an agricultural field given observations of some covariates at every point in the field. These chosen locations should be representative of the distribution of the covariates in the entire population and represent the spatial variability in the field. They can then be used to sample an unknown target feature whose sampling is expensive and cannot be realistically done at the population scale. An algorithm for determining these optimal sampling locations, namely the multifunctional matching (MFM) criterion, was based on matching of moments (functionals) between sample and population. The selected functionals in this study were standard deviation, mean, and Kendall's tau. An additional algorithm defined the minimal number of observations that could represent the population according to a desired level of accuracy. The MFM was applied to datasets from two agricultural plots: a vineyard and a peach orchard. The data from the plots included measured values of slope, topographic wetness index, normalized difference vegetation index, and apparent soil electrical conductivity. The MFM algorithm selected the number of sampling points according to a representation accuracy of 90% and determined the optimal location of these points. The algorithm was validated against values of vine or tree water status measured as crop water stress index (CWSI). Algorithm performance was then compared to two other sampling methods: the conditioned Latin hypercube sampling (cLHS) model and a uniform random sample with spatial constraints. Comparison among sampling methods was based on measures of similarity between the target variable population distribution and the distribution of the selected sample. MFM represented CWSI distribution better than the cLHS and the uniform random sampling, and the selected locations showed smaller deviations from the mean and standard deviation of the entire population. The MFM functioned better in the vineyard, where spatial variability was larger than in the orchard. In both plots, the spatial pattern of the selected samples captured the spatial variability of CWSI. MFM can be adjusted and applied using other moments/functionals and may be adopted by other disciplines, particularly in cases where small sample sizes are desired.
More Related Videos

Related Concept Videos
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:23
Sampling Plans
Random sampling is a method where each member of the population has an equal chance of being selected for the sample. It involves selecting individuals randomly, often using random number generators or lottery-type methods. For example, when analyzing the properties of a...
 01:15
Bioequivalence Experimental Study Designs: Repeated Measures, Cross-Over, Carry-Over, and Latin Square Designs
 01:16
Stratified Sampling Method
To choose a stratified sample, divide the population into groups called strata and then take a...
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:13
Multiple Comparison Tests
It would be easy to compare two samples using a significance alpha level of 0.05. In other words, there is only one sample pair to be compared. However, it would be difficult to identify a significantly different sample if the number...