Related Experiment Video
Updated: Oct 24, 2025
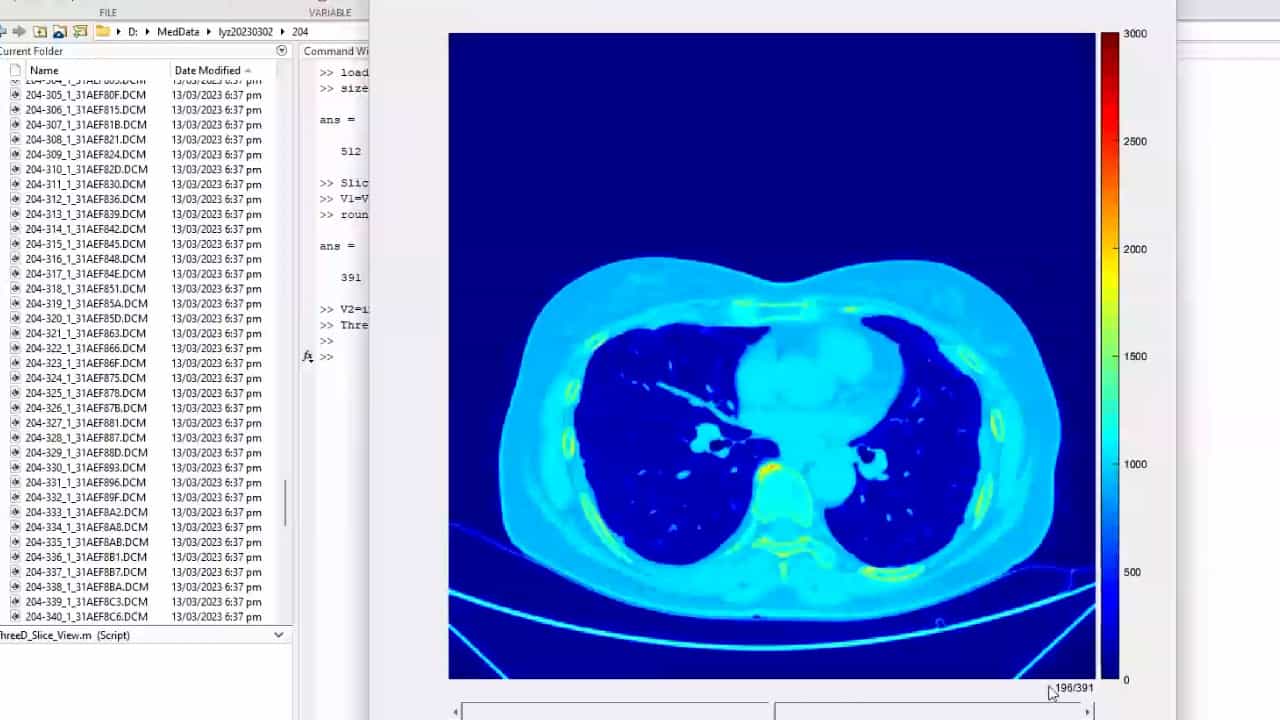

Author Spotlight: Advancing 3D Modeling for Enhanced Diagnosis and Treatment of Pulmonary Nodules in Early-Stage Lung Cancer
Published on: October 13, 2023
Optimal number of strong labels for curriculum learning with convolutional neural network to classify pulmonary
Yongwon Cho1, Beomhee Park1, Sang Min Lee2
1Department of Biomedical Engineering, Asan Medical Institute of Convergence Science and Technology, Asan Medical Center, University of Ulsan College of Medicine, Seoul, 88 Olympic-Ro 43-Gil Songpa-Gu, Seoul, 05505, Republic of Korea.

Background And Objective:
It is important to alleviate annotation efforts and costs by efficiently training on medical images. We performed a stress test on several strong labels for curriculum learning with a convolutional neural network to differentiate normal and five types of pulmonary abnormalities in chest radiograph images.
Methods:
The numbers of CXR images of healthy subjects and patients, acquired at Asan Medical Center (AMC), were 6069 and 3465, respectively. The numbers of CXR images of patients with nodules, consolidation, interstitial opacity, pleural effusion, and pneumothorax were 944, 550, 280, 1360, and 331, respectively. The AMC dataset was split into training, tuning, and test, with a ratio of 7:1:2. All lesions were strongly labeled by thoracic expert radiologists, with confirmation of the corresponding CT. For curriculum learning, normal and abnormal patches (N = 26658) were randomly extracted around the normal lung and strongly labeled abnormal lesions, respectively. In addition, 1%, 5%, 20%, 50%, and 100% of strong labels were used to determine an optimal number for them. Each patch dataset was trained with the ResNet-50 architecture, and all CXRs with weak labels were used for fine-tuning them in a transfer-learning manner. A dataset acquired from the Seoul National University Bundang Hospital (SNUBH) was used for external validation.
Results:
The detection accuracies of the 1%, 5%, 20%, 50%, and 100% datasets were 90.51, 92.15, 93.90, 94.54, and 95.39, respectively, in the AMC dataset and 90.01, 90.14, 90.97, 91.92, and 93.00 in the SNUBH dataset.
Conclusions:
Our results showed that curriculum learning with over 20% sampling rate for strong labels are sufficient to train a model with relatively high performance, which can be easily and efficiently developed in an actual clinical setting.
More Related Videos
Related Concept Videos
 01:30
Classification of Leukocytes
Neutrophils are the most abundant type of granular leukocytes, comprising 50-70% of all leukocytes. They feature small, evenly distributed granules and a...
 01:22
Force Classification
Contact and non-contact forces are two of the most widely used categories of forces. As the name suggests, contact forces require physical contact between two objects to act upon each other. Examples of contact forces include frictional,...
 01:31
Classification of Systems-II
 01:30
Classification of Signals
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...