Related Experiment Video
Updated: Oct 21, 2025


WheelCon: A Wheel Control-Based Gaming Platform for Studying Human Sensorimotor Control
Published on: August 15, 2020
A Maximum Divergence Approach to Optimal Policy in Deep Reinforcement Learning

Abstract:
Model-free reinforcement learning algorithms based on entropy regularized have achieved good performance in control tasks. Those algorithms consider using the entropy-regularized term for the policy to learn a stochastic policy. This work provides a new perspective that aims to explicitly learn a representation of intrinsic information in state transition to obtain a multimodal stochastic policy, for dealing with the tradeoff between exploration and exploitation. We study a class of Markov decision processes (MDPs) with divergence maximization, called divergence MDPs. The goal of the divergence MDPs is to find an optimal stochastic policy that maximizes the sum of both the expected discounted total rewards and a divergence term, where the divergence function learns the implicit information of state transition. Thus, it can provide better-off stochastic policies to improve both in robustness and performance in a high-dimension continuous setting. Under this framework, the optimality equations can be obtained, and then a divergence actor-critic algorithm is developed based on the divergence policy iteration method to address large-scale continuous problems. The experimental results, compared to other methods, show that our approach achieved better performance and robustness in the complex environment particularly. The code of DivAC can be found in https://github.com/yzyvl/DivAC.
Related Concept Videos
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:09
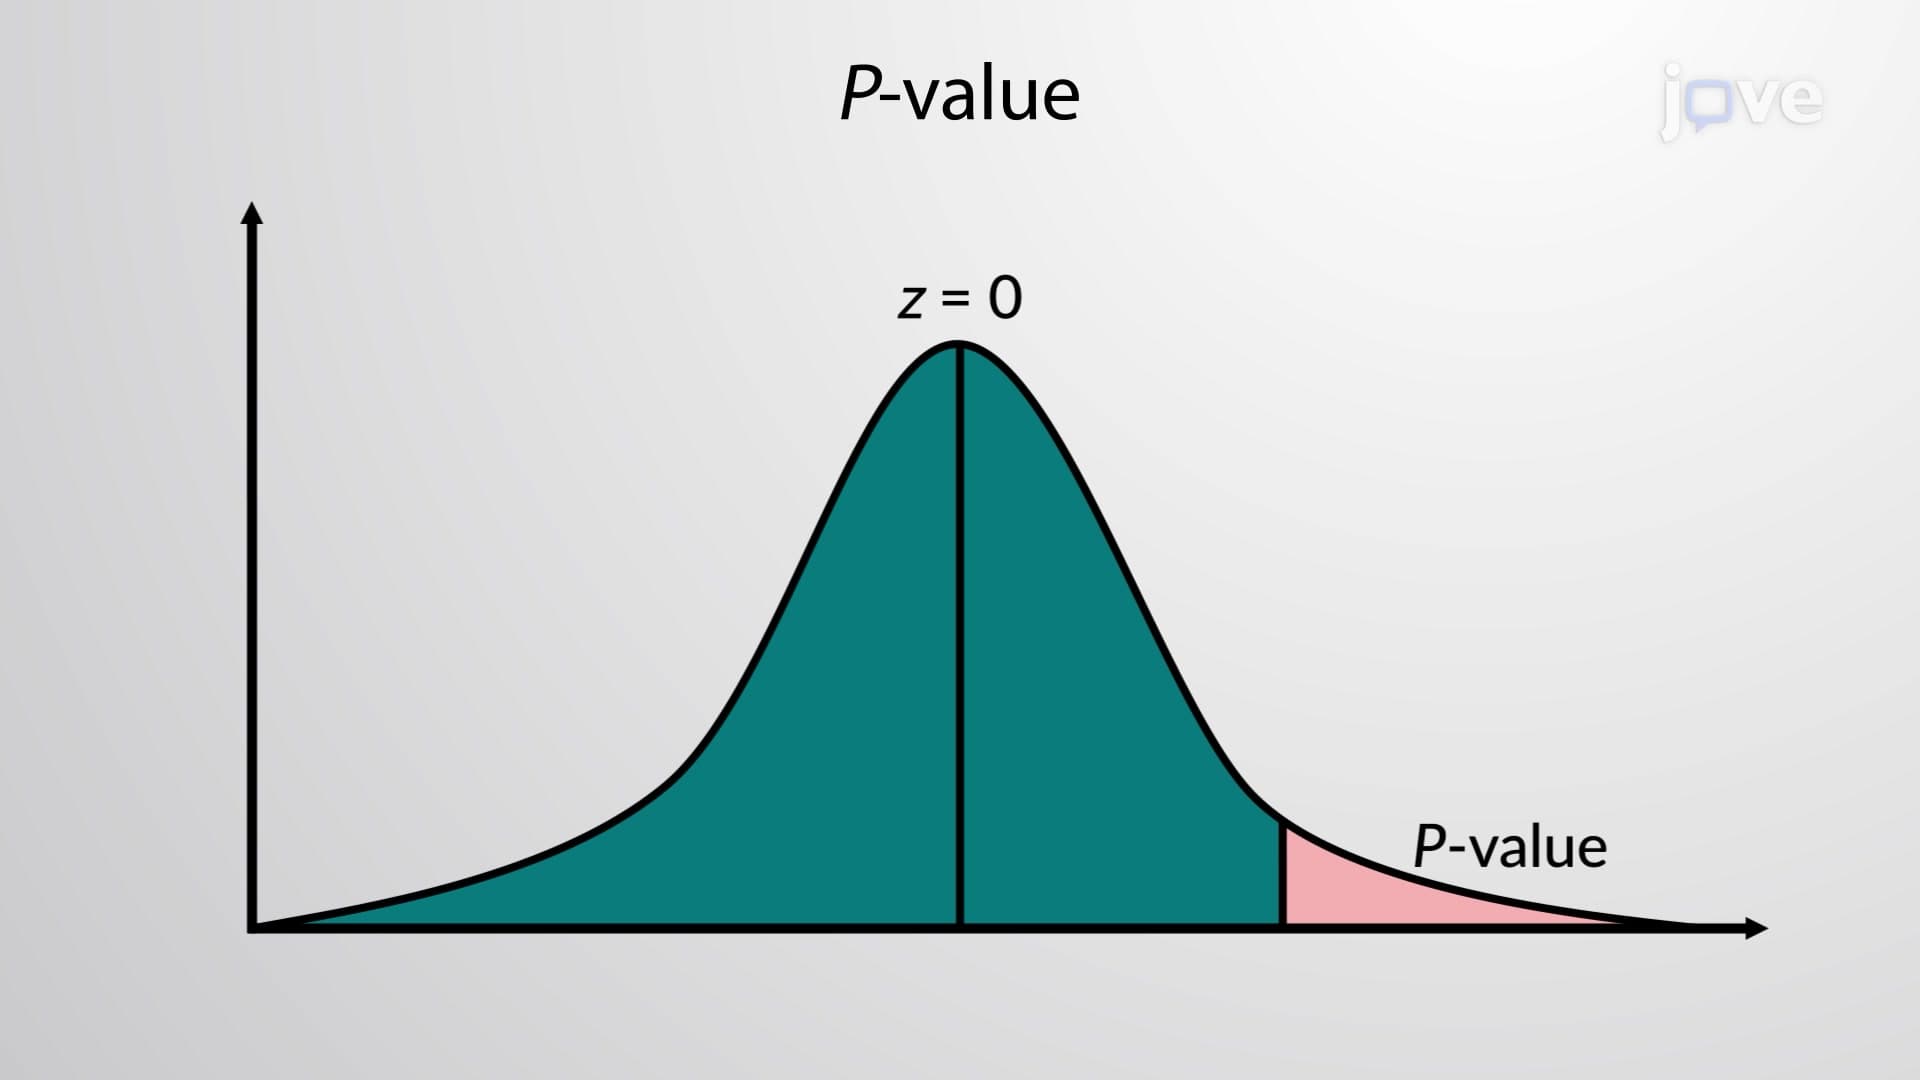
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 01:12
Observational Learning
 01:06
Collisions in Multiple Dimensions: Problem Solving
A small car of mass 1,200 kg traveling east at 60 km/h collides at an intersection with a truck of mass 3,000 kg traveling due north at 40 km/h. The two vehicles are locked together. What is the...
 01:06
Divergence and Stokes' Theorems
 01:24
Reinforcement Schedules
Once a behavior is learned,...