Related Experiment Video
Updated: Oct 21, 2025
Applications of EEG Neuroimaging Data: Event-related Potentials, Spectral Power, and Multiscale Entropy
Published on: June 27, 2013
The Often-Overlooked Power of Summary Statistics in Exploratory Data Analysis: Comparison of Pattern Recognition
Tahereh G Avval1, Behnam Moeini1, Victoria Carver1
1Department of Chemistry and Biochemistry, Brigham Young University, C100 BNSN, Provo, Utah 84602, United States.

Abstract:
Unsupervised exploratory data analysis (EDA) is often the first step in understanding complex data sets. While summary statistics are among the most efficient and convenient tools for exploring and describing sets of data, they are often overlooked in EDA. In this paper, we show multiple case studies that compare the performance, including clustering, of a series of summary statistics in EDA. The summary statistics considered here are pattern recognition entropy (PRE), the mean, standard deviation (STD), 1-norm, range, sum of squares (SSQ), and X4, which are compared with principal component analysis (PCA), multivariate curve resolution (MCR), and/or cluster analysis. PRE and the other summary statistics are direct methods for analyzing data-they are not factor-based approaches. To quantify the performance of summary statistics, we use the concept of the "critical pair," which is employed in chromatography. The data analyzed here come from different analytical methods. Hyperspectral images, including one of a biological material, are also analyzed. In general, PRE outperforms the other summary statistics, especially in image analysis, although a suite of summary statistics is useful in exploring complex data sets. While PRE results were generally comparable to those from PCA and MCR, PRE is easier to apply. For example, there is no need to determine the number of factors that describe a data set. Finally, we introduce the concept of divided spectrum-PRE (DS-PRE) as a new EDA method. DS-PRE increases the discrimination power of PRE. We also show that DS-PRE can be used to provide the inputs for the k-nearest neighbor (kNN) algorithm. We recommend PRE and DS-PRE as rapid new tools for unsupervised EDA.
Related Concept Videos
 01:10
Review and Preview
Percentiles are a type of fractile that partition data into...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:04
Significance Testing: Overview
 01:28
Introduction to Nonparametric Statistics
One of...
 01:08
Determination of Expected Frequency
 01:04
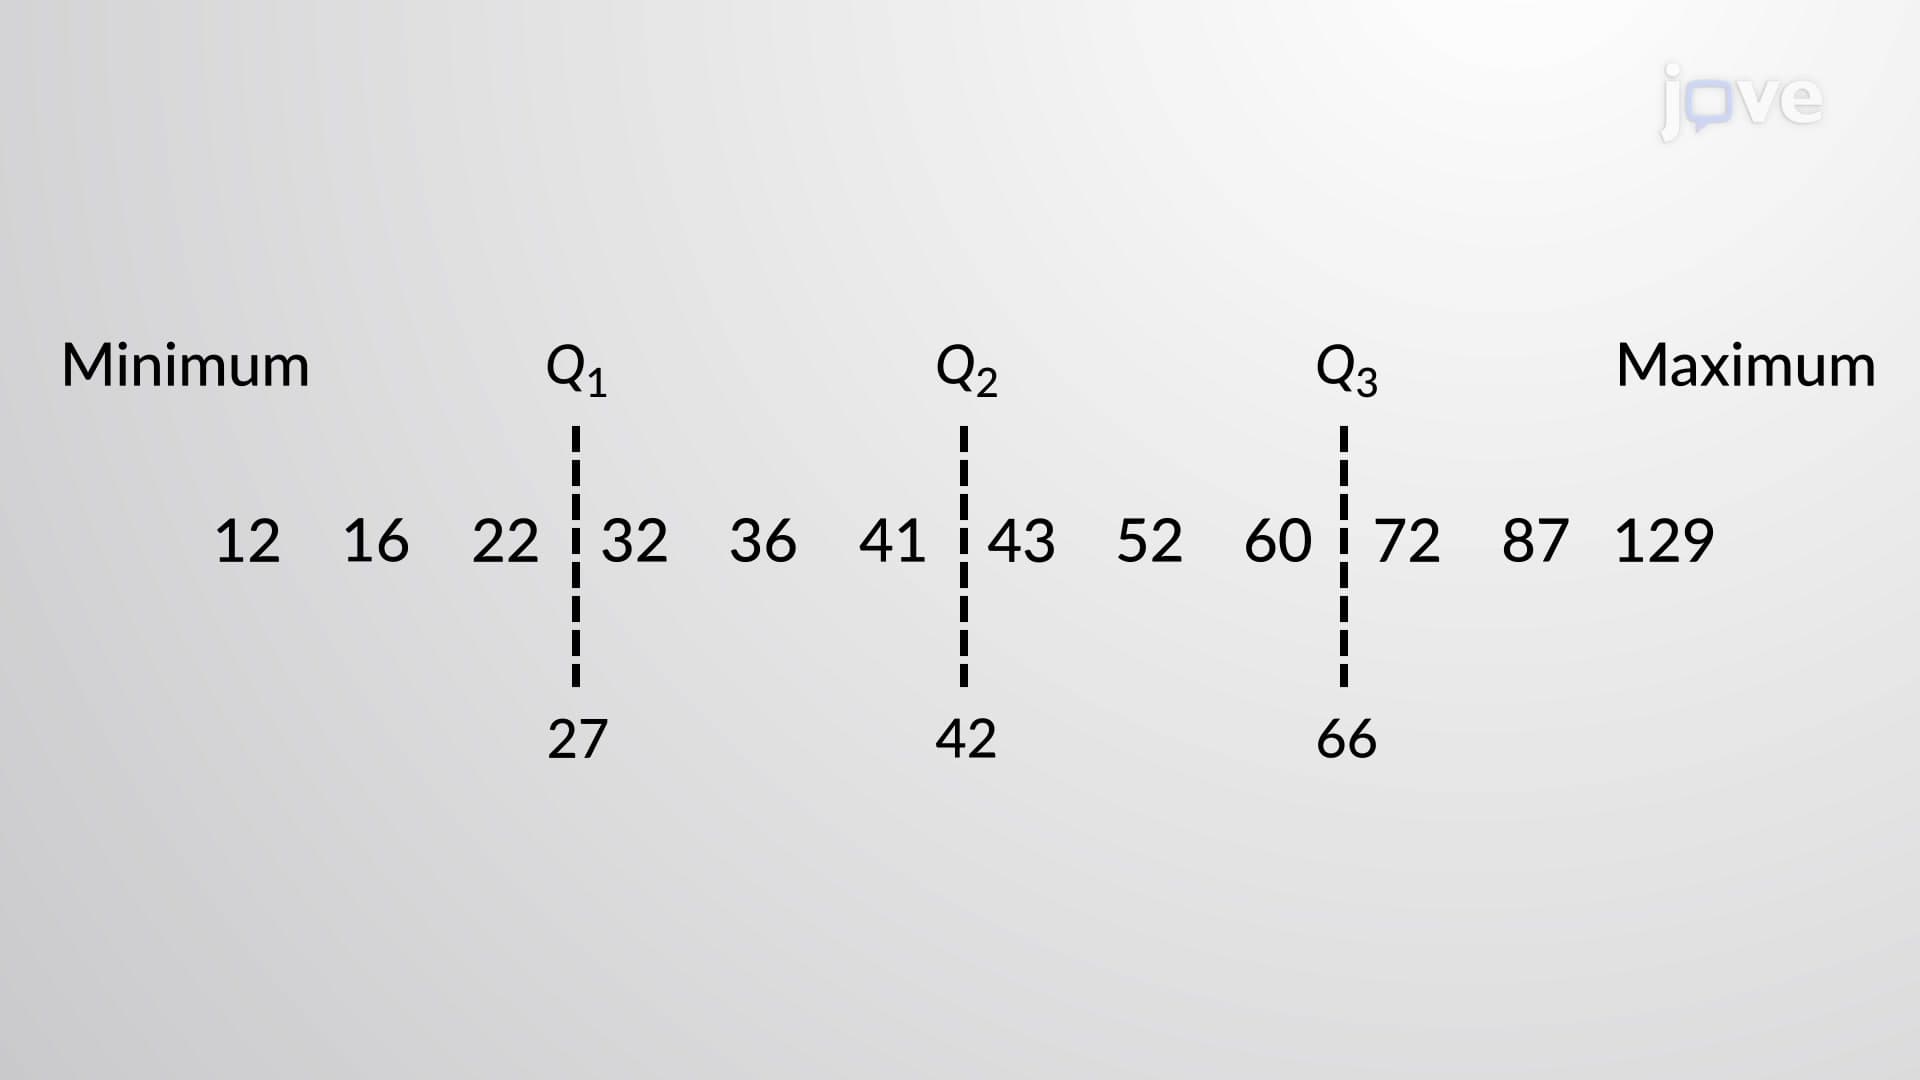
5-Number Summary
In a box plot, the minimum and maximum data values represent the lower and upper whiskers in the graph, and the median is designated as the center of the box in the chart. The first quartile and third...