Related Experiment Video
Updated: Oct 17, 2025

Establishing a Competing Risk Regression Nomogram Model for Survival Data
Published on: October 23, 2020
Estimation of the risk of work-related accidents for underground hard coal mine workers by logistic regression
1Department of Mining Engineering, Konya Technical University, Turkey.

Abstract:
Coal mining has the most risk in all of the mining sectors. Hence, in this sector, most work accidents encountered are intensive. The demographic characteristics of workers affect the occurrence of occupational accidents. This study aims to develop an equation that predicts workday loss by analyzing the relationship between workers' demographic characteristics and having an accident with workday loss. In this study, work-related accidents between 2014 and 2019 in underground hard coal mines in Turkey were analyzed using logistic regression analysis. An equation is derived that estimates the workday loss with the characteristics of workers in hard coal mines. With the equation derived in this study, employers can determine the potential for work accidents according to the demographic characteristics of the workers and serious work accidents will be prevented. Therefore, proactive solutions can be produced by applying the methods used in this study to different industries.
More Related Videos
 07:15
Machine Learning Algorithms for Early Detection of Bone Metastases in an Experimental Rat Model
Published on: August 16, 2020
 04:09
Predicting Treatment Response to Image-Guided Therapies Using Machine Learning: An Example for Trans-Arterial Treatment of Hepatocellular Carcinoma
Published on: October 10, 2018
Related Concept Videos
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:11
Hazard Rate
 01:19
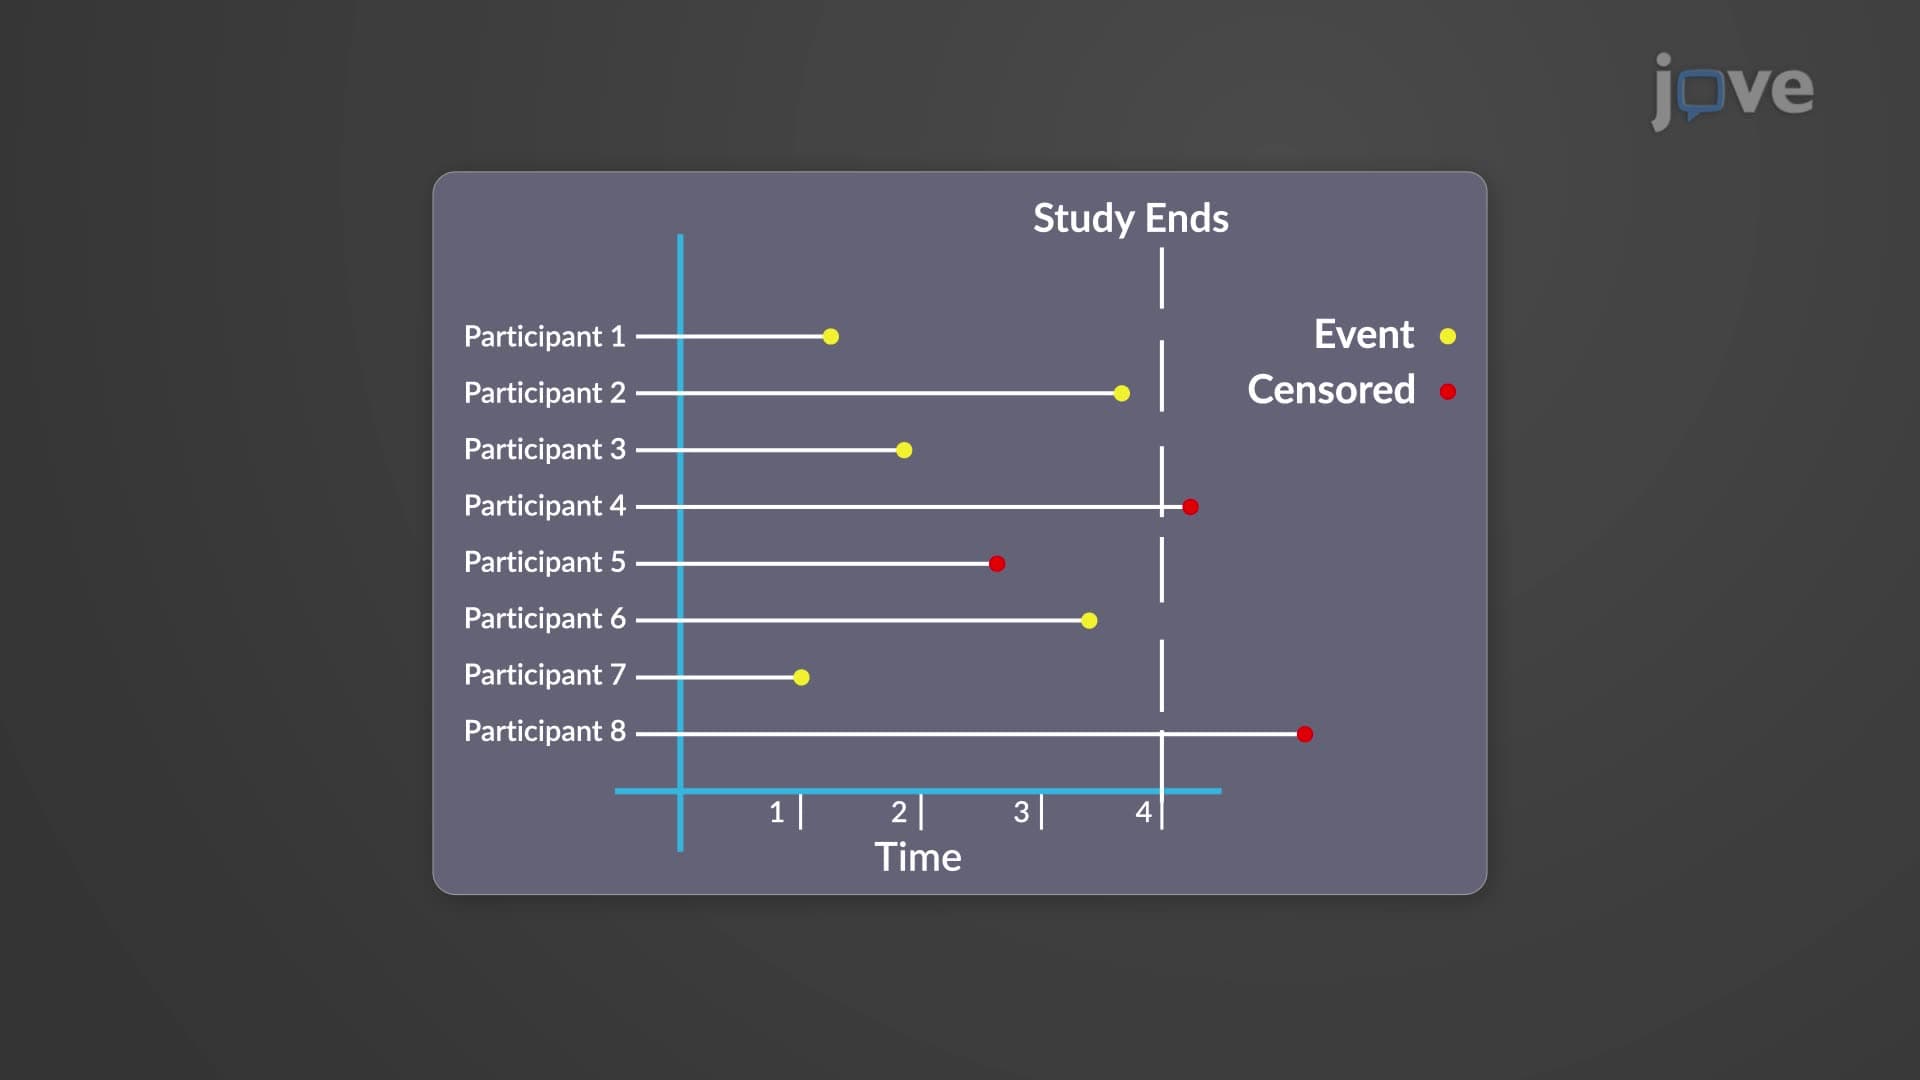
The Mantel-Cox Log-Rank Test
 01:08
Determination of Expected Frequency
 01:20
Comparing the Survival Analysis of Two or More Groups
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...