Related Experiment Video
Updated: Oct 17, 2025


Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
Novel empirical likelihood inference for the mean difference with right-censored data
Kangni Alemdjrodo1, Yichuan Zhao1
1Department of Mathematics and Statistics, 1373Georgia State University, Atlanta, GA, USA.

Abstract:
This paper focuses on comparing two means and finding a confidence interval for the difference of two means with right-censored data using the empirical likelihood method combined with the independent and identically distributed random functions representation. In the literature, some early researchers proposed empirical link-based confidence intervals for the mean difference based on right-censored data using the synthetic data approach. However, their empirical log-likelihood ratio statistic has a scaled chi-squared distribution. To avoid the estimation of the scale parameter in constructing confidence intervals, we propose an empirical likelihood method based on the independent and identically distributed representation of Kaplan-Meier weights involved in the empirical likelihood ratio. We obtain the standard chi-squared distribution. We also apply the adjusted empirical likelihood to improve coverage accuracy for small samples. In addition, we investigate a new empirical likelihood method, the mean empirical likelihood, within the framework of our study. The performances of all the empirical likelihood methods are compared via extensive simulations. The proposed empirical likelihood-based confidence interval has better coverage accuracy than those from existing methods. Finally, our findings are illustrated with a real data set.
More Related Videos


Related Concept Videos
 01:09
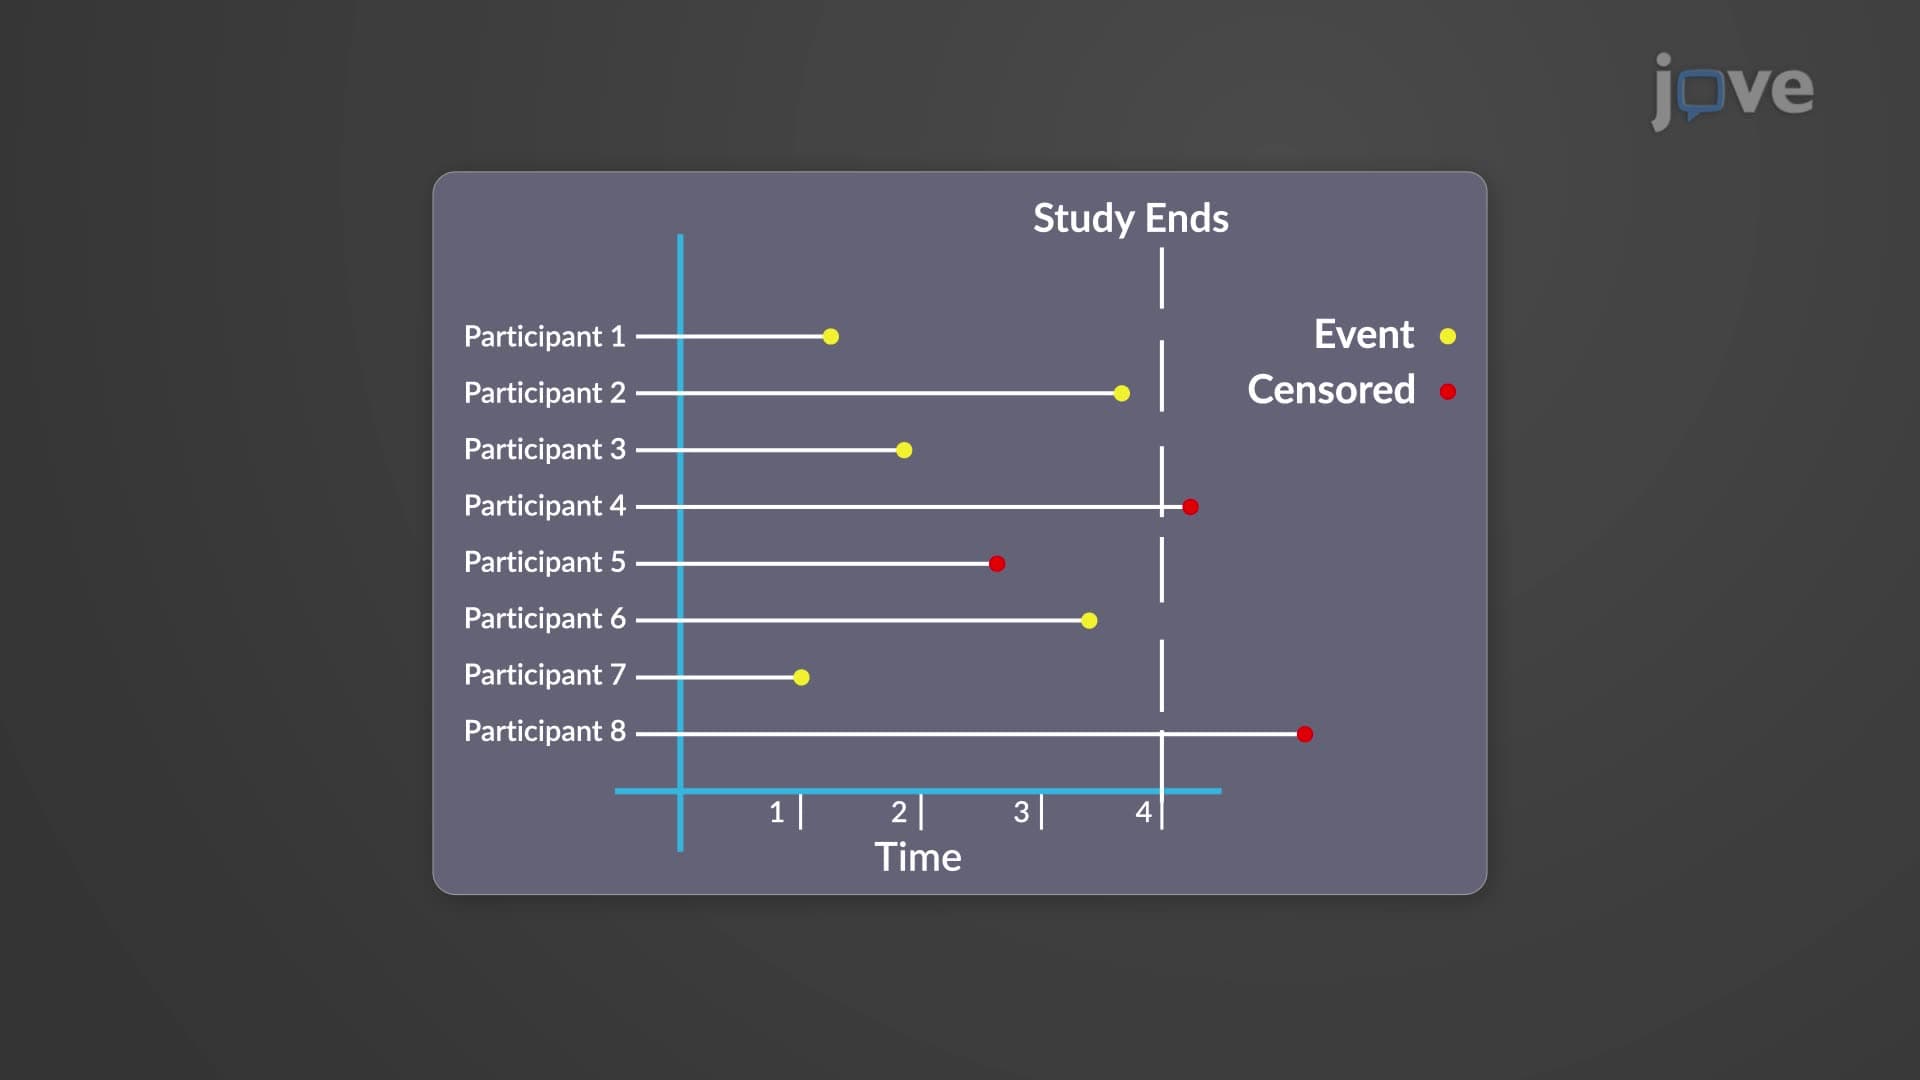
Censoring Survival Data
 01:24
Kaplan-Meier Approach
 01:19
The Mantel-Cox Log-Rank Test
 01:20
Comparing the Survival Analysis of Two or More Groups
 01:21
Testing a Claim about Mean: Unknown Population SD
Estimating a population mean requires the samples to be approximately normally distributed. The data should be collected from the randomly selected samples having no sampling bias. There is no specific requirement for sample size. But if the sample size is less than 30, and we don't know the population standard deviation, a different approach is used;...
 01:11
Testing a Claim about Mean: Known Population SD
Estimating a population mean requires the samples to be distributed normally. The data should be collected from the randomly selected samples having no sampling bias. The sample size needed to be higher than 30, and most importantly, the population standard deviation should be already known.
In most realistic situations, the population standard deviation is often unknown, but in rare circumstances, when it...