Related Experiment Video
Updated: Oct 16, 2025

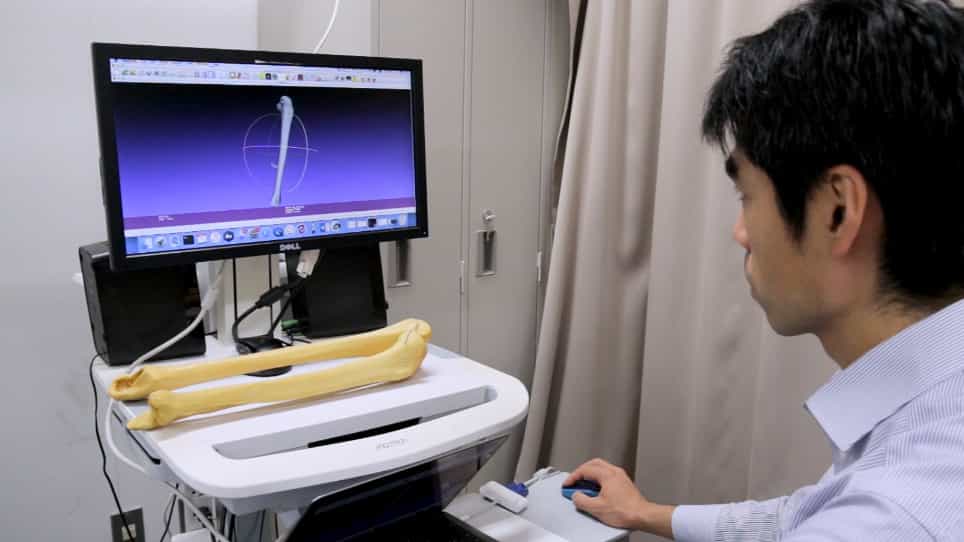
3D Printing Model of a Patient's Specific Lumbar Vertebra
Published on: April 14, 2023
Spine-transformers: Vertebra labeling and segmentation in arbitrary field-of-view spine CTs via 3D transformers
Rong Tao1, Wenyong Liu2, Guoyan Zheng1
1Institute of Medical Robotics, School of Biomedical Engineering, Shanghai Jiao Tong University, No.800 Dongchuan Road, Shanghai 200240, China.

Abstract:
In this paper, we address the problem of fully automatic labeling and segmentation of 3D vertebrae in arbitrary Field-Of-View (FOV) CT images. We propose a deep learning-based two-stage solution to tackle these two problems. More specifically, in the first stage, the challenging vertebra labeling problem is solved via a novel transformers-based 3D object detector that views automatic detection of vertebrae in arbitrary FOV CT scans as a one-to-one set prediction problem. The main components of the new method, called Spine-Transformers, are a one-to-one set based global loss that forces unique predictions and a light-weighted 3D transformer architecture equipped with a skip connection and learnable positional embeddings for encoder and decoder, respectively. We additionally propose an inscribed sphere-based object detector to replace the regular box-based object detector for a better handling of volume orientation variations. Our method reasons about the relationships of different levels of vertebrae and the global volume context to directly infer all vertebrae in parallel. In the second stage, the segmentation of the identified vertebrae and the refinement of the detected centers are then done by training one single multi-task encoder-decoder network for all vertebrae as the network does not need to identify which vertebra it is working on. The two tasks share a common encoder path but with different decoder paths. Comprehensive experiments are conducted on two public datasets and one in-house dataset. The experimental results demonstrate the efficacy of the present approach.