Related Experiment Video
Updated: Oct 13, 2025


A Psychophysics Paradigm for the Collection and Analysis of Similarity Judgments
Published on: March 1, 2022
Weighting schemes and incomplete data: A generalized Bayesian framework for chance-corrected interrater agreement
Rutger van Oest1, Jeffrey M Girard2
1Department of Marketing, BI Norwegian Business School.

Abstract:
Van Oest (2019) developed a framework to assess interrater agreement for nominal categories and complete data. We generalize this framework to all four situations of nominal or ordinal categories and complete or incomplete data. The mathematical solution yields a chance-corrected agreement coefficient that accommodates any weighting scheme for penalizing rater disagreements and any number of raters and categories. By incorporating Bayesian estimates of the category proportions, the generalized coefficient also captures situations in which raters classify only subsets of items; that is, incomplete data. Furthermore, this coefficient encompasses existing chance-corrected agreement coefficients: the S-coefficient, Scott's pi, Fleiss' kappa, and Van Oest's uniform prior coefficient, all augmented with a weighting scheme and the option of incomplete data. We use simulation to compare these nested coefficients. The uniform prior coefficient tends to perform best, in particular, if one category has a much larger proportion than others. The gap with Scott's pi and Fleiss' kappa widens if the weighting scheme becomes more lenient to small disagreements and often if more item classifications are missing; missingness biases play a moderating role. The uniform prior coefficient often performs much better than the S-coefficient, but the S-coefficient sometimes performs best for small samples, missing data, and lenient weighting schemes. The generalized framework implies a new interpretation of chance-corrected weighted agreement coefficients: These coefficients estimate the probability that both raters in a pair assign an item to its correct category without guessing. Whereas Van Oest showed this interpretation for unweighted agreement, we generalize to weighted agreement. (PsycInfo Database Record (c) 2023 APA, all rights reserved).


Related Concept Videos
 00:57
Weighted Mean
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:10
Propagation of Uncertainty from Systematic Error
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:19
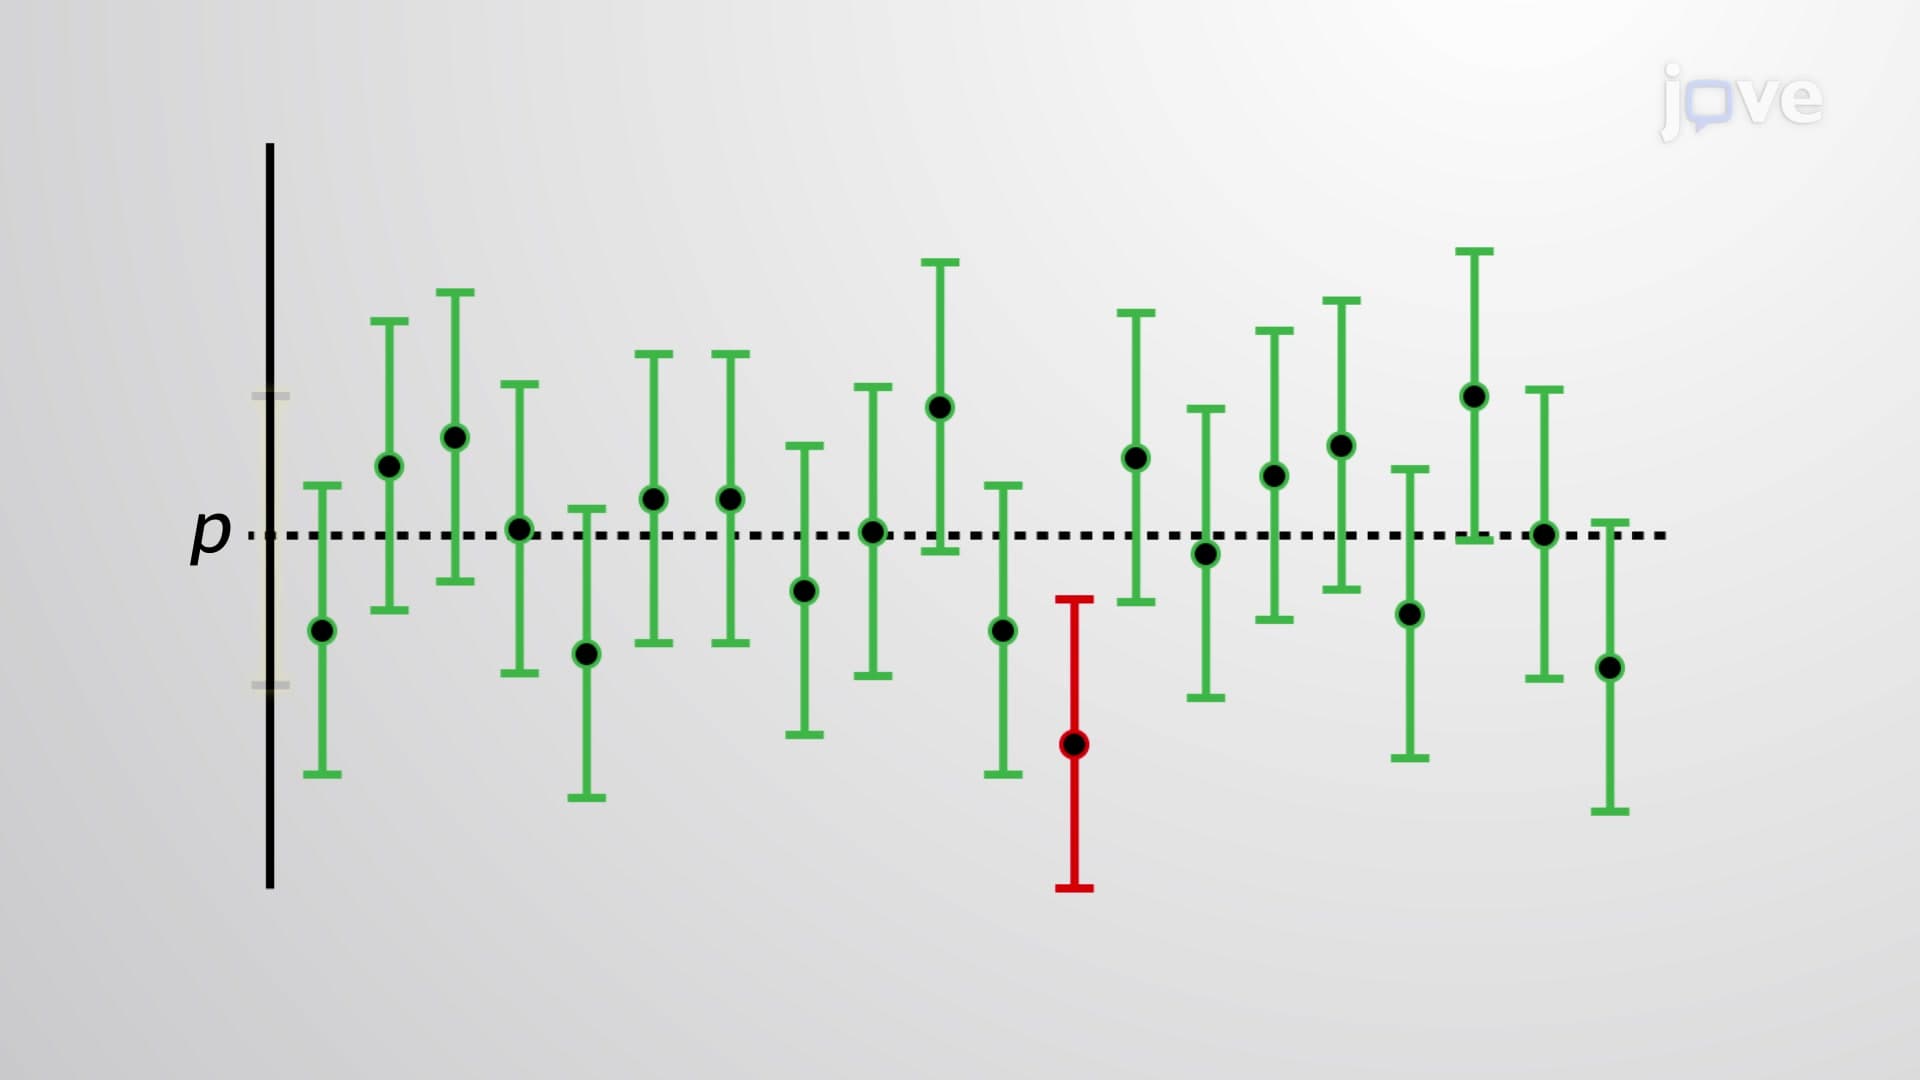
Interpretation of Confidence Intervals
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...