Related Experiment Video
Updated: Oct 13, 2025

A Method of Trigonometric Modelling of Seasonal Variation Demonstrated with Multiple Sclerosis Relapse Data
Published on: December 9, 2015
Time Series Segmentation Based on Stationarity Analysis to Improve New Samples Prediction
Ricardo Petri Silva1, Bruno Bogaz Zarpelão2, Alberto Cano3
1Department of Electrical Engineering, State University of Londrina, Londrina 86057-970, Brazil.

Abstract:
A wide range of applications based on sequential data, named time series, have become increasingly popular in recent years, mainly those based on the Internet of Things (IoT). Several different machine learning algorithms exploit the patterns extracted from sequential data to support multiple tasks. However, this data can suffer from unreliable readings that can lead to low accuracy models due to the low-quality training sets available. Detecting the change point between high representative segments is an important ally to find and thread biased subsequences. By constructing a framework based on the Augmented Dickey-Fuller (ADF) test for data stationarity, two proposals to automatically segment subsequences in a time series were developed. The former proposal, called Change Detector segmentation, relies on change detection methods of data stream mining. The latter, called ADF-based segmentation, is constructed on a new change detector derived from the ADF test only. Experiments over real-file IoT databases and benchmarks showed the improvement provided by our proposals for prediction tasks with traditional Autoregressive integrated moving average (ARIMA) and Deep Learning (Long short-term memory and Temporal Convolutional Networks) methods. Results obtained by the Long short-term memory predictive model reduced the relative prediction error from 1 to 0.67, compared to time series without segmentation.

Related Concept Videos
 00:54
Time-Series Graph
 01:11
Sampling Continuous Time Signal
In the...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:16
Basic Discrete Time Signals
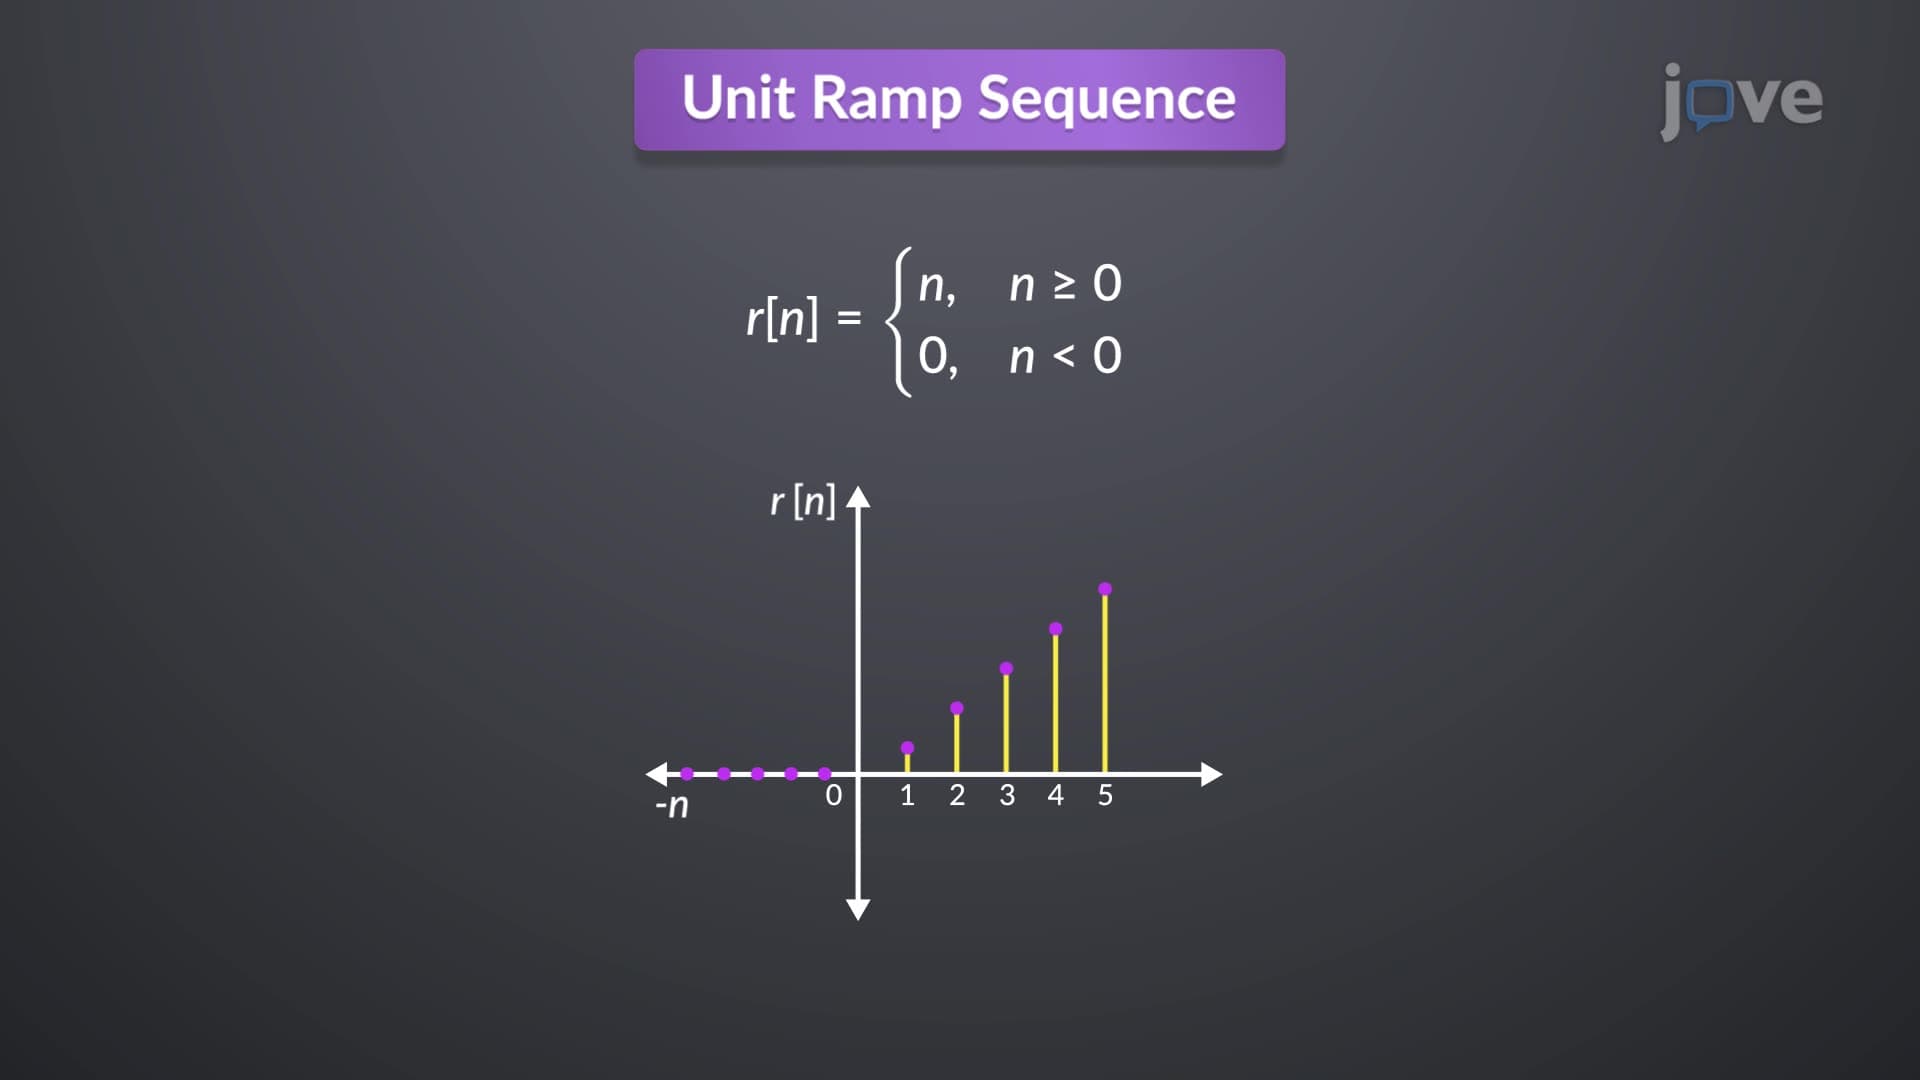
The unit impulse or sample sequence is mathematically expressed as zero for all n values except at n=0, where it is one. The unit impulse sequence, denoted by δ(n), is the first difference of the unit step sequence, while the unit step sequence u(n) is...
 01:15
Sampling Theorem