Related Experiment Video
Updated: Oct 13, 2025
An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
Fitting and Cross-Validating Cox Models to Censored Big Data With Missing Values Using Extensions of Partial Least
Frédéric Bertrand1,2, Myriam Maumy-Bertrand1,2
1LIST3N, Université de Technologie de Troyes, Troyes, France.

Abstract:
Fitting Cox models in a big data context -on a massive scale in terms of volume, intensity, and complexity exceeding the capacity of usual analytic tools-is often challenging. If some data are missing, it is even more difficult. We proposed algorithms that were able to fit Cox models in high dimensional settings using extensions of partial least squares regression to the Cox models. Some of them were able to cope with missing data. We were recently able to extend our most recent algorithms to big data, thus allowing to fit Cox model for big data with missing values. When cross-validating standard or extended Cox models, the commonly used criterion is the cross-validated partial loglikelihood using a naive or a van Houwelingen scheme -to make efficient use of the death times of the left out data in relation to the death times of all the data. Quite astonishingly, we will show, using a strong simulation study involving three different data simulation algorithms, that these two cross-validation methods fail with the extensions, either straightforward or more involved ones, of partial least squares regression to the Cox model. This is quite an interesting result for at least two reasons. Firstly, several nice features of PLS based models, including regularization, interpretability of the components, missing data support, data visualization thanks to biplots of individuals and variables -and even parsimony or group parsimony for Sparse partial least squares or sparse group SPLS based models, account for a common use of these extensions by statisticians who usually select their hyperparameters using cross-validation. Secondly, they are almost always featured in benchmarking studies to assess the performance of a new estimation technique used in a high dimensional or big data context and often show poor statistical properties. We carried out a vast simulation study to evaluate more than a dozen of potential cross-validation criteria, either AUC or prediction error based. Several of them lead to the selection of a reasonable number of components. Using these newly found cross-validation criteria to fit extensions of partial least squares regression to the Cox model, we performed a benchmark reanalysis that showed enhanced performances of these techniques. In addition, we proposed sparse group extensions of our algorithms and defined a new robust measure based on the Schmid score and the R coefficient of determination for least absolute deviation: the integrated R Schmid Score weighted. The R-package used in this article is available on the CRAN, http://cran.r-project.org/web/packages/plsRcox/index.html. The R package bigPLS will soon be available on the CRAN and, until then, is available on Github https://github.com/fbertran/bigPLS.
More Related Videos
 04:35
Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
 05:16
Cutoff Value of Phase Angle by Bioelectrical Impedance Analysis at Admission as a Prognostic Factor in Patients with Acute Heart Failure
Published on: June 10, 2025
Related Concept Videos
 01:09
Censoring Survival Data
 01:14
Parametric Survival Analysis: Weibull and Exponential Methods
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
 01:17
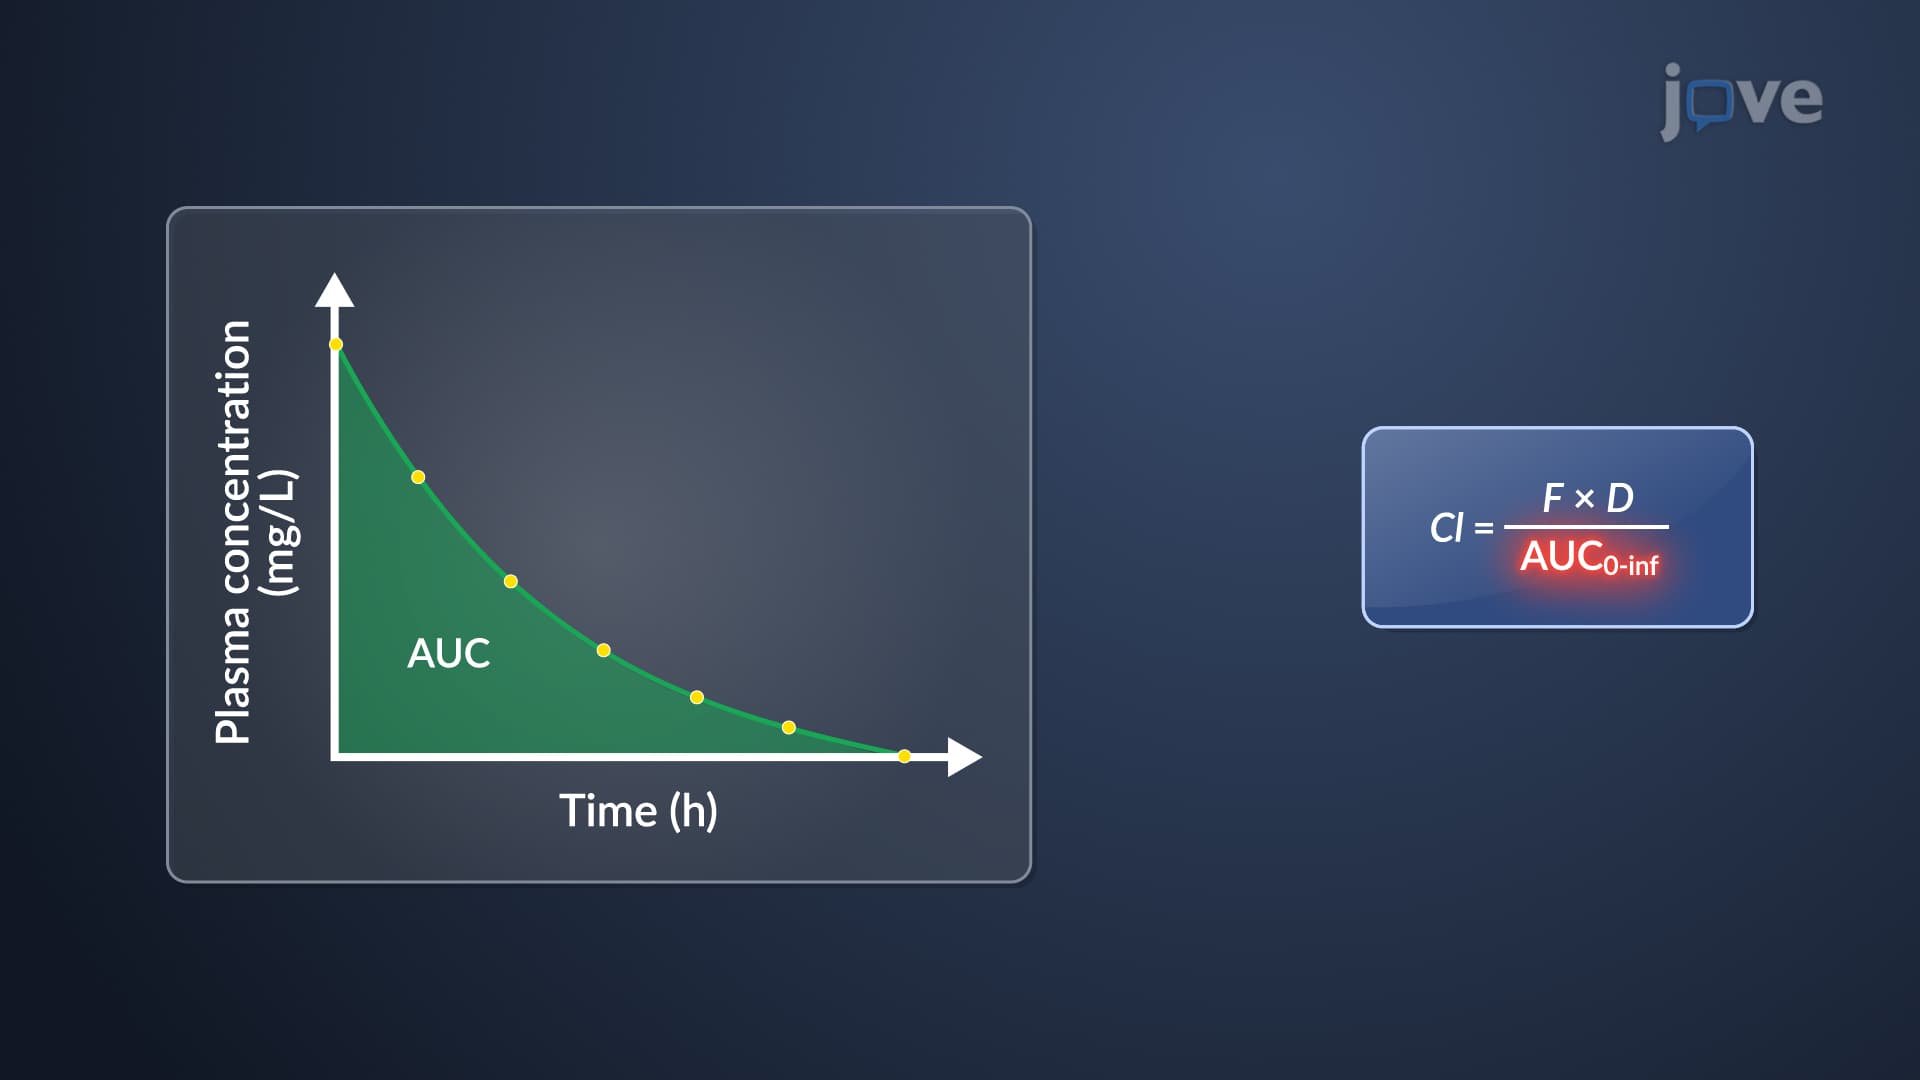
Clearance Models: Noncompartmental Models
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:09
Truncation in Survival Analysis
Left truncation occurs when individuals who experienced the event of interest before a certain time are not included in the study. This is often due to a "delayed entry" into the study where only those who survive until a certain entry point are...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...