Related Experiment Video
Updated: Oct 3, 2025
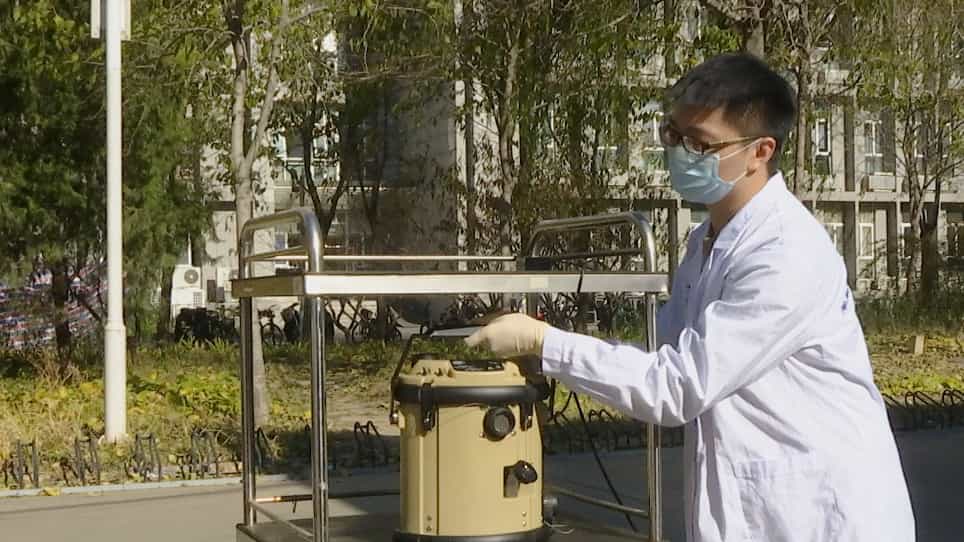

Composition and Distribution Analysis of Bioaerosols Under Different Environmental Conditions
Published on: January 7, 2019
Seasonal prediction of daily PM2.5 concentrations with interpretable machine learning: a case study of Beijing, China
Yafei Wu1,2,3, Shaowu Lin1,2,3, Kewei Shi1,3
1The State Key Laboratory of Molecular Vaccine and Molecular Diagnostics, School of Public Health, Xiamen University, Xiamen, 361102, China.

Abstract:
Machine learning (ML) has shown high predictive ability in environmental research. Accurate estimation of daily PM2.5 concentrations is a prerequisite to address environmental public health issues. However, studies on the interpretability of ML algorithms were limited. In this study, we aimed to estimate the daily concentrations of PM2.5 at a seasonal level, and to understand the potential mechanisms of ML algorithms' decisions with SHapley Additive exPlanations (SHAP). Daily ground PM2.5 concentrations and meteorological data were obtained from the Beijing Municipal Ecological and Environmental Monitoring Center, and China Meteorological Data Service Centre between December 2013 and 2019 November. We calculated correlation coefficient and variance inflation factor (VIF) to eliminate the variables with collinearity, and recursive feature elimination (RFE) was further used to selected more important predictors. A series of ML algorithms, including linear regression, the variants of linear regression (Ridge, Lasso, Elasticnet), decision tree (DT), k-nearest neighbor (KNN), support vector regression (SVR), ensemble methods (random forest: RF, eXtreme Gradient Boosting: XGBoost), and deep learning (long short-term memory network: LSTM), were developed to estimate seasonal-level daily PM2.5 concentrations. A 10-fold cross validation was used to tune hyperparameters, and root mean square error (RMSE), mean absolute error (MAE), ratio of performance to deviation (RPD), and Lin's concordance correlation coefficient (LCCC) were used to evaluate models' performance. SHAP was performed for local and global interpretability analysis. The results showed that the distribution of PM2.5 concentrations in Beijing showed obvious seasonal patterns. A total of five variables (Precipitation, Mean wind speed, Sunshine duration, Mean surface temperature, Mean relative humidity) were selected for final prediction. LSTM showed much higher accuracy than other traditional ML models, achieved the smallest RMSE of 19.58 µg/m3 and MAE of 15.11 µg/m3. In terms of selected data set, there was acceptable (LCCC = 0.41 ~ 0.52) agreement and accuracy (RPD = 0.97 ~ 1.92) for LSTM. The SHAP analyses revealed that the meteorological factors had different influences in specific predictions, and the complex interactions were also illustrated. These results enhance our understanding of meteorological factors-PM2.5 relationships and explain the mechanisms of ML algorithms' decisions.
More Related Videos
Related Concept Videos
 01:18
Steps in Outbreak Investigation
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as: