Related Experiment Video
Updated: Oct 3, 2025
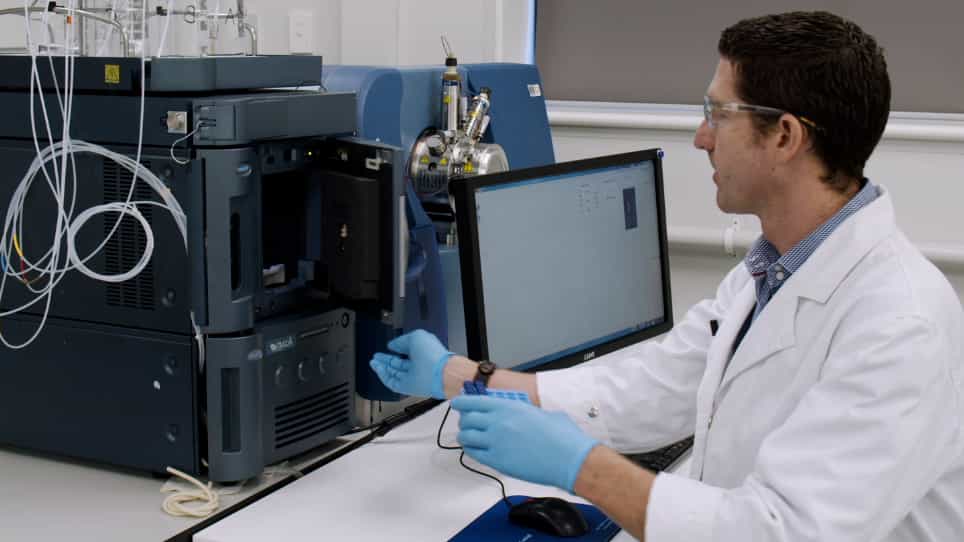

Untargeted Liquid Chromatography-Mass Spectrometry-Based Metabolomics Analysis of Wheat Grain
Published on: March 13, 2020
Evaluation of Random Forests (RF) for Regional and Local-Scale Wheat Yield Prediction in Southeast Australia
Alexis Pang1, Melissa W L Chang1,2, Yang Chen1,3
1School of Agriculture and Food, Faculty of Veterinary and Agricultural Sciences, The University of Melbourne, Parkville 3010, Australia.

Abstract:
Wheat accounts for more than 50% of Australia's total grain production. The capability to generate accurate in-season yield predictions is important across all components of the agricultural value chain. The literature on wheat yield prediction has motivated the need for more novel works evaluating machine learning techniques such as random forests (RF) at multiple scales. This research applied a Random Forest Regression (RFR) technique to build regional and local-scale yield prediction models at the pixel level for three southeast Australian wheat-growing paddocks, each located in Victoria (VIC), New South Wales (NSW) and South Australia (SA) using 2018 yield maps from data supplied by collaborating farmers. Time-series Normalized Difference Vegetation Index (NDVI) data derived from Planet's high spatio-temporal resolution imagery, meteorological variables and yield data were used to train, test and validate the models at pixel level using Python libraries for (a) regional-scale three-paddock composite and (b) individual paddocks. The composite region-wide RF model prediction for the three paddocks performed well (R2 = 0.86, RMSE = 0.18 t ha-1). RF models for individual paddocks in VIC (R2 = 0.89, RMSE = 0.15 t ha-1) and NSW (R2 = 0.87, RMSE = 0.07 t ha-1) performed well, but moderate performance was seen for SA (R2 = 0.45, RMSE = 0.25 t ha-1). Generally, high values were underpredicted and low values overpredicted. This study demonstrated the feasibility of applying RF modeling on satellite imagery and yielded 'big data' for regional as well as local-scale yield prediction.

Related Concept Videos
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 02:16
Light Acquisition
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:19
Survival Tree
Building a Survival Tree
Constructing a...