Related Experiment Video
Updated: Oct 1, 2025
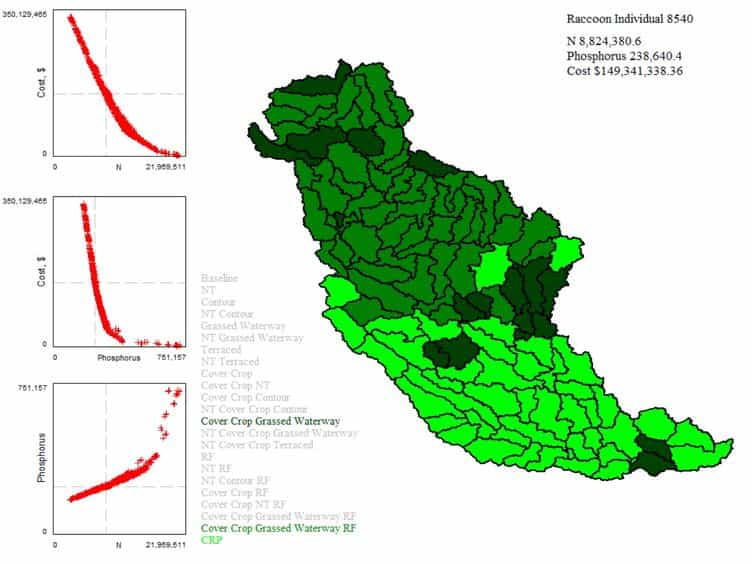

Spatial Multiobjective Optimization of Agricultural Conservation Practices using a SWAT Model and an Evolutionary Algorithm
Published on: December 9, 2012
Dataset on PGA Tour tournament entry
Inés Alegre1, Miguel A Canela1, David Pastoriza2
1IESE Business School, Spain.

Abstract:
This article describes a dataset that allows to explore the determinants and moderators of athletes' decision to enter in tournaments endowed with a monetary prize. Specifically, the dataset contains variables that describe athlete's short-term momentum (i.e., performance streak in the tournaments recently entered) and long-term momentum (i.e., performance streak in the same tournament across seasons), which permits an in-depth analysis of how past performance trajectory drives self-selection into tournaments. The dataset consists of 54,915 self-selection decisions that golfers have taken over an eleven-year period (1996-2006) when deciding to participate in PGA Tour tournaments.
Related Concept Videos
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 00:57
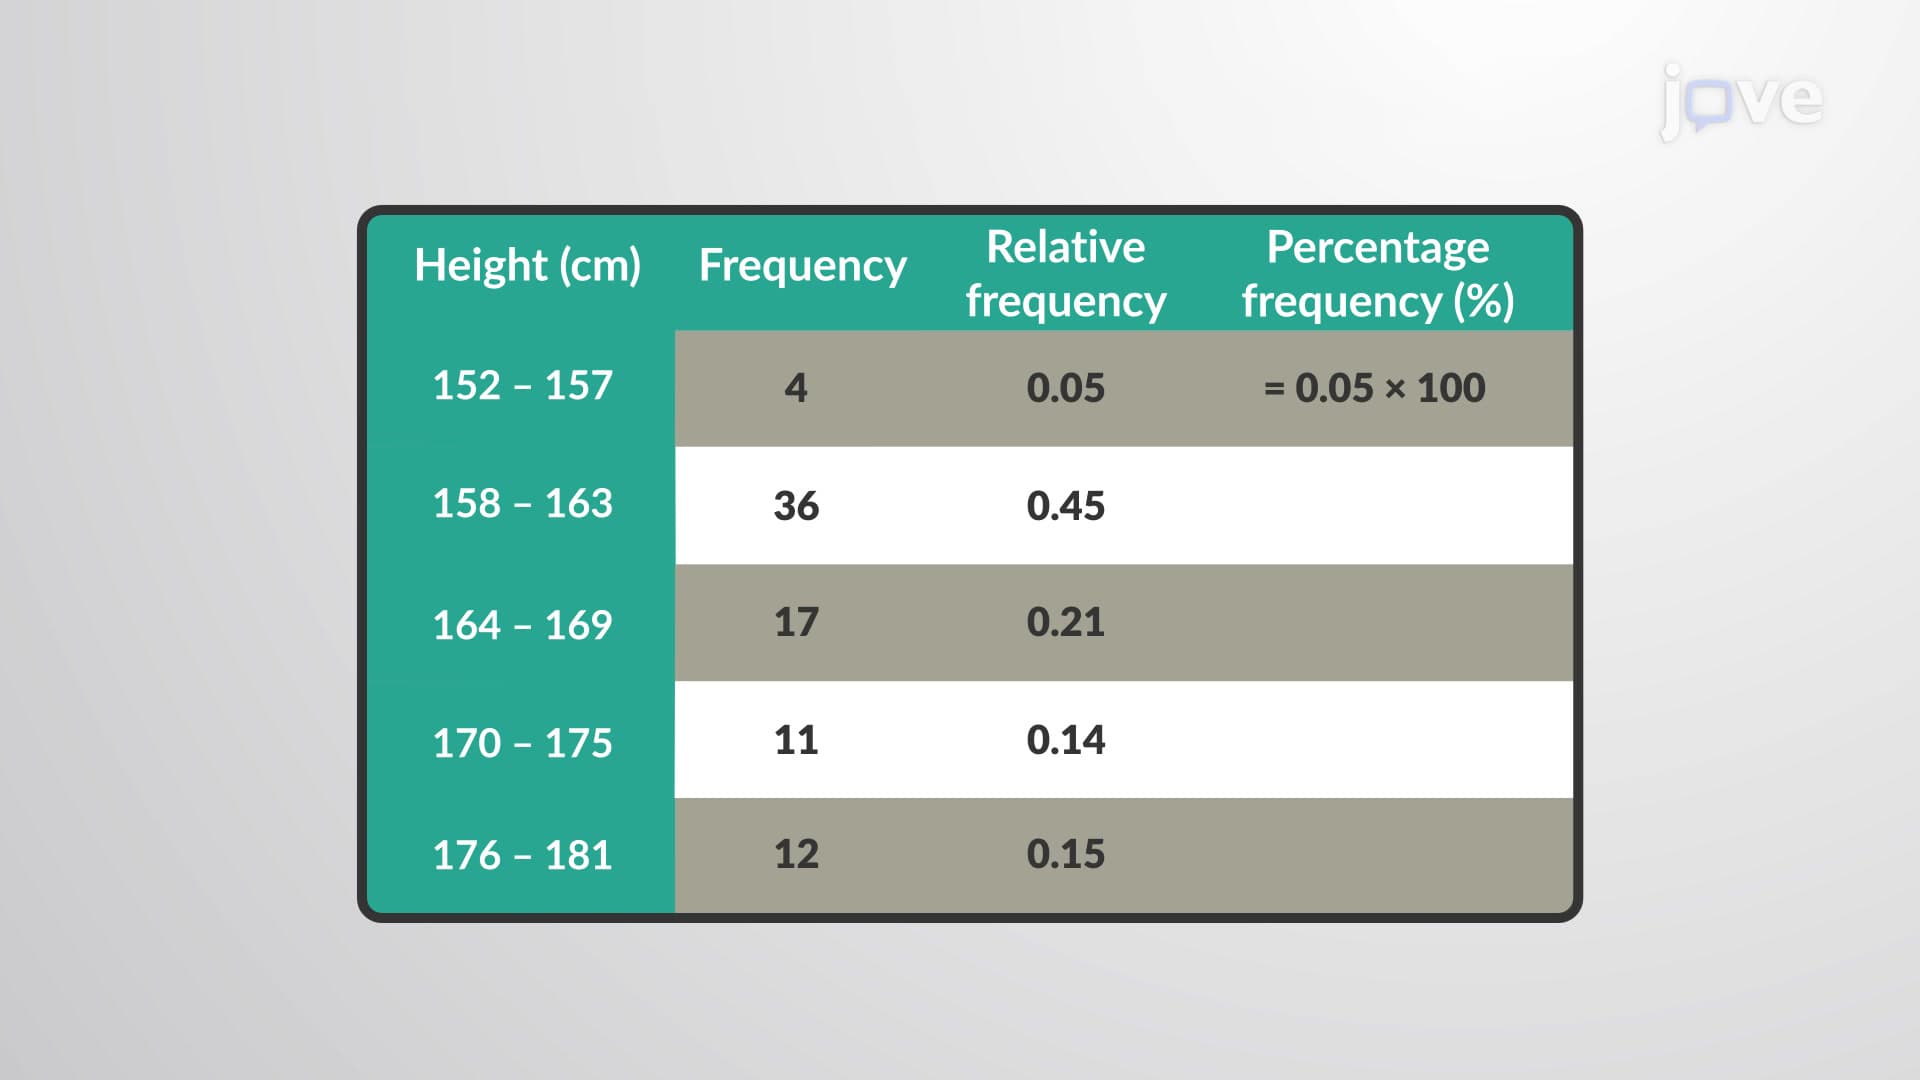
Percentage Frequency Distribution
The process of making a percentage frequency distribution involves the following few steps: note the total number of observations;...
 02:35
RACE - Rapid Amplification of cDNA Ends
 00:55
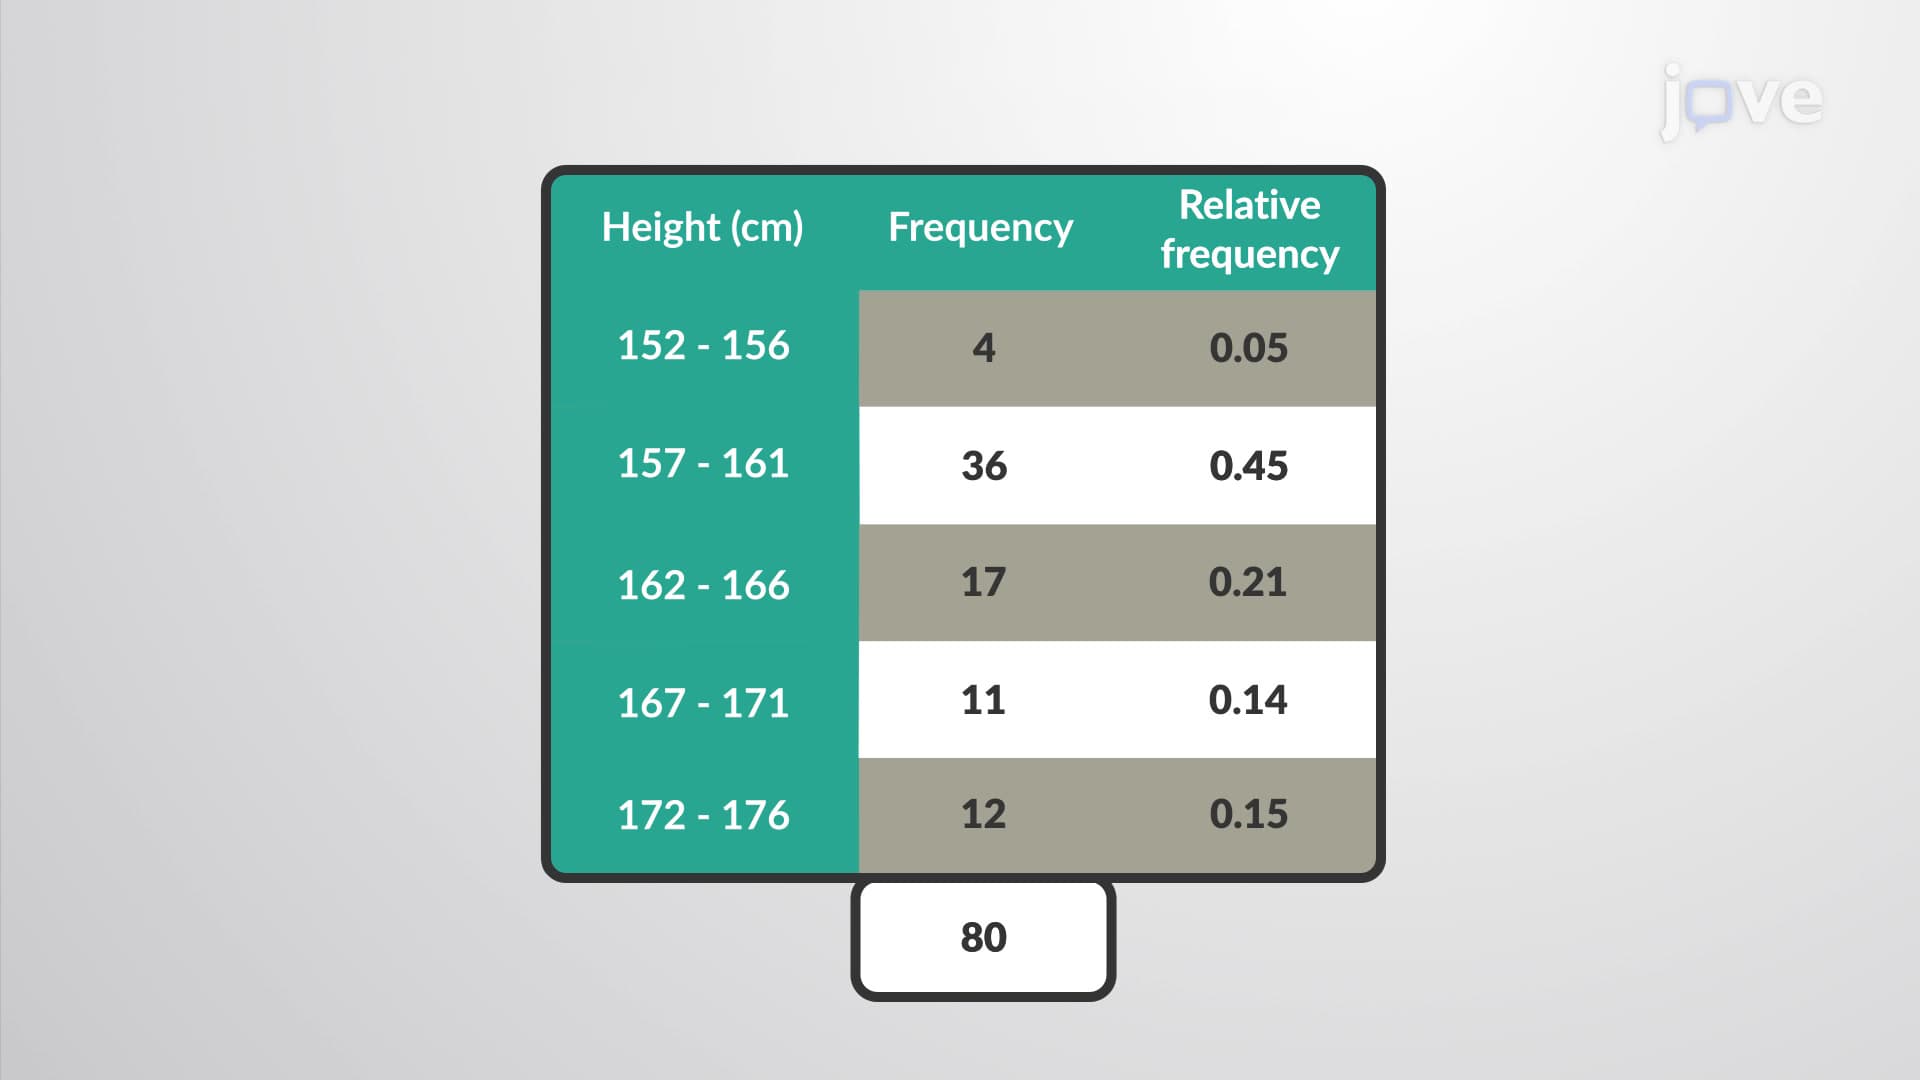
Relative Frequency Distribution
 01:29
Contingency Table
 01:15
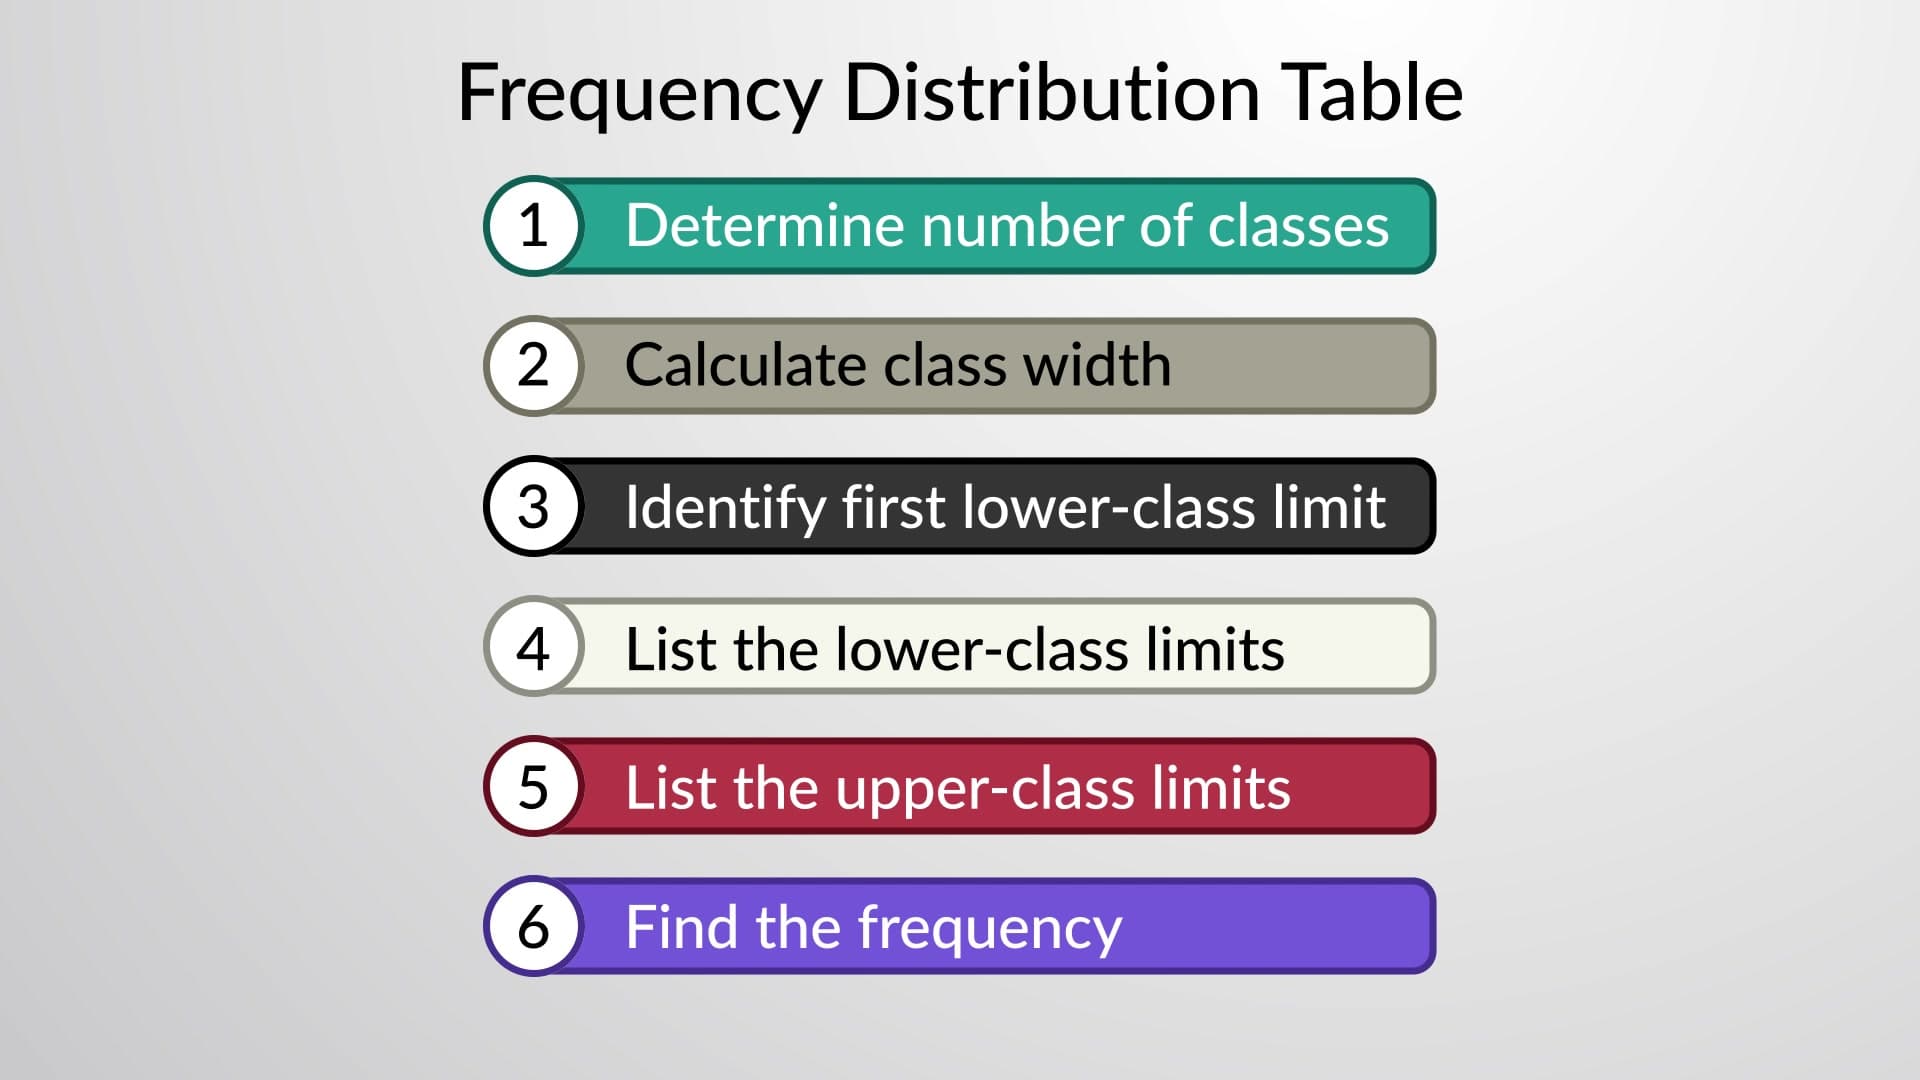
Construction of Frequency Distribution
First, make a table with two columns—one with the title of the data that needs to be organized, and the other column for frequency. [Draw a third column for tally marks if needed]. Then, take a look at the items given in the data set and decide if an ungrouped frequency distribution table or a grouped frequency distribution table would be more suitable. If there are large sets of different values, then it is...