Gene Expression Data Analysis Using Feature Weighted Robust Fuzzy c-Means Clustering
Related Experiment Video
Updated: Oct 1, 2025
Author Spotlight: Impact of Intergenic Interactions on Disease-Identifying Dark Biomarkers
Published on: March 1, 2024

Abstract:
Clustering of gene expression data has been proven to be very useful in various applications, i.e., identifying the natural structure inherent in gene expression, understanding gene functions, mining relevant information from noisy data, and understanding gene regulation. In all these applications, genes, i.e., features, play a crucial role in characterizing them into different groups. These features may be relevant, irrelevant, or redundant, but they have different contributions during the clustering process. This paper presents a novel approach by considering the effect of features during the clustering process. In the proposed method, the fuzzy c-means the objective function is modified using a weighted Euclidean distance between the features with a monotonically decreasing function. The monotonically decreasing function helps control the features' contribution during the clustering process to partition the data into more relevant clusters. The proposed approach is validated, and performance is presented in various clustering performance measures on the different standard datasets. These clustering performance measures have also been compared with multiple state-of-the-art methods.
Related Concept Videos
 00:57
Weighted Mean
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
 03:21
RNA-seq
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
 02:34
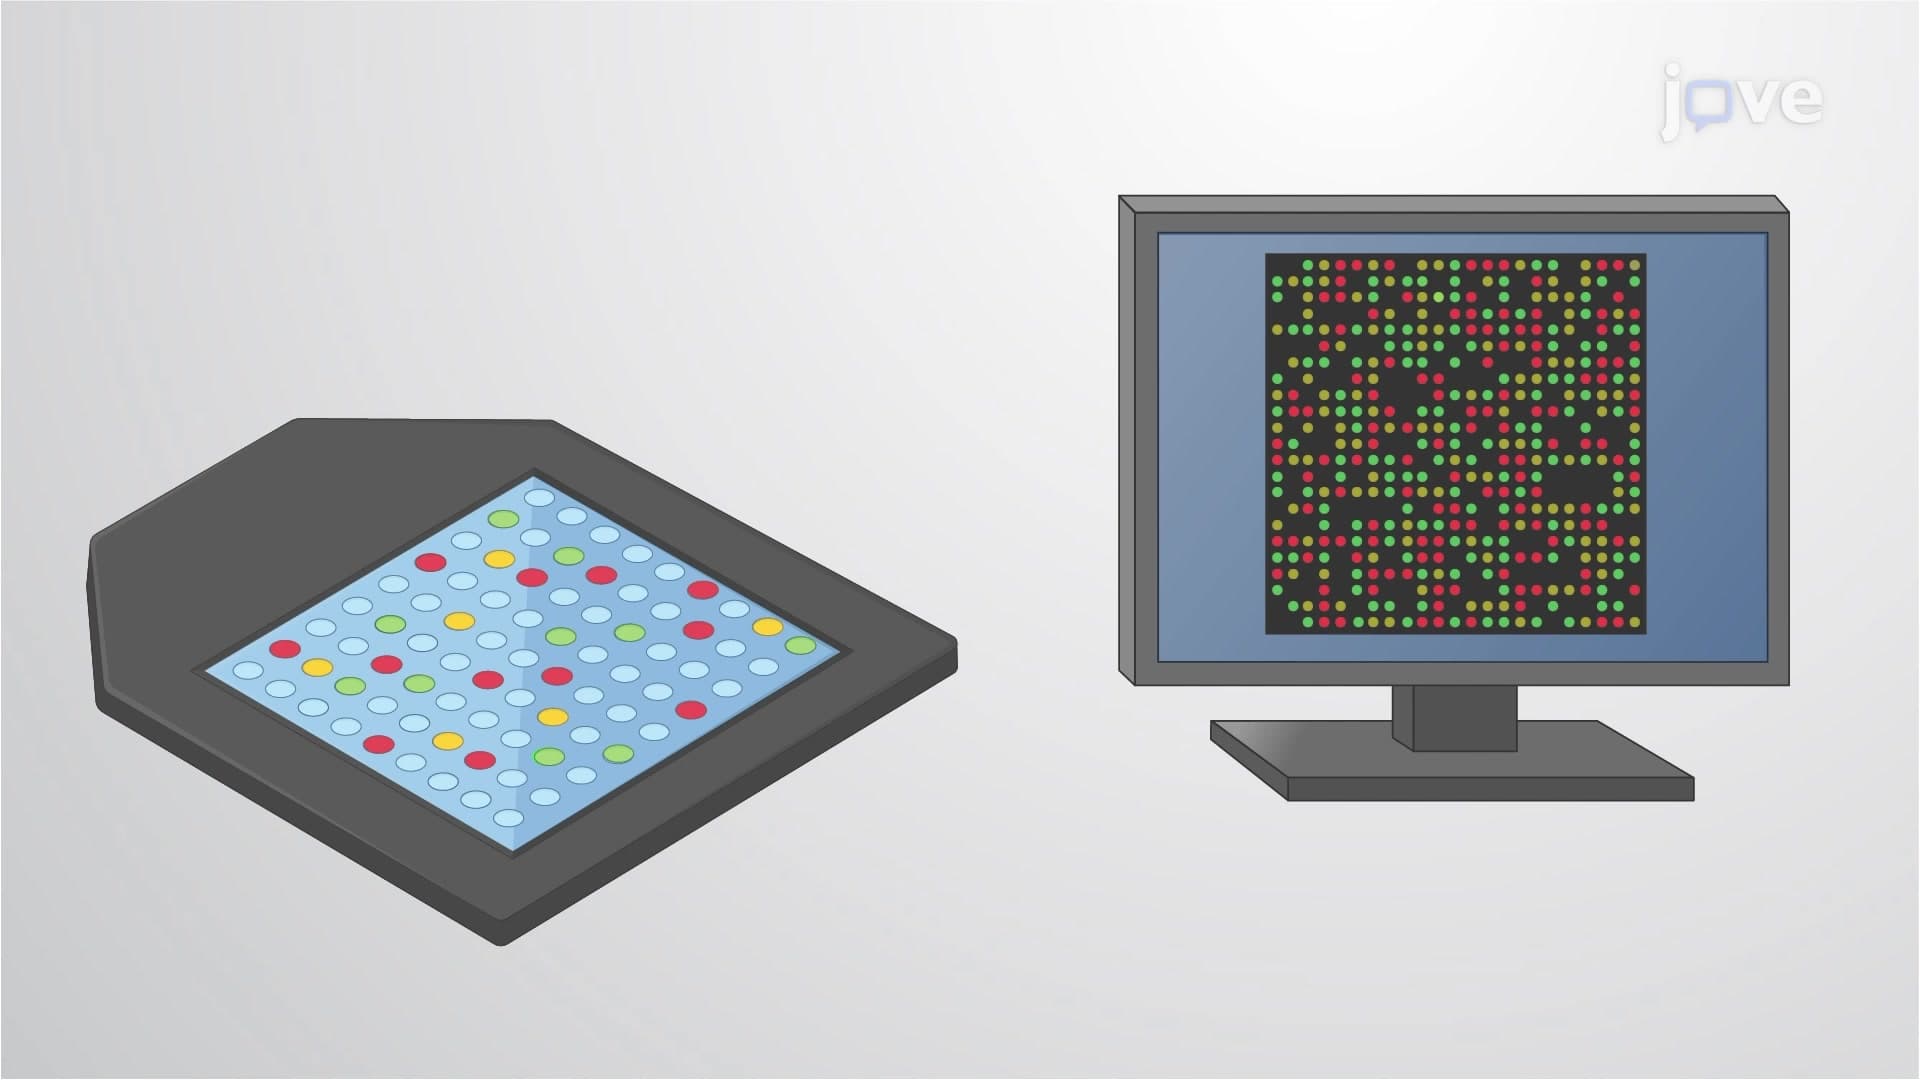
DNA Microarrays
 01:11
Genome-wide Association Studies-GWAS
GWAS does not require the identification of the target gene involved in...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...