Learning Rate Dropout
Related Experiment Video
Updated: Sep 30, 2025

Deep Neural Networks for Image-Based Dietary Assessment
Published on: March 13, 2021

Abstract:
Optimization algorithms are of great importance to efficiently and effectively train a deep neural network. However, the existing optimization algorithms show unsatisfactory convergence behavior, either slowly converging or not seeking to avoid bad local optima. Learning rate dropout (LRD) is a new gradient descent technique to motivate faster convergence and better generalization. LRD aids the optimizer to actively explore in the parameter space by randomly dropping some learning rates (to 0); at each iteration, only parameters whose learning rate is not 0 are updated. Since LRD reduces the number of parameters to be updated for each iteration, the convergence becomes easier. For parameters that are not updated, their gradients are accumulated (e.g., momentum) by the optimizer for the next update. Accumulating multiple gradients at fixed parameter positions gives the optimizer more energy to escape from the saddle point and bad local optima. Experiments show that LRD is surprisingly effective in accelerating training while preventing overfitting.
Related Concept Videos
 01:11
Hazard Rate
 01:30
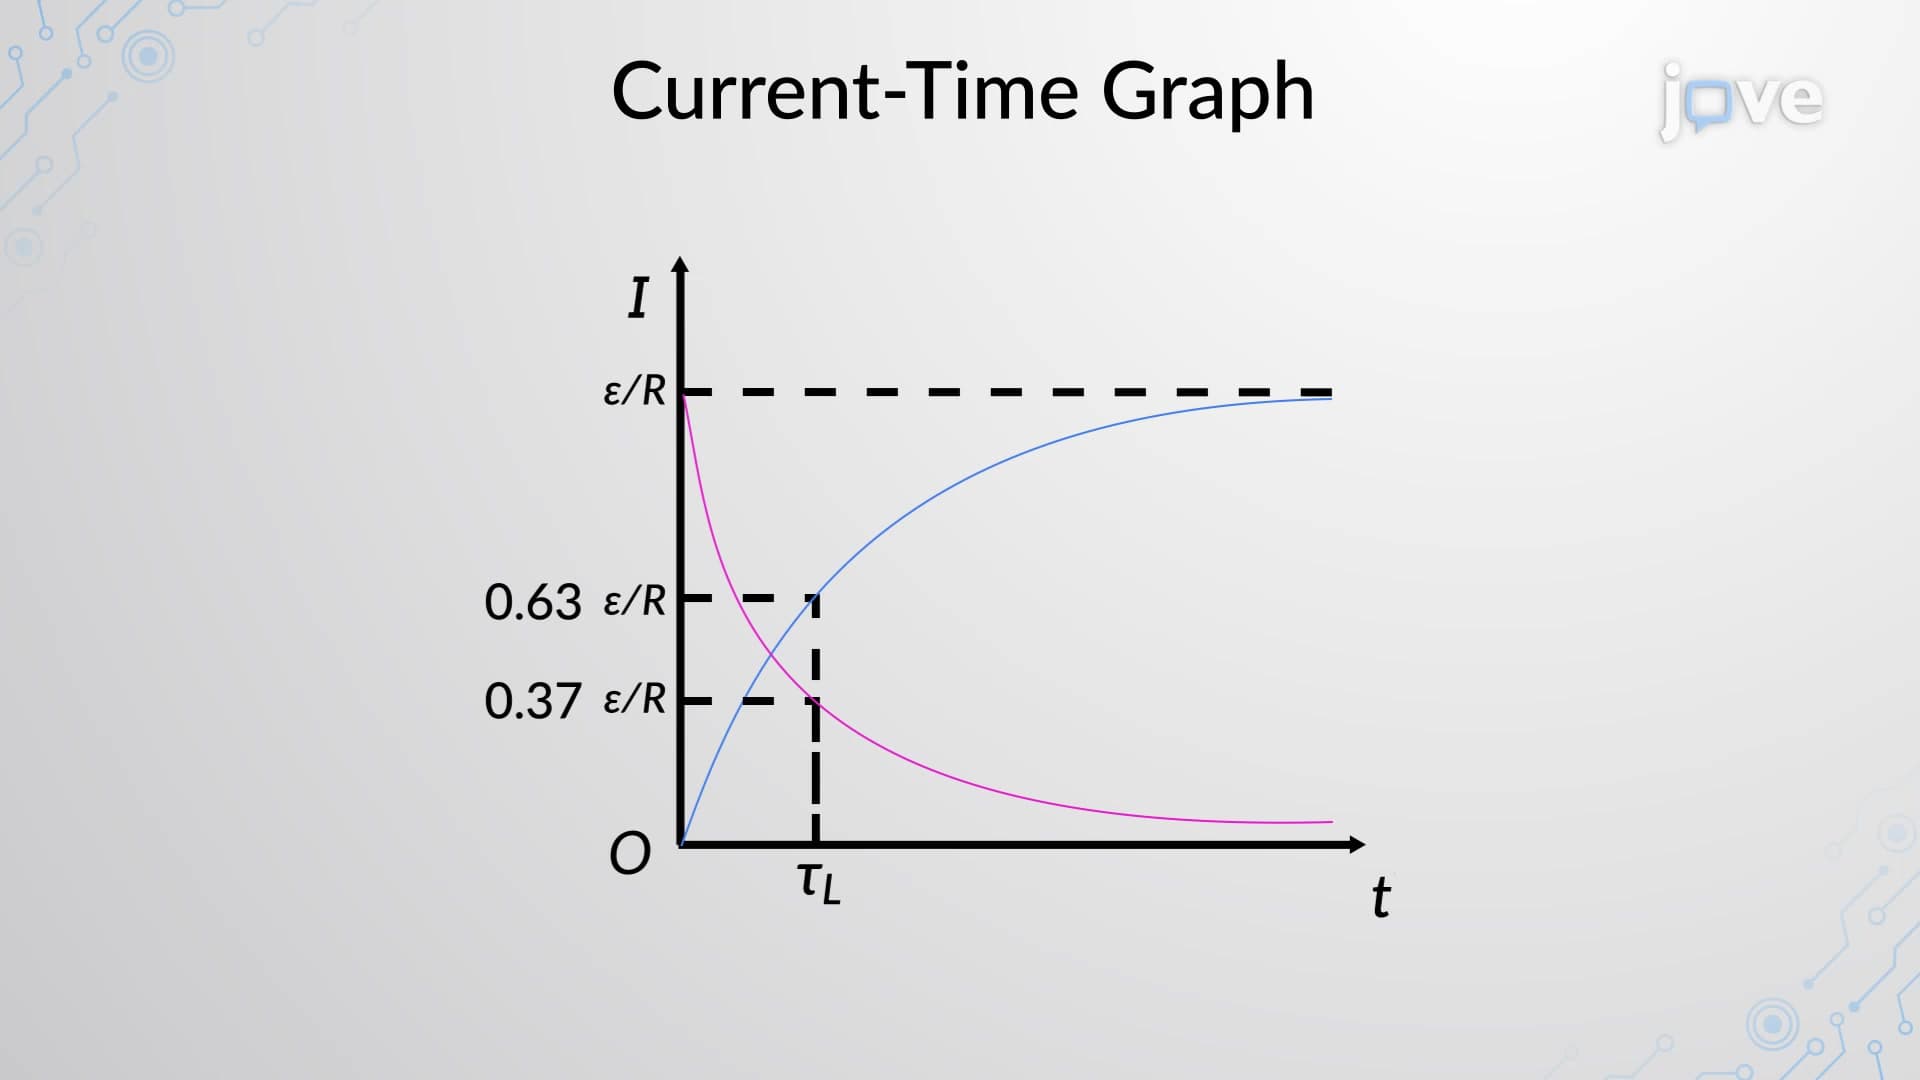
Current Growth And Decay In RL Circuits
 01:52
Regression Toward the Mean
 01:19
Survival Tree
Building a Survival Tree
Constructing a...
 01:18
Introduction to Learning
In contrast to learned behaviors, unlearned behaviors such as crying, sexual...
 01:24
Generalization, Discrimination, and Extinction
Generalization occurs when a behavior reinforced in one context is performed in similar situations. For instance, a student who studies diligently for calculus and receives excellent grades might apply the same study habits to psychology and history, expecting similar results. Generalization shows how learning in one setting can influence behavior in...