Related Experiment Video
Updated: Sep 22, 2025

How to Measure Cortical Folding from MR Images: a Step-by-Step Tutorial to Compute Local Gyrification Index
Published on: January 2, 2012
Lossless indexing with counting de Bruijn graphs
Mikhail Karasikov1,2,3, Harun Mustafa1,2,3, Gunnar Rätsch1,2,3,4,5
1Department of Computer Science, ETH Zurich, 8092 Zurich, Switzerland.

Abstract:
Sequencing data are rapidly accumulating in public repositories. Making this resource accessible for interactive analysis at scale requires efficient approaches for its storage and indexing. There have recently been remarkable advances in building compressed representations of annotated (or colored) de Bruijn graphs for efficiently indexing k-mer sets. However, approaches for representing quantitative attributes such as gene expression or genome positions in a general manner have remained underexplored. In this work, we propose counting de Bruijn graphs, a notion generalizing annotated de Bruijn graphs by supplementing each node-label relation with one or many attributes (e.g., a k-mer count or its positions). Counting de Bruijn graphs index k-mer abundances from 2652 human RNA-seq samples in over eightfold smaller representations compared with state-of-the-art bioinformatics tools and is faster to construct and query. Furthermore, counting de Bruijn graphs with positional annotations losslessly represent entire reads in indexes on average 27% smaller than the input compressed with gzip for human Illumina RNA-seq and 57% smaller for Pacific Biosciences (PacBio) HiFi sequencing of viral samples. A complete searchable index of all viral PacBio SMRT reads from NCBI's Sequence Read Archive (SRA) (152,884 samples, 875 Gbp) comprises only 178 GB. Finally, on the full RefSeq collection, we generate a lossless and fully queryable index that is 4.6-fold smaller than the MegaBLAST index. The techniques proposed in this work naturally complement existing methods and tools using de Bruijn graphs, and significantly broaden their applicability: from indexing k-mer counts and genome positions to implementing novel sequence alignment algorithms on top of highly compressed graph-based sequence indexes.
Related Concept Videos
 01:15
Routh-Hurwitz Criterion I
To apply the Routh-Hurwitz criterion, a Routh table is constructed. The table's rows are labeled with powers of the complex frequency variable s, starting from the...
 01:19
Routh-Hurwitz Criterion II
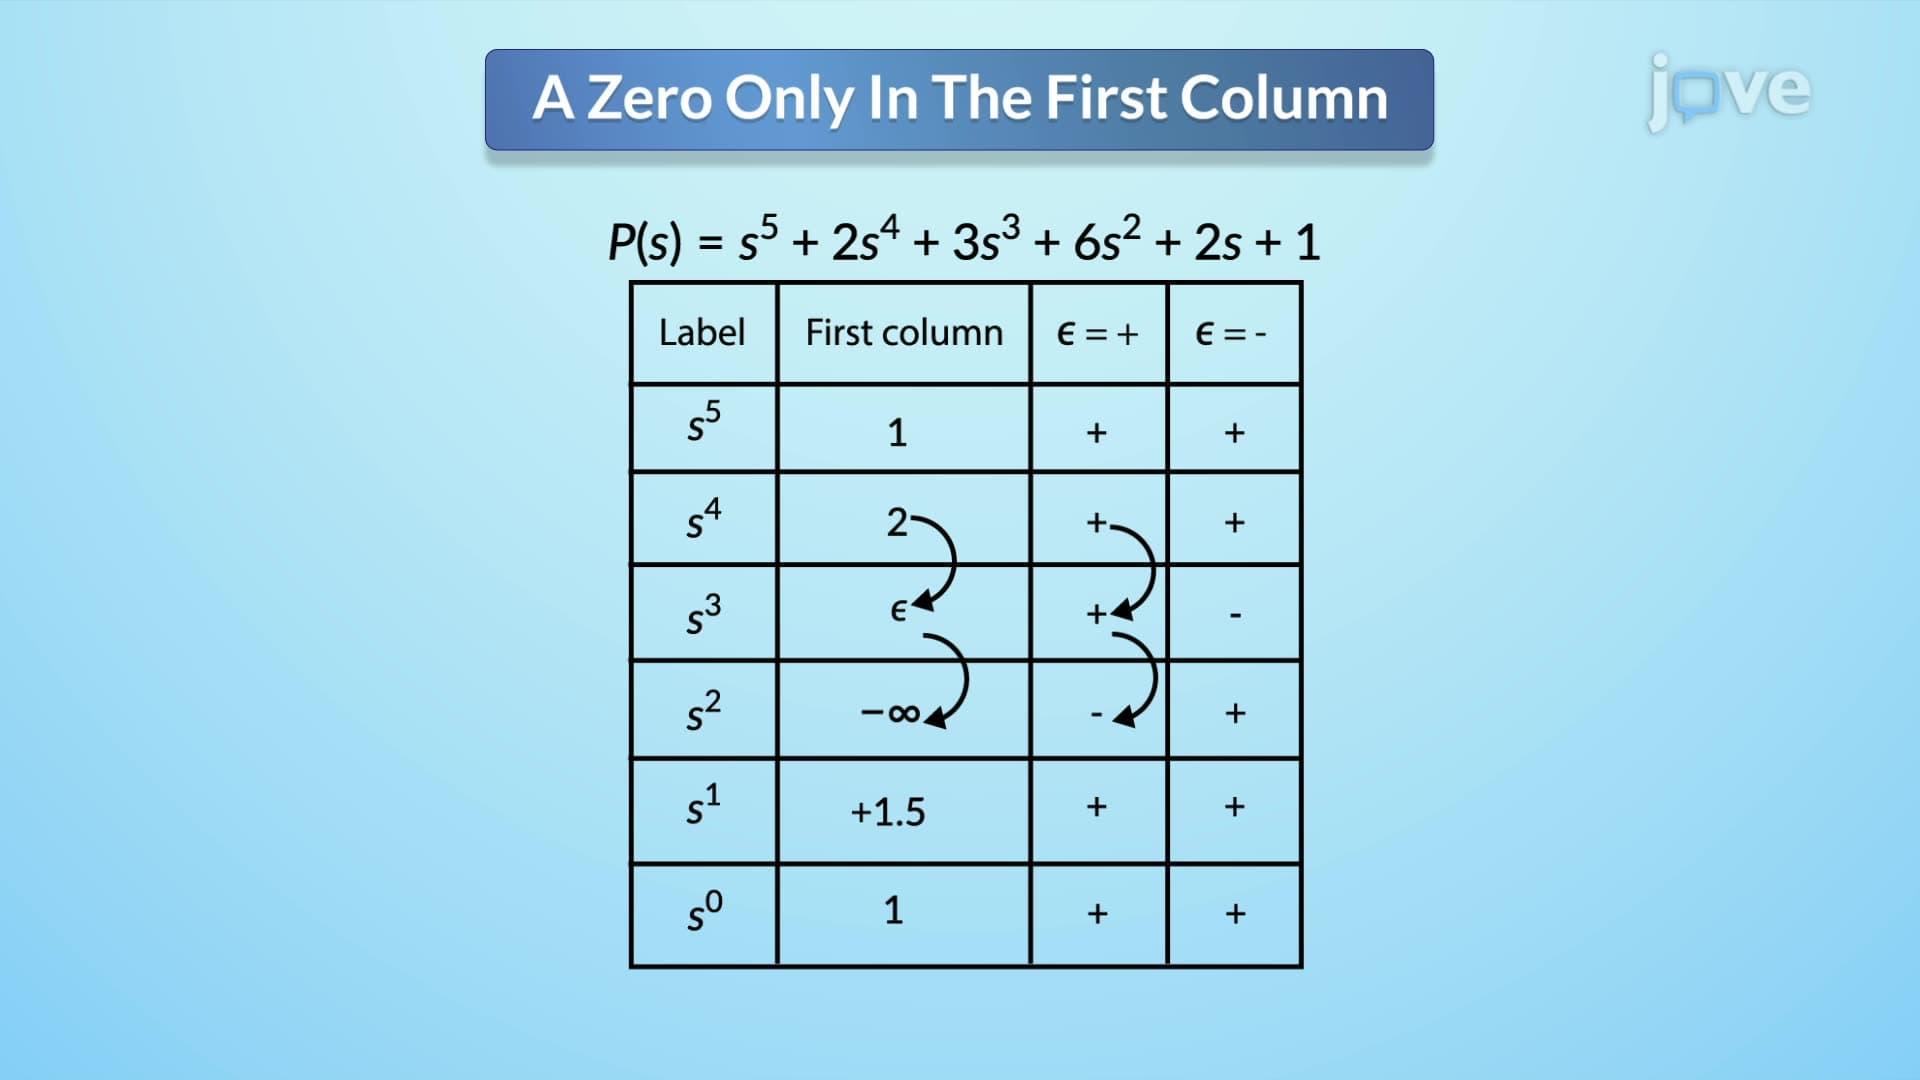
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first...
 01:10
Vector Algebra: Graphical Method
We use the laws of geometry to construct resultant vectors, followed by trigonometry to find vector magnitudes and directions. For a geometric construction of the sum of two vectors in a plane, we follow the parallelogram rule. Suppose two vectors are at arbitrary positions. Translate either one of...
 01:12
Bewley Lattice Diagram
 01:21
Boundary Conditions: Lossless Lines
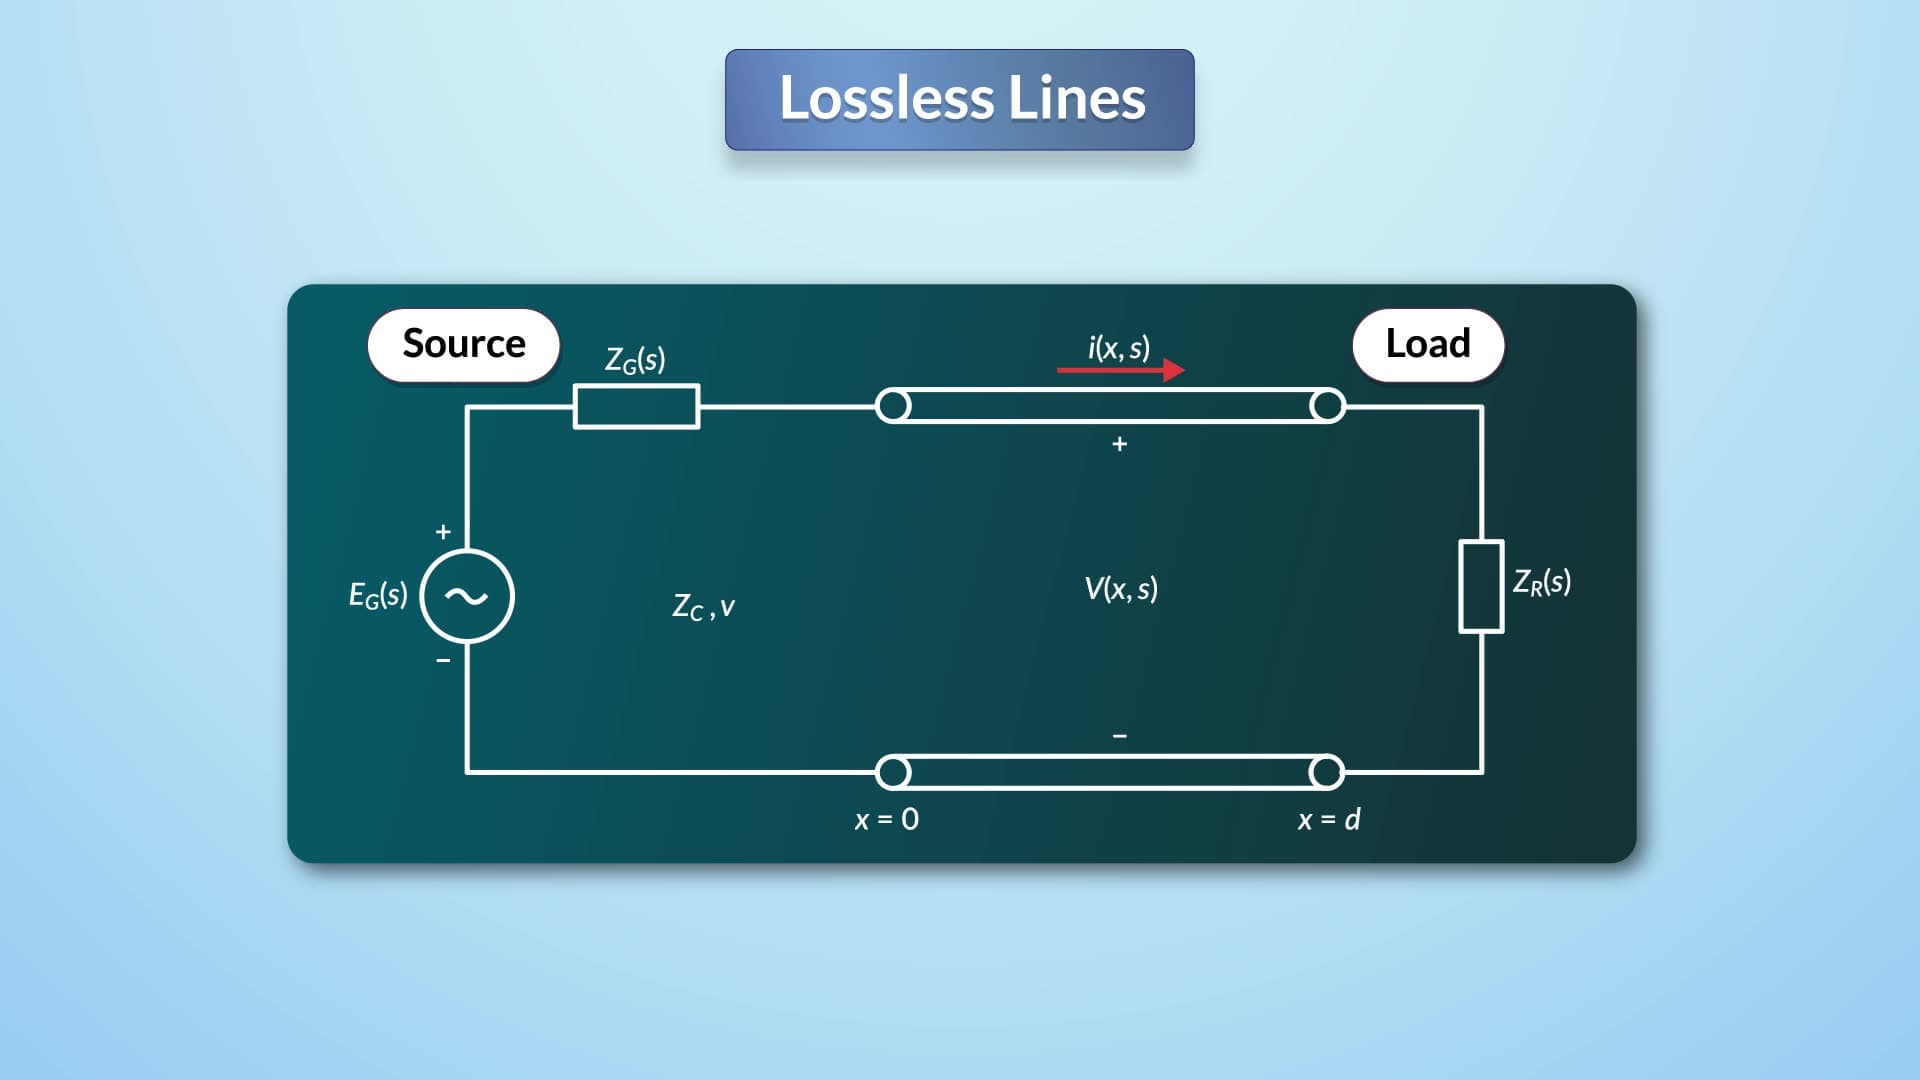
At the receiving end, the boundary condition states that the voltage equals the product of the receiving-end impedance and current. This relationship is expressed as a function of the incident and...
 01:16
Second Uniqueness Theorem
In contrast, consider that the electric field is non-unique and apply Gauss's law in divergence form in the region between the conductors and the integral form to the...