Related Experiment Video
Updated: Sep 7, 2025
Investigating Object Representations in the Macaque Dorsal Visual Stream Using Single-unit Recordings
Published on: August 1, 2018
Reinforcement Learning Model With Dynamic State Space Tested on Target Search Tasks for Monkeys: Extension to
Kazuhiro Sakamoto1,2, Hinata Yamada1, Norihiko Kawaguchi2
1Department of Neuroscience, Faculty of Medicine, Tohoku Medical and Pharmaceutical University, Sendai, Japan.

Abstract:
Learning is a crucial basis for biological systems to adapt to environments. Environments include various states or episodes, and episode-dependent learning is essential in adaptation to such complex situations. Here, we developed a model for learning a two-target search task used in primate physiological experiments. In the task, the agent is required to gaze one of the four presented light spots. Two neighboring spots are served as the correct target alternately, and the correct target pair is switched after a certain number of consecutive successes. In order for the agent to obtain rewards with a high probability, it is necessary to make decisions based on the actions and results of the previous two trials. Our previous work achieved this by using a dynamic state space. However, to learn a task that includes events such as fixation to the initial central spot, the model framework should be extended. For this purpose, here we propose a "history-in-episode architecture." Specifically, we divide states into episodes and histories, and actions are selected based on the histories within each episode. When we compared the proposed model including the dynamic state space with the conventional SARSA method in the two-target search task, the former performed close to the theoretical optimum, while the latter never achieved target-pair switch because it had to re-learn each correct target each time. The reinforcement learning model including the proposed history-in-episode architecture and dynamic state scape enables episode-dependent learning and provides a basis for highly adaptable learning systems to complex environments.
Related Concept Videos
 01:27
State Space Representation
Consider an RLC circuit, a...
 01:12
Observational Learning
 01:24
Reinforcement Schedules
Once a behavior is learned,...
 01:21
State Space to Transfer Function
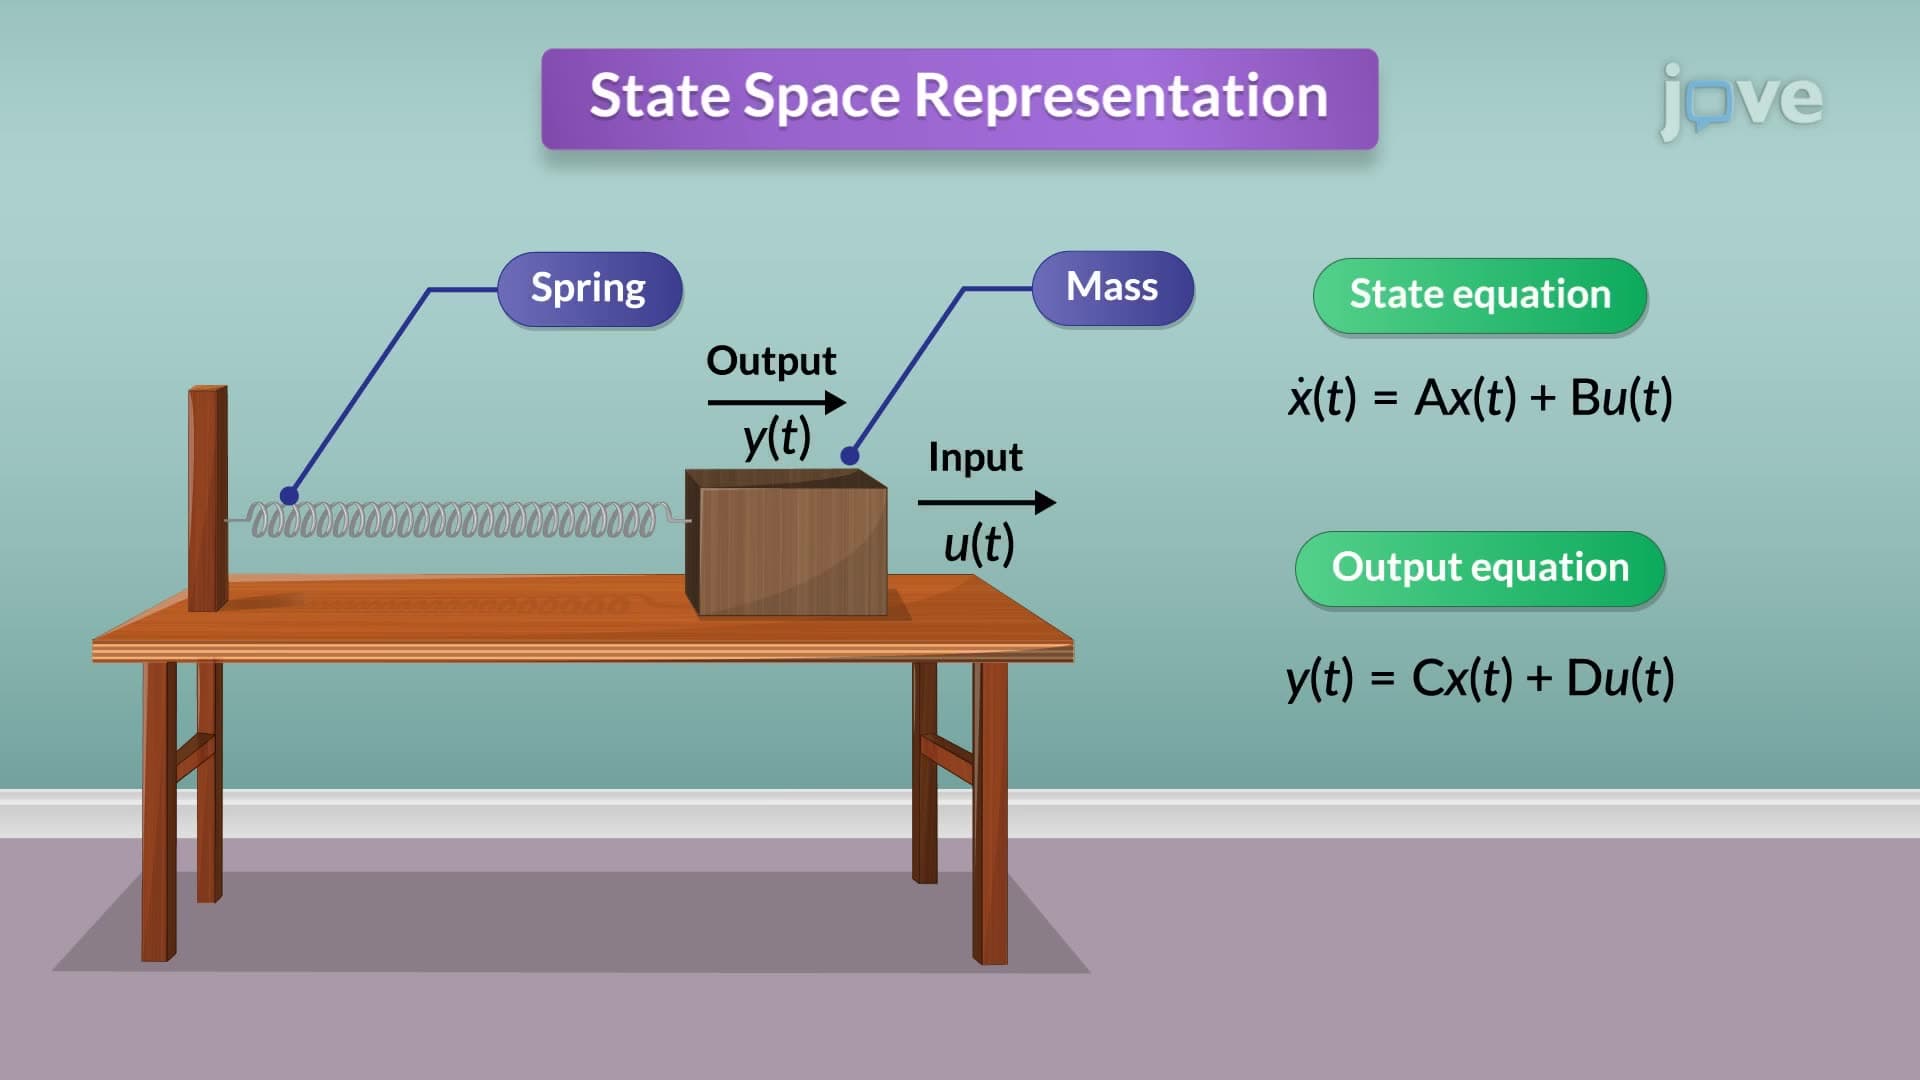
The transformation process begins with the state-space representation, characterized by the state equation and the output equation. These equations are typically represented as:
 01:23
Transfer Function to State Space
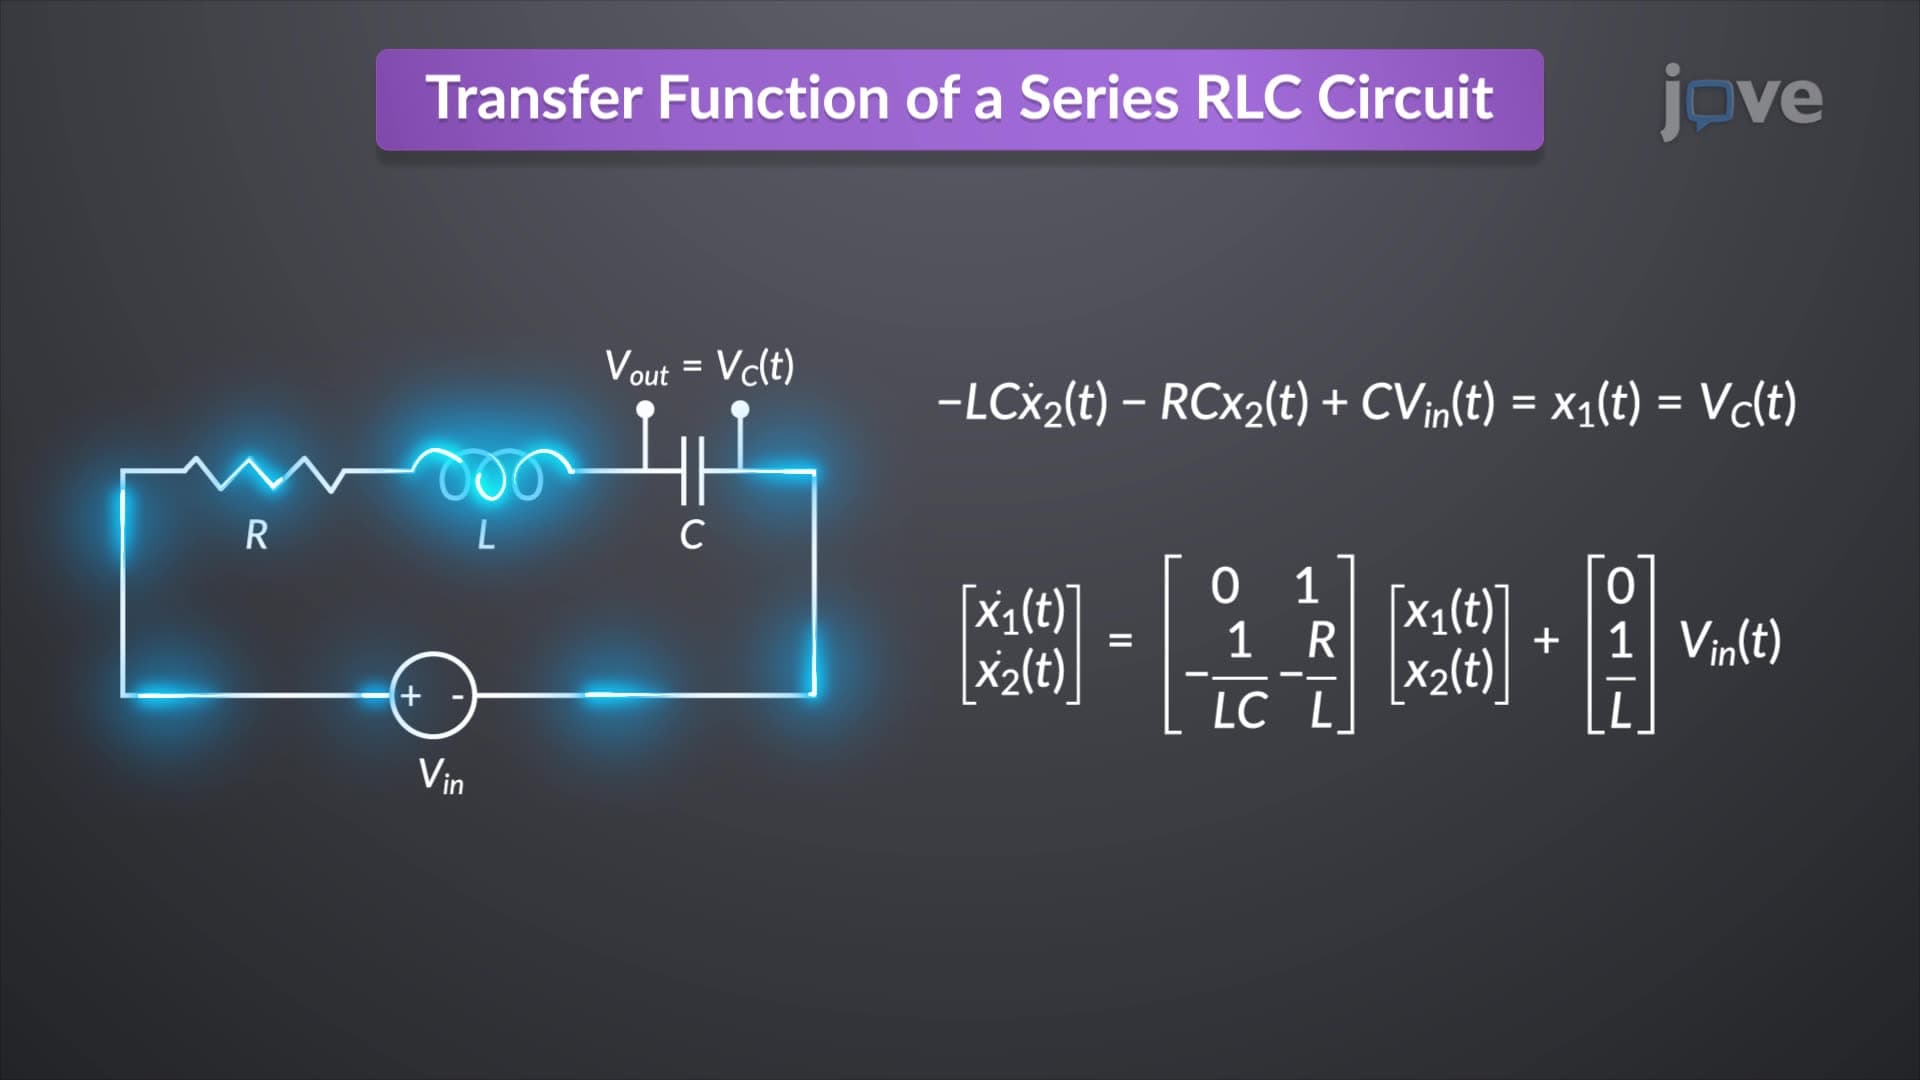
In an...