Transfer learning in proteins: evaluating novel protein learned representations for bioinformatics tasks
Related Experiment Video
Updated: Sep 6, 2025
DNA Virus Detection System Based on RPA-CRISPR/Cas12a-SPM and Deep Learning
Published on: May 10, 2024
Emilio Fenoy1, Alejando A Edera1, Georgina Stegmayer1
1Research Institute for Signals, Systems and Computational Intelligence sinc(i) (CONICET-UNL), Ciudad Universitaria, Santa Fe, Argentina.

Abstract:
A representation method is an algorithm that calculates numerical feature vectors for samples in a dataset. Such vectors, also known as embeddings, define a relatively low-dimensional space able to efficiently encode high-dimensional data. Very recently, many types of learned data representations based on machine learning have appeared and are being applied to several tasks in bioinformatics. In particular, protein representation learning methods integrate different types of protein information (sequence, domains, etc.), in supervised or unsupervised learning approaches, and provide embeddings of protein sequences that can be used for downstream tasks. One task that is of special interest is the automatic function prediction of the huge number of novel proteins that are being discovered nowadays and are still totally uncharacterized. However, despite its importance, up to date there is not a fair benchmark study of the predictive performance of existing proposals on the same large set of proteins and for very concrete and common bioinformatics tasks. Therefore, this lack of benchmark studies prevent the community from using adequate predictive methods for accelerating the functional characterization of proteins. In this study, we performed a detailed comparison of protein sequence representation learning methods, explaining each approach and comparing them with an experimental benchmark on several bioinformatics tasks: (i) determining protein sequence similarity in the embedding space; (ii) inferring protein domains and (iii) predicting ontology-based protein functions. We examine the advantages and disadvantages of each representation approach over the benchmark results. We hope the results and the discussion of this study can help the community to select the most adequate machine learning-based technique for protein representation according to the bioinformatics task at hand.


Related Concept Videos
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to...
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
 02:04
Protein-protein Interfaces
02:26Conservation of Protein Domains
 02:15
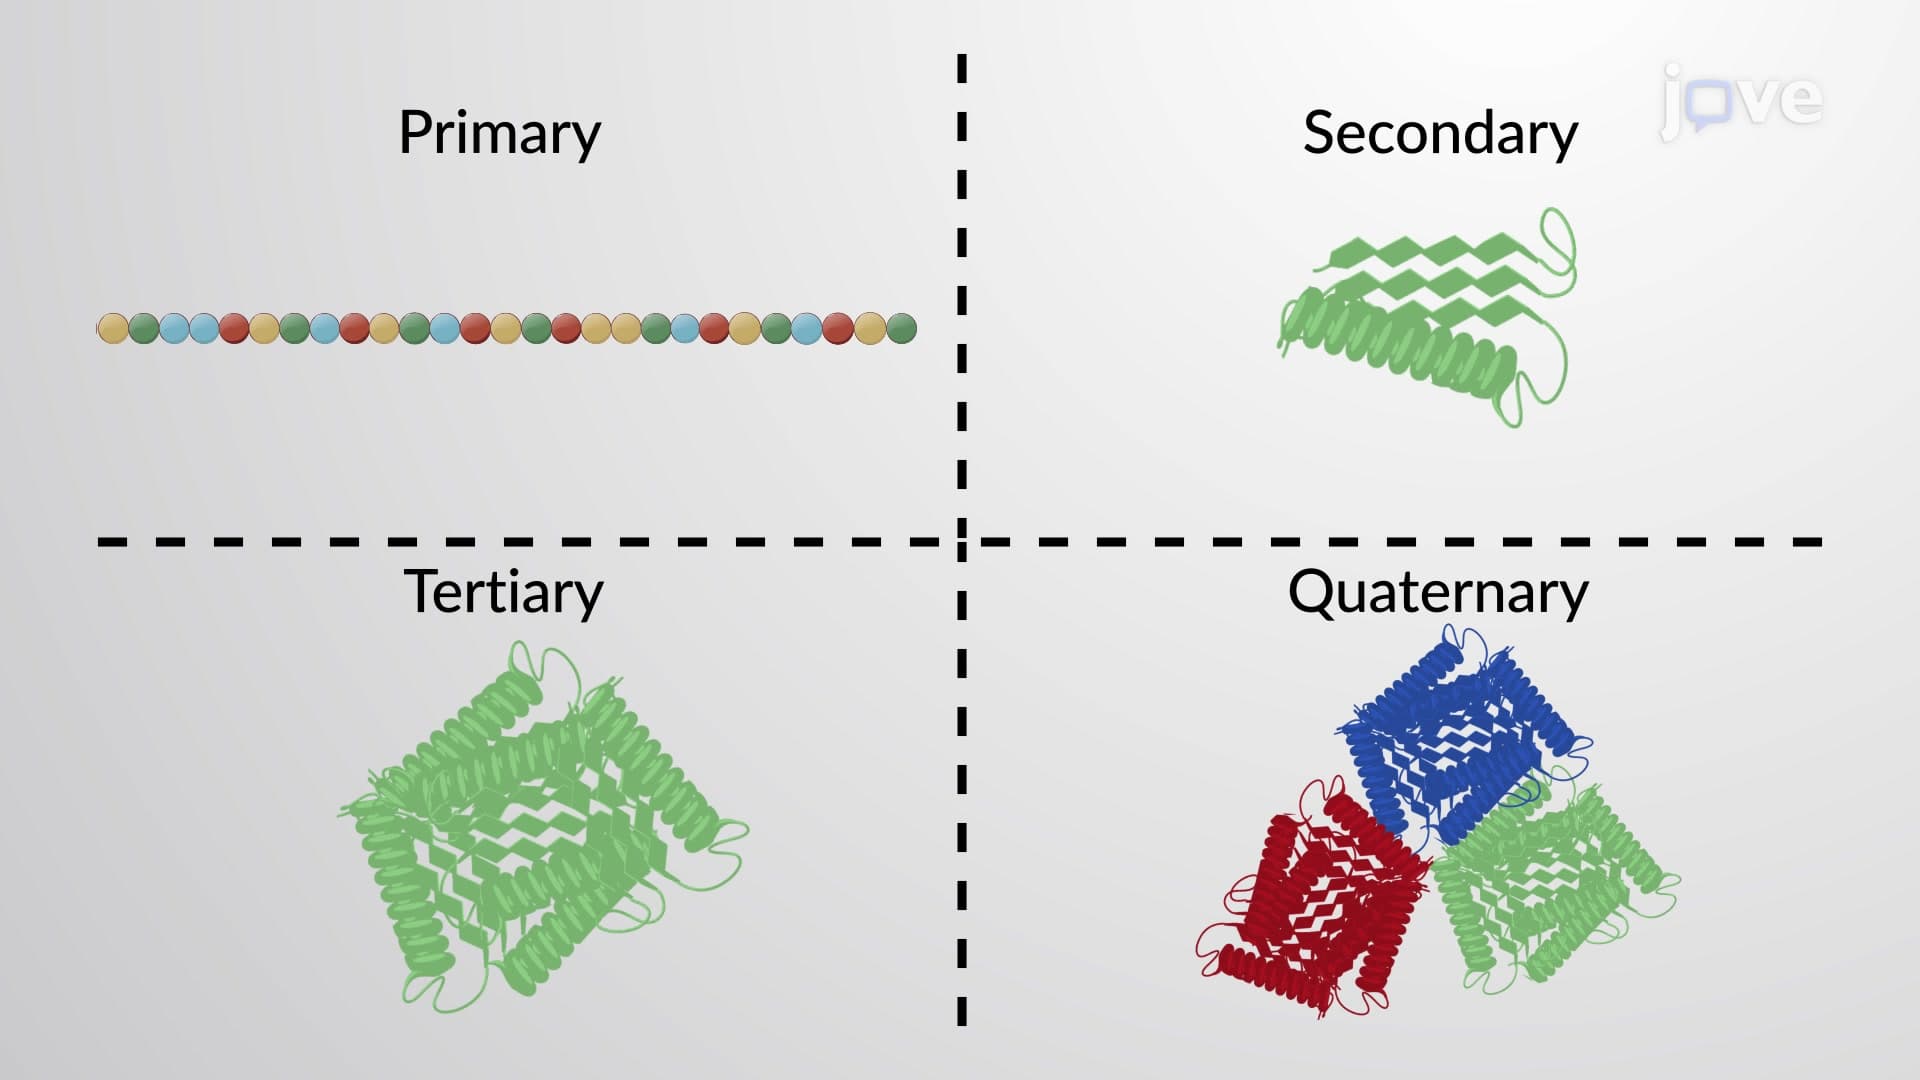
Protein and Protein Structure
A protein's shape is critical to its function. For example, an enzyme...
02:15Protein and Protein Structures