Related Experiment Video
Updated: Aug 30, 2025


A Psychophysics Paradigm for the Collection and Analysis of Similarity Judgments
Published on: March 1, 2022
Relative Entropy of Distance Distribution Based Similarity Measure of Nodes in Weighted Graph Data
Shihu Liu1, Yingjie Liu1, Chunsheng Yang1
1School of Mathematics and Computer Science, Yunnan Minzu University, Kunming 650504, China.

Abstract:
Many similarity measure algorithms of nodes in weighted graph data have been proposed by employing the degree of nodes in recent years. Despite these algorithms obtaining great results, there may be still some limitations. For instance, the strength of nodes is ignored. Aiming at this issue, the relative entropy of the distance distribution based similarity measure of nodes is proposed in this paper. At first, the structural weights of nodes are given by integrating their degree and strength. Next, the distance between any two nodes is calculated with the help of their structural weights and the Euclidean distance formula to further obtain the distance distribution of each node. After that, the probability distribution of nodes is constructed by normalizing their distance distributions. Thus, the relative entropy can be applied to measure the difference between the probability distributions of the top d important nodes and all nodes in graph data. Finally, the similarity of two nodes can be measured in terms of this above-mentioned difference calculated by relative entropy. Experimental results demonstrate that the algorithm proposed by considering the strength of node in the relative entropy has great advantages in the most similar node mining and link prediction.
More Related Videos
 09:49
Divergence of Root Microbiota in Different Habitats based on Weighted Correlation Networks
Published on: September 25, 2021
 12:27
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
Related Concept Videos
 01:12
Coefficient of Correlation
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...
 01:20
Kendall's Coefficient of Concordance
 01:20
Spearman's Rank Correlation Test
Spearman's test calculates...
 00:55
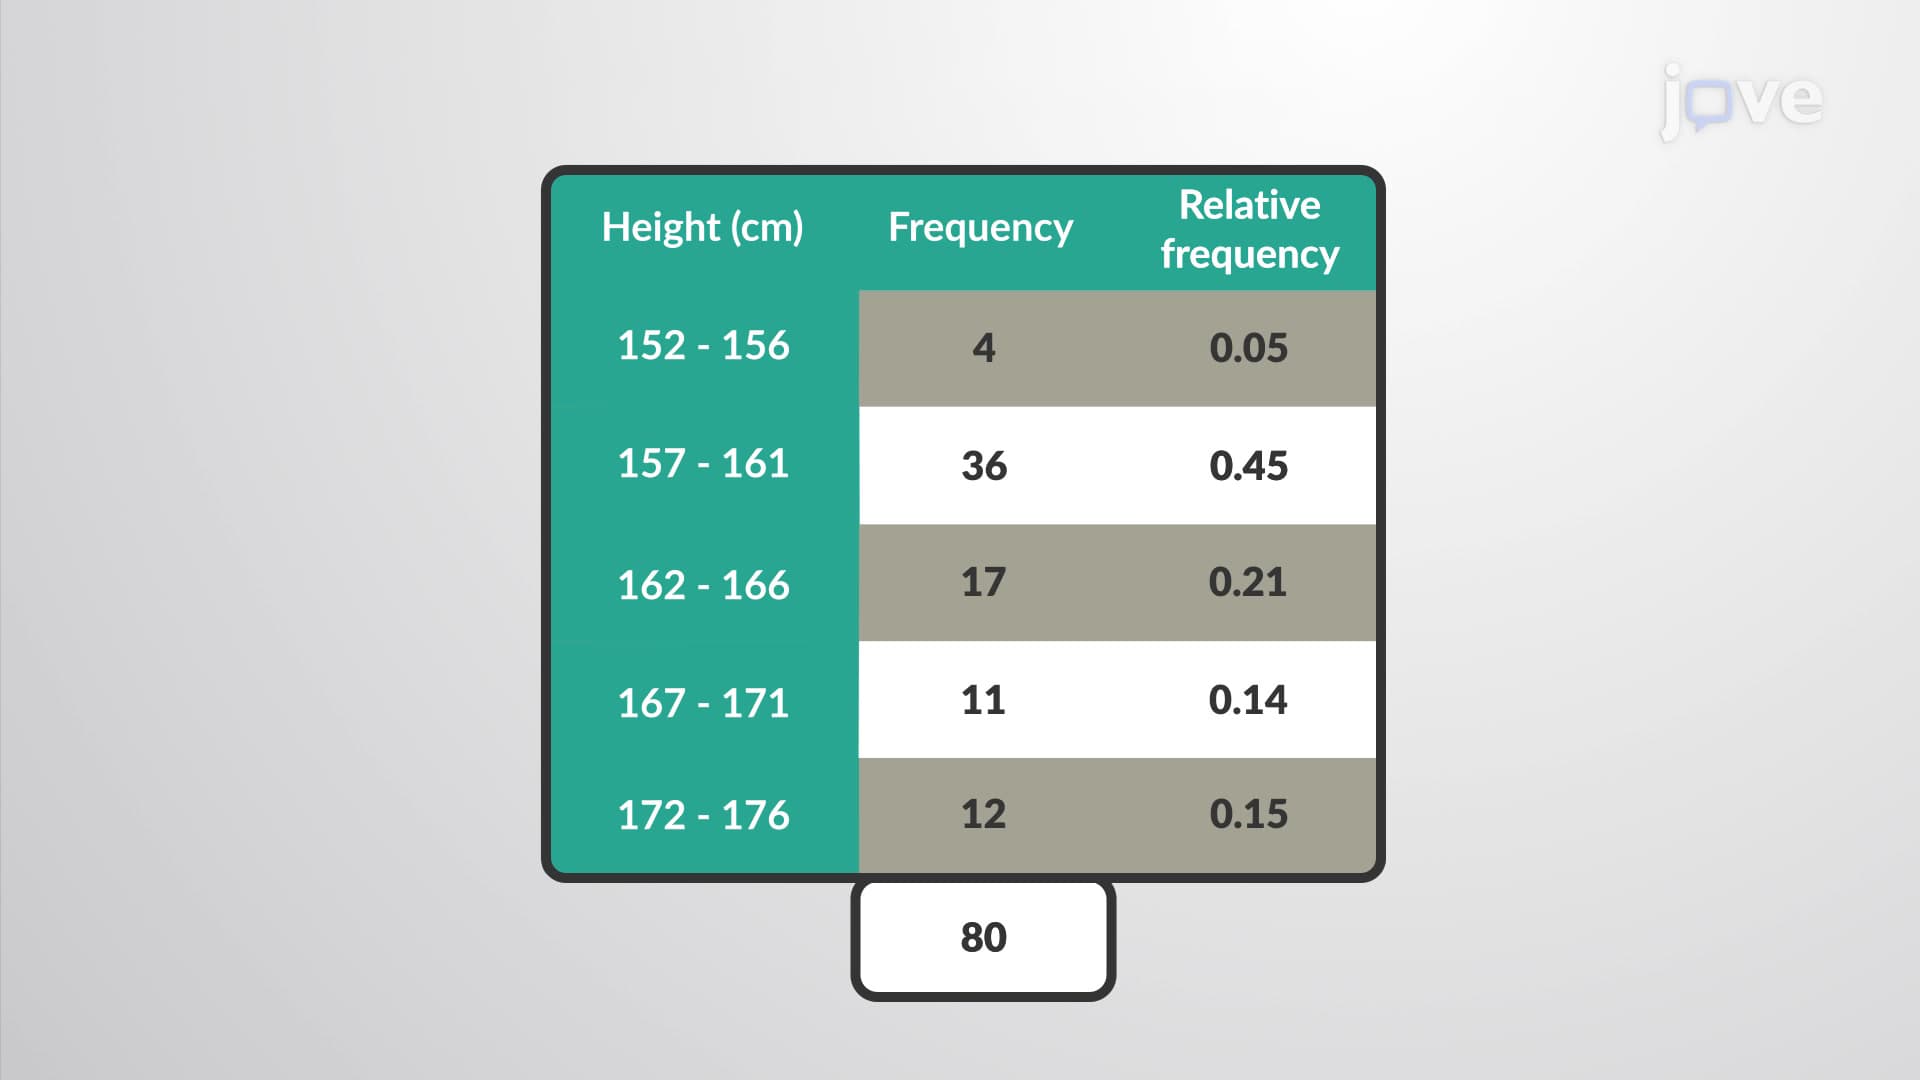
Relative Frequency Distribution
 00:57
Weighted Mean
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
 01:12
Sampling Distribution