Related Experiment Video
Updated: Aug 28, 2025
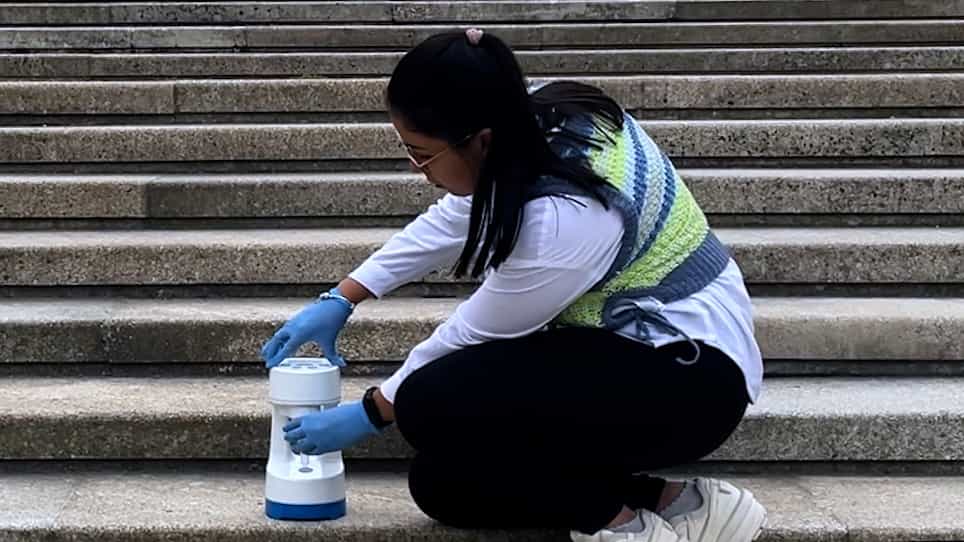

Quantification and Whole Genome Characterization of SARS-CoV-2 RNA in Wastewater and Air Samples
Published on: June 30, 2023
Analysis of the Rate of Confirmed COVID-19 Cases in Seoul and Factors Affecting It Using Big Data Analysis
San-Duk Yang1, Hyun-Seok Park2,3
1Department of Cyber Security & AI technology, The School of Integrated Software and Design, Kyung Hee Cyber University, Seoul, Republic of Korea.

Abstract:
Coronavirus disease (COVID-19) is caused by infection with the severe acute respiratory syndrome coronavirus 2 (SARS-CoV-2) and presents with mild to severe symptoms. Vaccines have been developed, but COVID-19 persists. Therefore, it is necessary to analyze big data at an early stage to establish an effective infection prevention strategy. To reduce SARS-CoV-2 infection, this study aimed to analyze the infection factors by region within Seoul, Korea and identify the major factors affecting the infection rate. For ease of data aggregation, the study was conducted after a data refinement operation that organized data in the same group into categories, and classified them in detail by specific keywords. Based on the results of this study, if preventive measures are established after identifying the representative infectious factors, periods, and routes of COVID-19 infection, the infection rate could be effectively reduced in the future.

Related Concept Videos
 01:18
Steps in Outbreak Investigation
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:04
Pie Chart
In a pie chart, the central angle, the arc length of each slice, and the area are directly proportional to the quantity or percentage it represents. Some real-world examples that can be depicted using pie charts include marks obtained by students...
 01:12
Statistical Software for Data Analysis and Clinical Trials
 00:52
Pareto Chart
The Pareto chart is named after the Italian economist Vilfredo Pareto, who described the Pareto...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...