Related Experiment Video
Updated: Aug 27, 2025

The Pilocarpine Model of Temporal Lobe Epilepsy and EEG Monitoring Using Radiotelemetry System in Mice
Published on: February 27, 2018
PM2.5 Forecast in Korea using the Long Short-Term Memory (LSTM) Model
Chang-Hoi Ho1, Ingyu Park1, Jinwon Kim2
1School of Earth and Environmental Sciences, Seoul National University, 1 Gwanak-ro, Gwanak-gu, Seoul, 08826 Republic of Korea.

Abstract:
The National Institute of Environmental Research, under the Ministry of Environment of Korea, provides two-day forecasts, through AirKorea, of the concentration of particulate matter with diameters of ≤ 2.5 μm (PM2.5) in terms of four grades (low, moderate, high, and very high) over 19 districts nationwide. Particulate grades are subjectively designated by human forecasters based on forecast results from the Community Multiscale Air Quality (CMAQ) and artificial intelligence (AI) models in conjunction with weather patterns. This study evaluates forecasts from the long short-term memory (LSTM) algorithm relative to those from CMAQ-solely and AirKorea using observations from 2019. The skills of the one-day PM2.5 forecasts over the 19 districts were 39-70% for CMAQ, 72-79% for LSTM, and 73-80% for AirKorea; the AI forecasts showed comparable skills to the human forecasters at AirKorea. The one-day forecast skill levels of high and very high PM2.5 pollution grades are 31-98%, 31-74%, and 39-81% for the CMAQ-solely, the LSTM, and the AirKorea forecasts, respectively. Despite good skills for forecasting the high and very high events, CMAQ-solely forecasts also generate substantially higher false alarm rates (up to 86%) than the LSTM and AirKorea forecasts (up to 58%). Hence, applying only the LSTM model to the CMAQ forecasts can yield reasonable forecast skill levels comparable to the operational AirKorea forecasts that elaborately combine the CMAQ model, AI models, and human forecasters. The present results suggest that applications of appropriate AI models can greatly enhance PM2.5 forecast skills for Korea in a more objective way.
Supplementary Information:
The online version contains supplementary material available at 10.1007/s13143-022-00293-2.
Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:05
Noncompartmental Analysis: Mean Residence Time
After the administration of a drug through intravenous bolus injection, the drug molecules are distributed throughout the body and remain there for varying periods. The MRT represents the average time these drug molecules stay in the...
 01:07
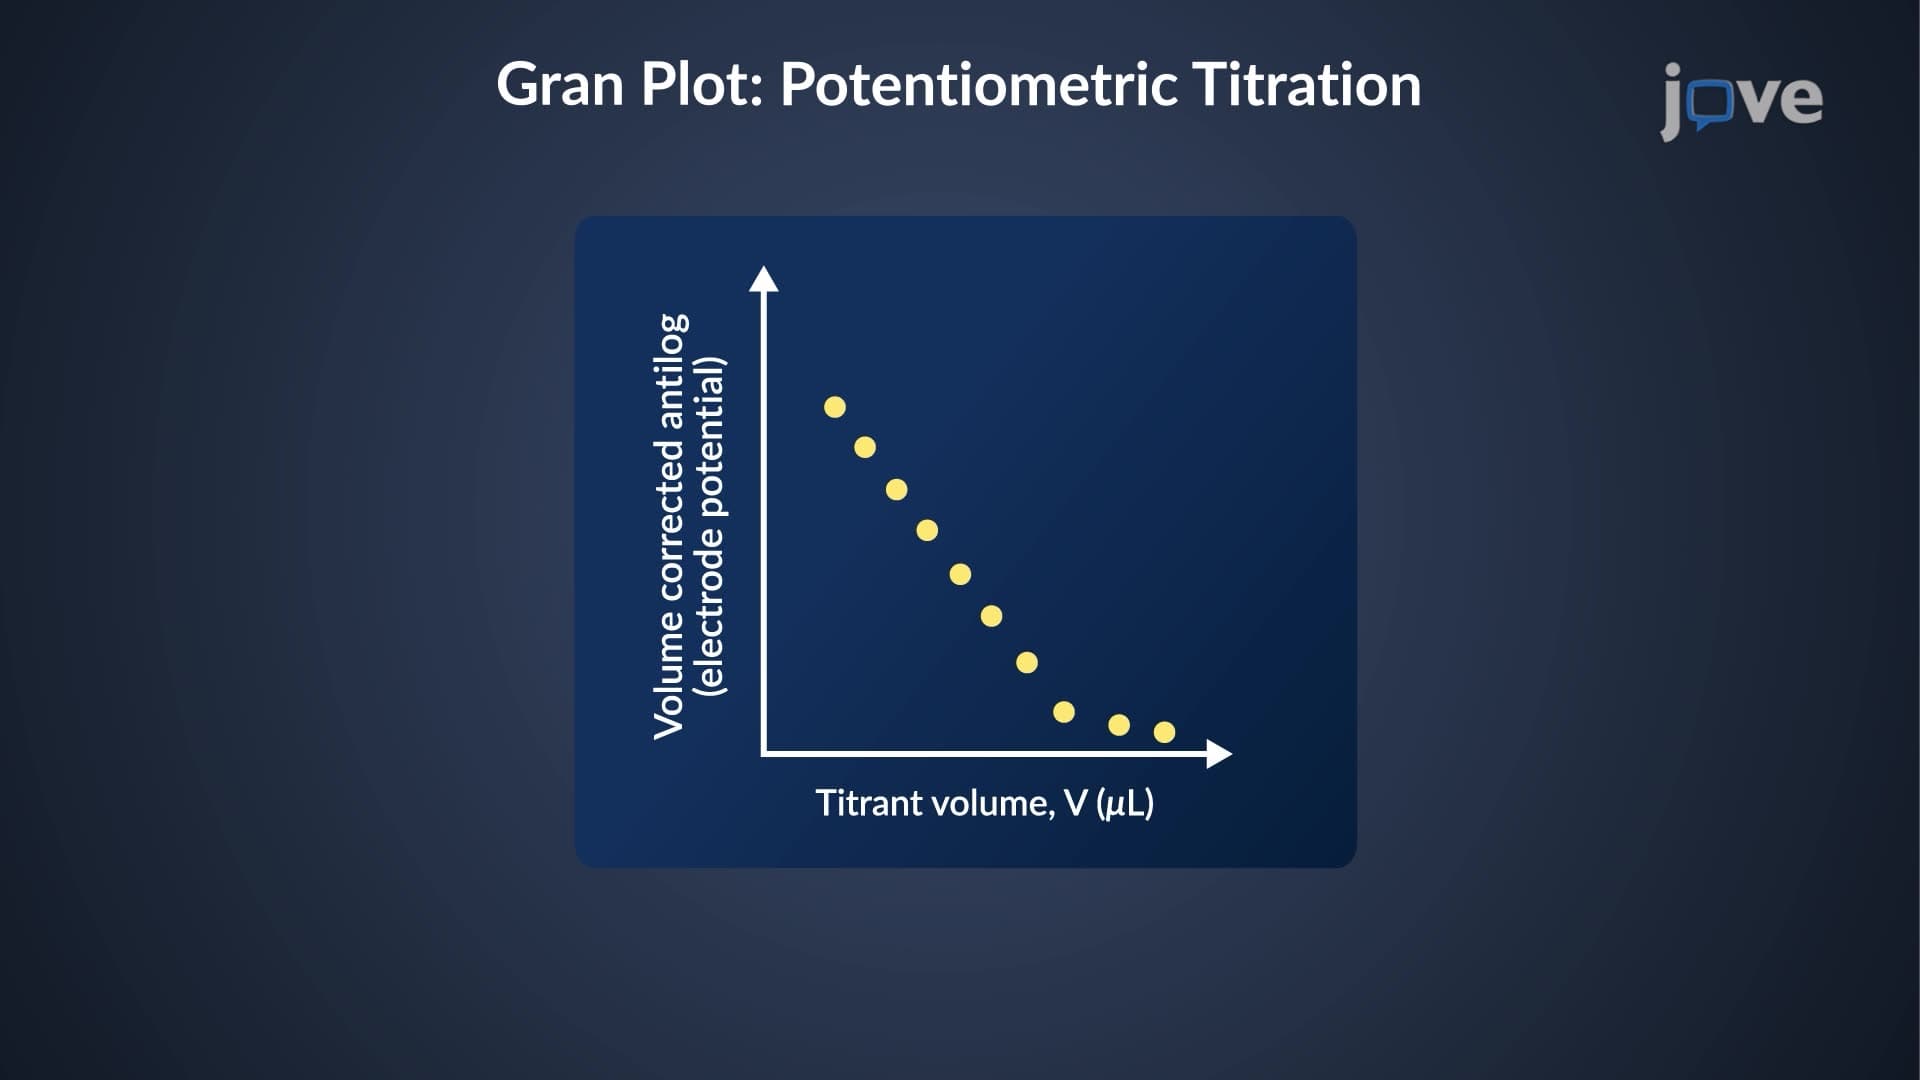
End Point Prediction: Gran Plot
For potentiometric titration, the Gran plot is created by plotting...
 01:13
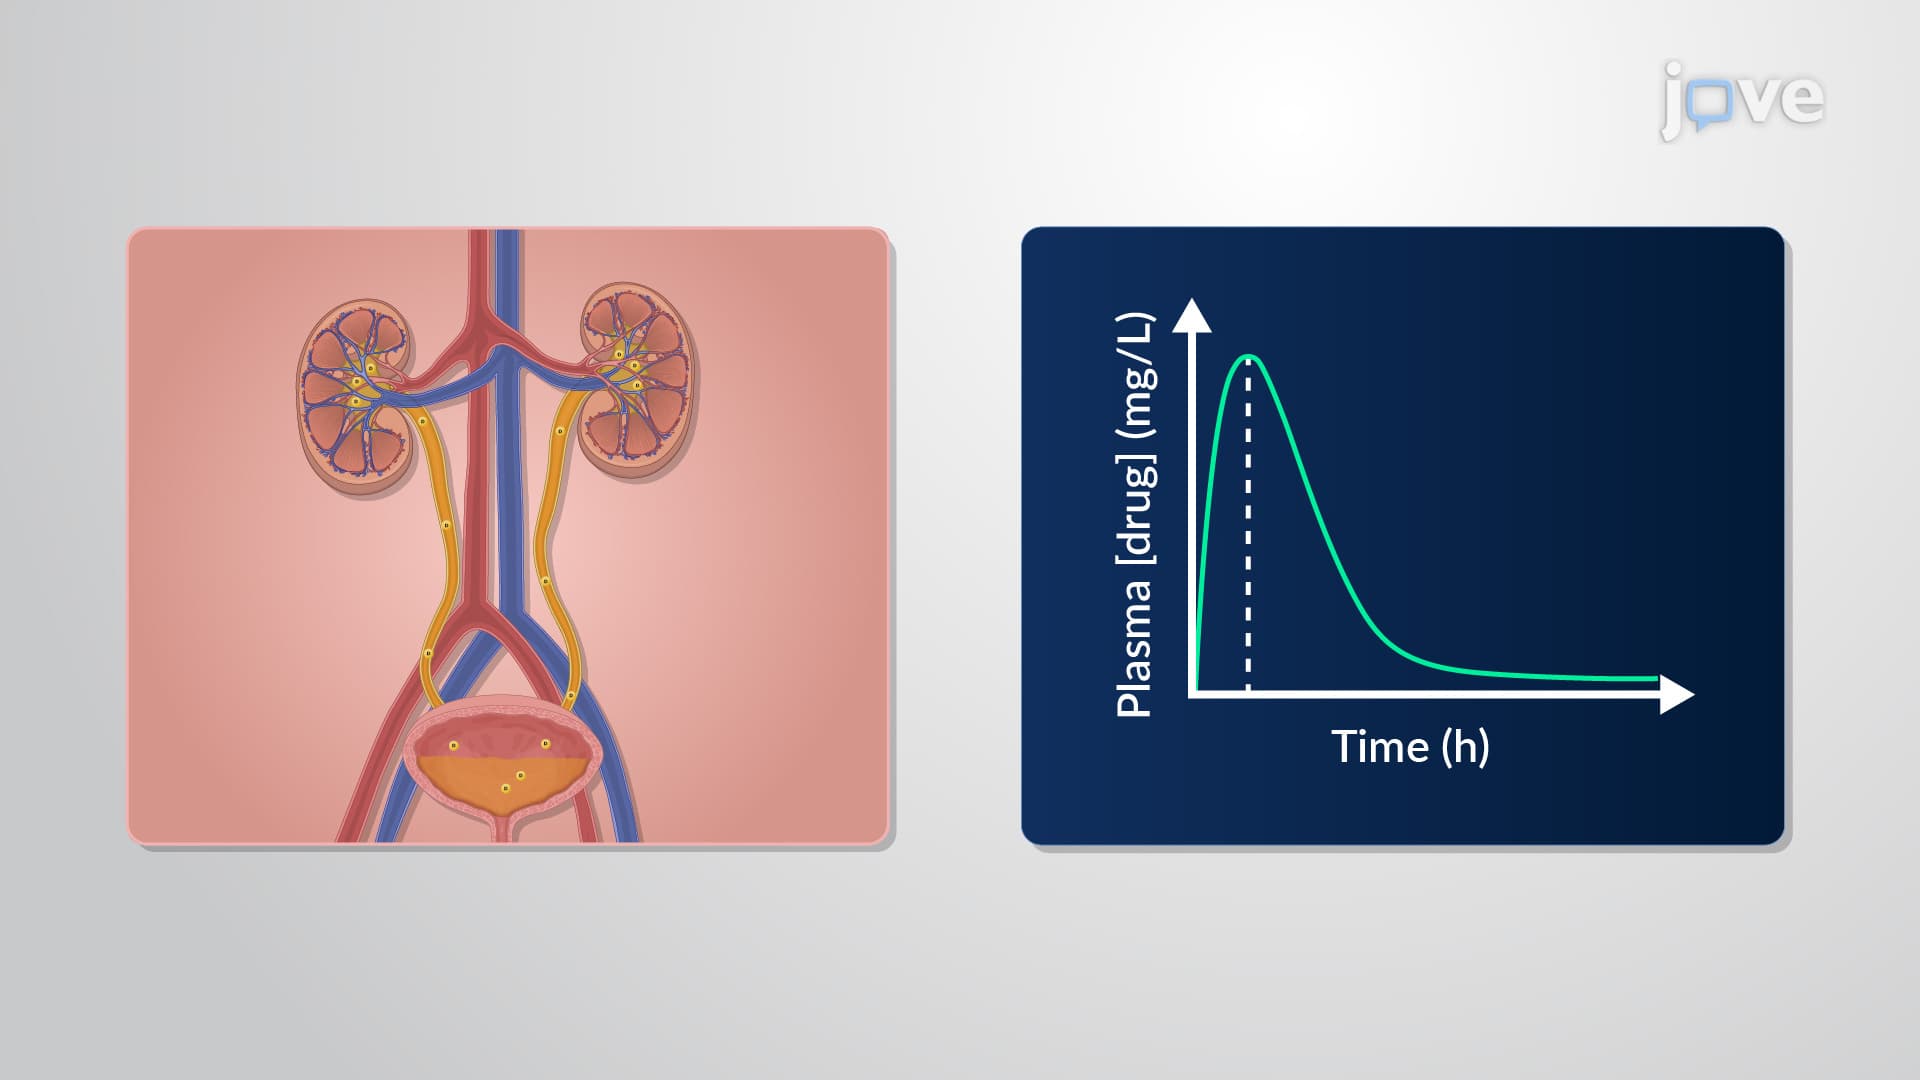
Parameters Affecting Nonlinear Elimination: Zero-Order Input, First-Order Absorption and Two-Compartment Model
When a drug is administered through a constant intravenous infusion and eliminated via nonlinear pharmacokinetics, it follows zero-order input. For example, oral drugs undergo first-order absorption upon administration and are eliminated through nonlinear pharmacokinetics.
In the case of subcutaneously administered drugs,...
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...