Related Experiment Video
Updated: Aug 26, 2025


An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
External Validation of a Multivariable Prediction Model for Placenta Accreta Spectrum
Shubhangi Singh1,2, Daniela A Carusi3, Penny Wang3
1From the Department of Anesthesiology, Perioperative and Pain Medicine, Brigham and Women's Hospital-Harvard Medical School, Boston, Massachusetts.

Background:
Placenta accreta spectrum (PAS) is a disorder of abnormal placentation associated with severe postpartum hemorrhage, maternal morbidity, and mortality. Predelivery prediction of this condition is important to determine appropriate delivery location and multidisciplinary planning for operative management. This study aimed to validate a prediction model for PAS developed by Weiniger et al in 2 cohorts who delivered at 2 different United States tertiary centers.
Methods:
Cohort A (Brigham and Women's Hospital; N = 253) included patients with risk factors (prior cesarean delivery and placenta previa) and/or ultrasound features of PAS presenting to a tertiary-care hospital. Cohort B (Columbia University Irving Medical Center; N = 99) consisted of patients referred to a tertiary-care hospital specifically because of ultrasound features of PAS. Using the outcome variable of surgical and/or pathological diagnosis of PAS, discrimination (via c-statistic), calibration (via intercept, slope, and flexible calibration curve), and clinical usefulness (via decision curve analysis) were determined.
Results:
The model c-statistics in cohorts A and B were 0.728 (95% confidence interval [CI], 0.662-0.794) and 0.866 (95% CI, 0.754-0.977) signifying acceptable and excellent discrimination, respectively. The calibration intercept (0.537 [95% CI, 0.154-0.980] for cohort A and 3.001 [95% CI, 1.899- 4.335] for B), slopes (0.342 [95% CI, 0.170-0.532] for cohort A and 0.604 [95% CI, -0.166 to 1.221] for B), and flexible calibration curves in each cohort indicated that the model underestimated true PAS risks on average and that there was evidence of overfitting in both validation cohorts. The use of the model compared to a treat-all strategy by decision curve analysis showed a greater net benefit of the model at a threshold probability of >0.25 in cohort A. However, no net benefit of the model over the treat-all strategy was seen in cohort B at any threshold probability.
Conclusions:
The performance of the Weiniger model is variable based on the case-mix of the population with regard to PAS clinical risk factors and ultrasound features, highlighting the importance of spectrum bias when applying this PAS prediction model to distinct populations. The model showed benefit for predicting PAS in populations with substantial case-mix heterogeneity at threshold probability of >25%.
Related Concept Videos
 01:13
Sensitivity, Specificity, and Predicted Value
Sensitivity is the...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:19
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:11
Regression Analysis
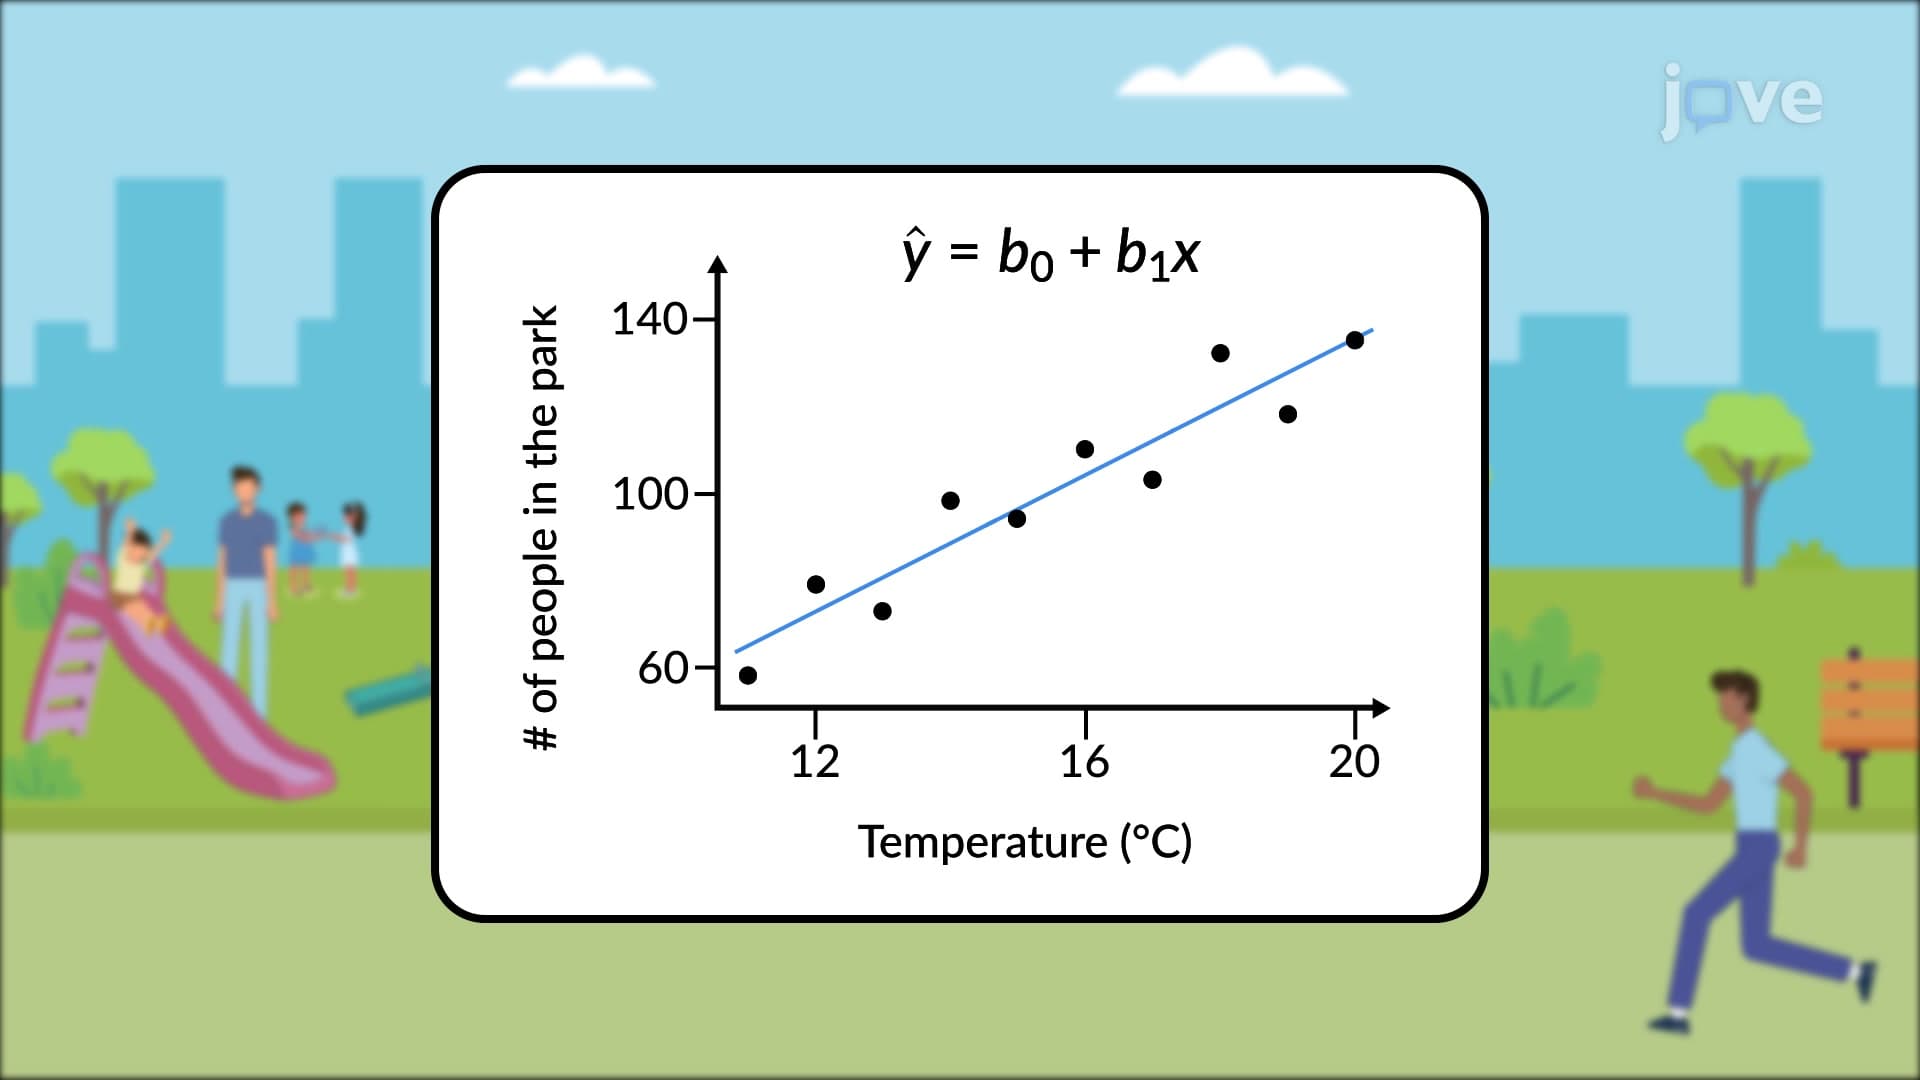
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...