Monotonic Quantile Network for Worst-Case Offline Reinforcement Learning
Related Experiment Video
Updated: Aug 23, 2025

WheelCon: A Wheel Control-Based Gaming Platform for Studying Human Sensorimotor Control
Published on: August 15, 2020

Abstract:
A key challenge in offline reinforcement learning (RL) is how to ensure the learned offline policy is safe, especially in safety-critical domains. In this article, we focus on learning a distributional value function in offline RL and optimizing a worst-case criterion of returns. However, optimizing a distributional value function in offline RL can be hard, since the crossing quantile issue is serious, and the distribution shift problem needs to be addressed. To this end, we propose monotonic quantile network (MQN) with conservative quantile regression (CQR) for risk-averse policy learning. First, we propose an MQN to learn the distribution over returns with non-crossing guarantees of the quantiles. Then, we perform CQR by penalizing the quantile estimation for out-of-distribution (OOD) actions to address the distribution shift in offline RL. Finally, we learn a worst-case policy by optimizing the conditional value-at-risk (CVaR) of the distributional value function. Furthermore, we provide theoretical analysis of the fixed-point convergence in our method. We conduct experiments in both risk-neutral and risk-sensitive offline settings, and the results show that our method obtains safe and conservative behaviors in robotic locomotion tasks.


Related Concept Videos
 01:24
Reinforcement Schedules
Once a behavior is learned,...
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:09
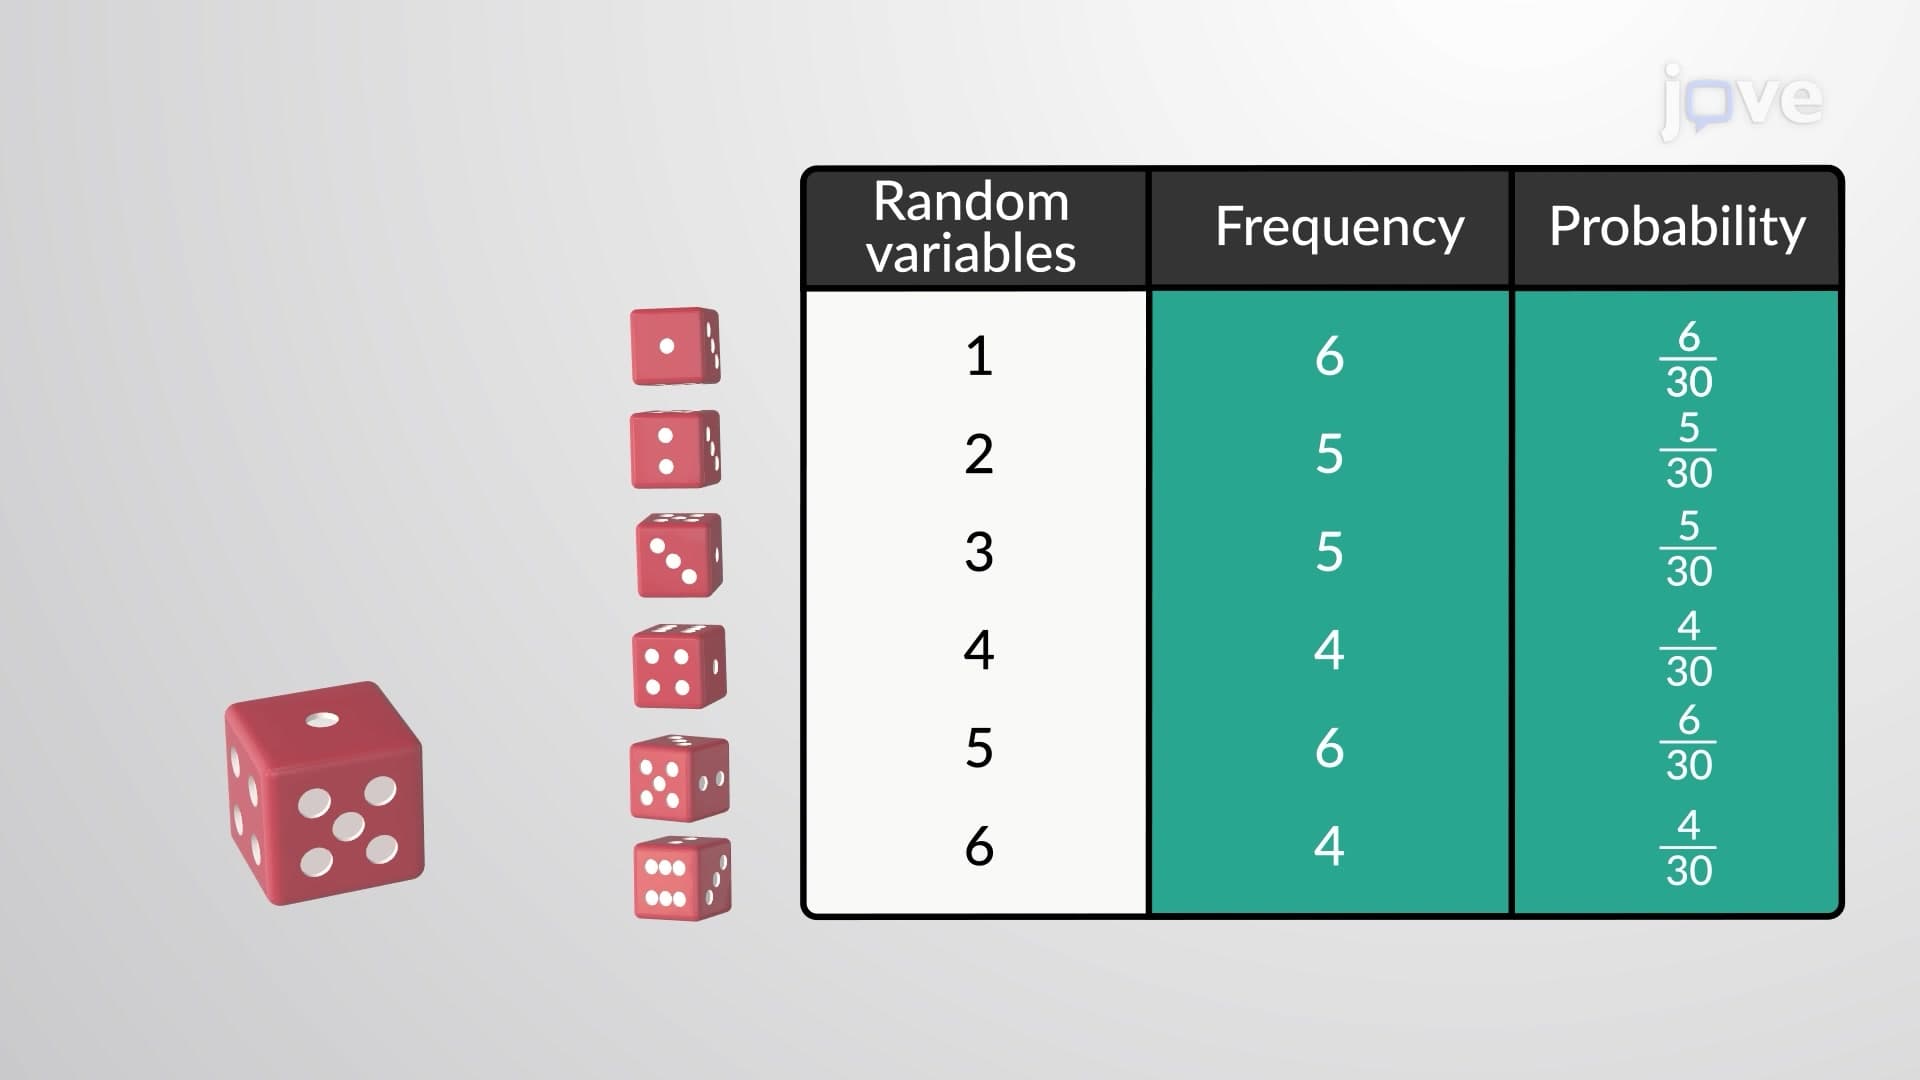
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test