Machine learning approaches for electronic health records phenotyping: a methodical review
Related Experiment Video
Updated: Aug 20, 2025
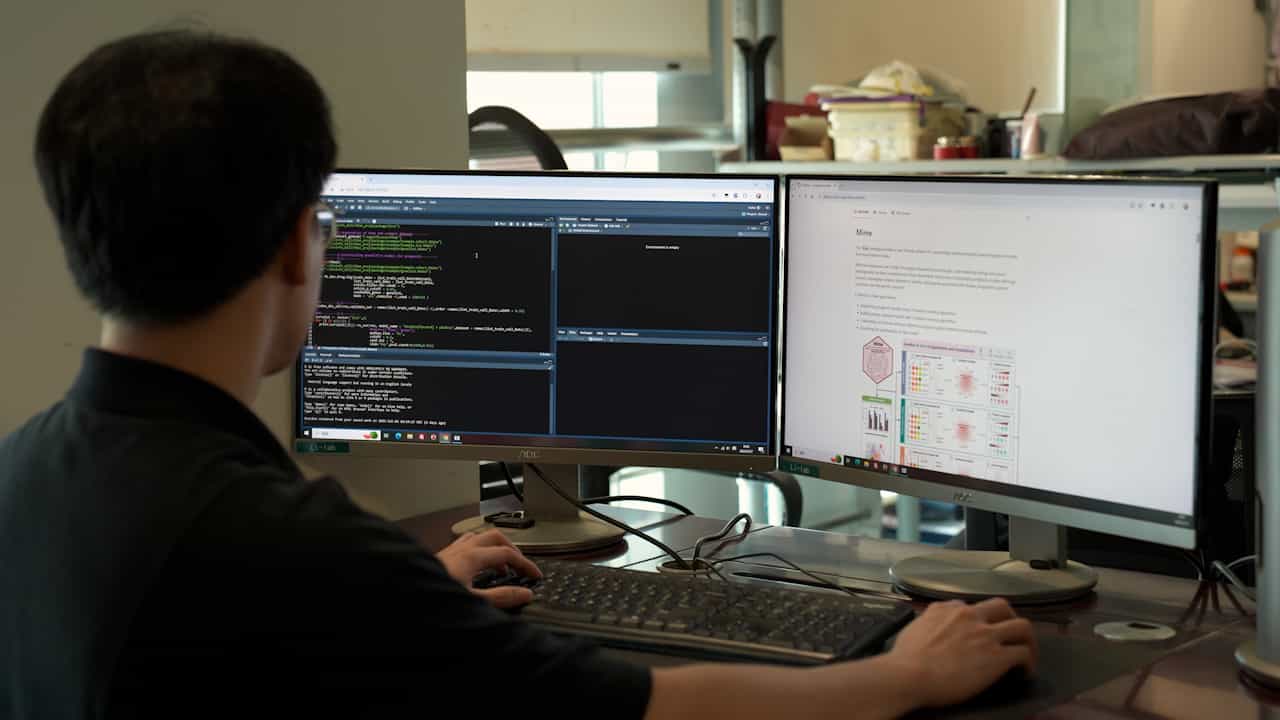
Constructing and Visualizing Models using Mime-based Machine-learning Framework
Published on: July 22, 2025
Siyue Yang1, Paul Varghese2, Ellen Stephenson3
1Department of Statistical Sciences, University of Toronto, Toronto, Ontario, Canada.

Objective:
Accurate and rapid phenotyping is a prerequisite to leveraging electronic health records for biomedical research. While early phenotyping relied on rule-based algorithms curated by experts, machine learning (ML) approaches have emerged as an alternative to improve scalability across phenotypes and healthcare settings. This study evaluates ML-based phenotyping with respect to (1) the data sources used, (2) the phenotypes considered, (3) the methods applied, and (4) the reporting and evaluation methods used.
Materials And Methods:
We searched PubMed and Web of Science for articles published between 2018 and 2022. After screening 850 articles, we recorded 37 variables on 100 studies.
Results:
Most studies utilized data from a single institution and included information in clinical notes. Although chronic conditions were most commonly considered, ML also enabled the characterization of nuanced phenotypes such as social determinants of health. Supervised deep learning was the most popular ML paradigm, while semi-supervised and weakly supervised learning were applied to expedite algorithm development and unsupervised learning to facilitate phenotype discovery. ML approaches did not uniformly outperform rule-based algorithms, but deep learning offered a marginal improvement over traditional ML for many conditions.
Discussion:
Despite the progress in ML-based phenotyping, most articles focused on binary phenotypes and few articles evaluated external validity or used multi-institution data. Study settings were infrequently reported and analytic code was rarely released.
Conclusion:
Continued research in ML-based phenotyping is warranted, with emphasis on characterizing nuanced phenotypes, establishing reporting and evaluation standards, and developing methods to accommodate misclassified phenotypes due to algorithm errors in downstream applications.
More Related Videos
 04:09
Predicting Treatment Response to Image-Guided Therapies Using Machine Learning: An Example for Trans-Arterial Treatment of Hepatocellular Carcinoma
Published on: October 10, 2018
 03:37
Author Spotlight: Impact of Intergenic Interactions on Disease-Identifying Dark Biomarkers
Published on: March 1, 2024
Related Concept Videos
 01:30
Methods of Documentation VII: EMR
 01:12
Analysis of Population Pharmacokinetic Data
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:15
Model Approaches for Pharmacokinetic Data: Physiological Models