Related Experiment Video
Updated: Aug 19, 2025
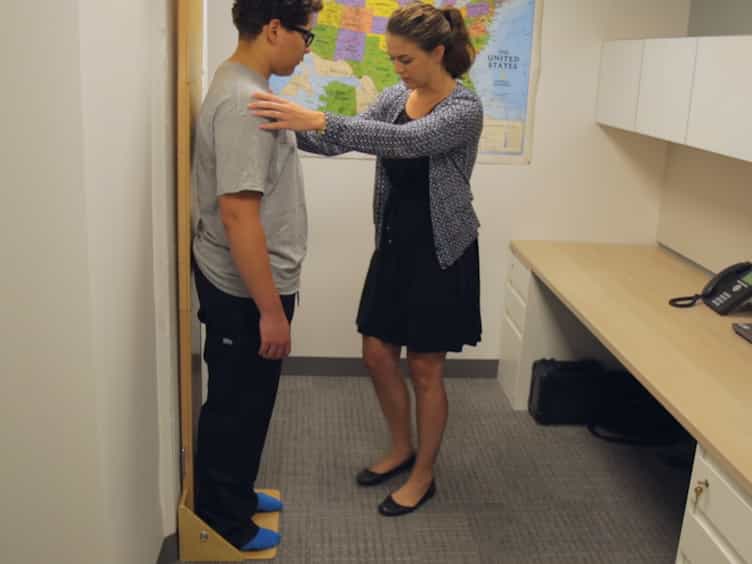

Assessment of Child Anthropometry in a Large Epidemiologic Study
Published on: February 2, 2017
Analysing outlier communities to child birth weight outcomes in Malawi: application of multinomial logistic
Natasha Sakala1, Tsirizani M Kaombe2
1Department of Mathematical Sciences, School of Natural and Applied Sciences, University of Malawi, Zomba, Malawi.

Studies have reported significant effect of geographically shared variables on new-born baby weight. Although there is growing use of community-based child health interventions in public health research, such as through provinces, schools, or health facilities, there has been less interest by researchers to study outlying communities to child birth weight outcomes. We apply multinomial logistic regression model diagnostics to identify outlier communities to child birth weight in Malawi. We use a random sample of 850 clusters, each with at least 7 households based on 2015-16 Malawi demographic and health survey data. There were a total of 11,680 children with measured birth weight, that was categorised as either low ([Formula: see text] grams), normal ([Formula: see text] grams) or high ([Formula: see text] grams). The analyses were done in STATA version 15 and R version 3.6.3. Based on a multinomial logit model with various socio-demographic factors associated with child birth weight, the results showed that two clusters from rural parts of Southern region of Malawi had overly influence on estimated effects of the factors on birth weight. Both clusters had normal to high birth weight babies, with no child having low birth weight. There could be some desired motherhood practices applied by mothers in the two rural clusters worth learning from by policy makers in the child healthcare sector.
Studies have reported significant effect of geographically shared variables on new-born baby weight. Although there is growing use of community-based child health interventions in public health research, such as through provinces, schools, or health facilities, there has been less interest by researchers to study outlying communities to child birth weight outcomes. We apply multinomial logistic regression model diagnostics to identify outlier communities to child birth weight in Malawi. We use a random sample of 850 clusters, each with at least 7 households based on 2015-16 Malawi demographic and health survey data. There were a total of 11,680 children with measured birth weight, that was categorised as either low ([Formula: see text] grams), normal ([Formula: see text] grams) or high ([Formula: see text] grams). The analyses were done in STATA version 15 and R version 3.6.3. Based on a multinomial logit model with various socio-demographic factors associated with child birth weight, the results showed that two clusters from rural parts of Southern region of Malawi had overly influence on estimated effects of the factors on birth weight. Both clusters had normal to high birth weight babies, with no child having low birth weight. There could be some desired motherhood practices applied by mothers in the two rural clusters worth learning from by policy makers in the child healthcare sector.
More Related Videos
Related Concept Videos
 01:08
Outliers and Influential Points
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 01:12
What Are Outliers?
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
 01:52
Regression Toward the Mean
 01:17
z Scores and Area Under the Curve
 01:20
Comparing the Survival Analysis of Two or More Groups