CLIP knows image aesthetics
Related Experiment Video
Updated: Aug 17, 2025
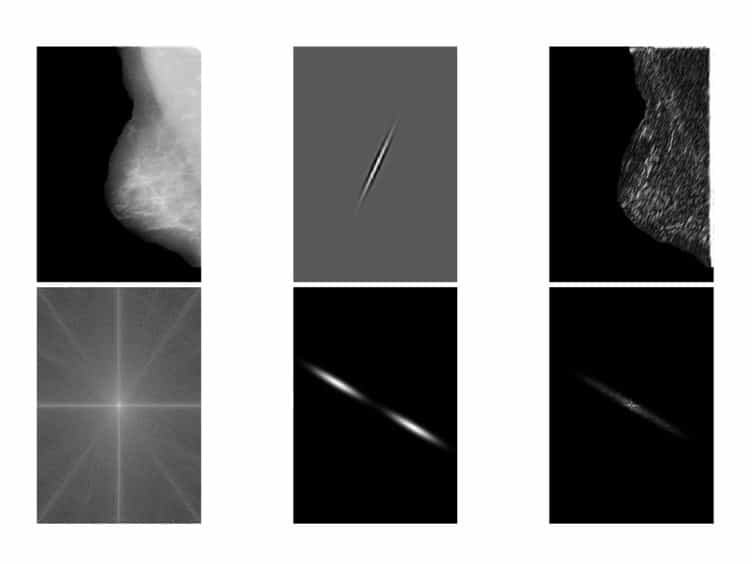
Detection of Architectural Distortion in Prior Mammograms via Analysis of Oriented Patterns
Published on: August 30, 2013
Simon Hentschel1, Konstantin Kobs1, Andreas Hotho1
1Chair of Data Science, Institute of Computer Science, Julius-Maximilians-Universität of Würzburg, Würzburg, Germany.

Abstract:
Most Image Aesthetic Assessment (IAA) methods use a pretrained ImageNet classification model as a base to fine-tune. We hypothesize that content classification is not an optimal pretraining task for IAA, since the task discourages the extraction of features that are useful for IAA, e.g., composition, lighting, or style. On the other hand, we argue that the Contrastive Language-Image Pretraining (CLIP) model is a better base for IAA models, since it has been trained using natural language supervision. Due to the rich nature of language, CLIP needs to learn a broad range of image features that correlate with sentences describing the image content, composition, environments, and even subjective feelings about the image. While it has been shown that CLIP extracts features useful for content classification tasks, its suitability for tasks that require the extraction of style-based features like IAA has not yet been shown. We test our hypothesis by conducting a three-step study, investigating the usefulness of features extracted by CLIP compared to features obtained from the last layer of a comparable ImageNet classification model. In each step, we get more computationally expensive. First, we engineer natural language prompts that let CLIP assess an image's aesthetic without adjusting any weights in the model. To overcome the challenge that CLIP's prompting only is applicable to classification tasks, we propose a simple but effective strategy to convert multiple prompts to a continuous scalar as required when predicting an image's mean aesthetic score. Second, we train a linear regression on the AVA dataset using image features obtained by CLIP's image encoder. The resulting model outperforms a linear regression trained on features from an ImageNet classification model. It also shows competitive performance with fully fine-tuned networks based on ImageNet, while only training a single layer. Finally, by fine-tuning CLIP's image encoder on the AVA dataset, we show that CLIP only needs a fraction of training epochs to converge, while also performing better than a fine-tuned ImageNet model. Overall, our experiments suggest that CLIP is better suited as a base model for IAA methods than ImageNet pretrained networks.
Related Concept Videos
 01:12
Modeling and Similitude
 01:21
Gestalt Principles of Perception
 01:09
Types of Skewness
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...
 01:09
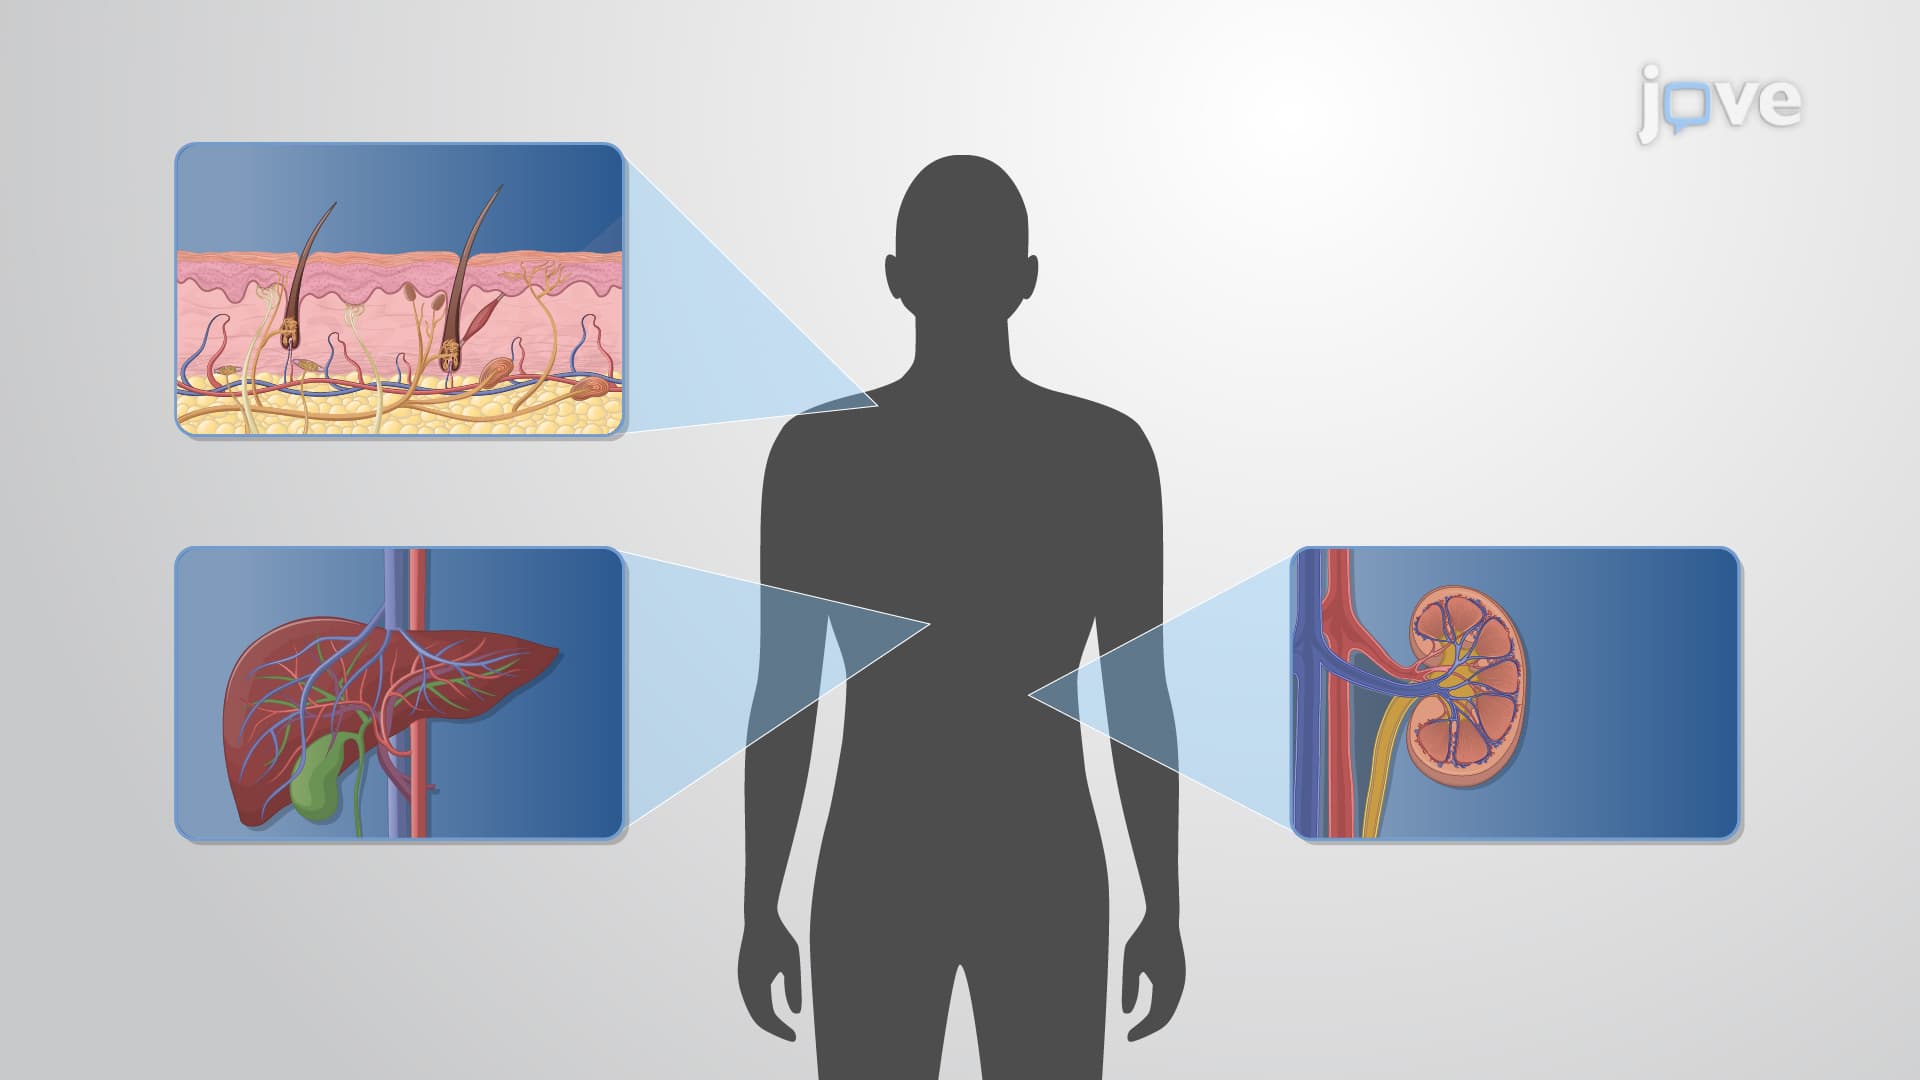
Clearance Models: Physiological Models
The organ's clearance rate depends on the blood flow to the organ and the extraction ratio (E). The extraction ratio describes the organ's...
 01:24
Concepts and Prototypes
The brain organizes this information using concepts, which are mental categories grouping linguistic data,...
 01:21
Deformations in a Transverse Cross Section
As the material stretches, it expands or contracts in orthogonal directions to the load. This phenomenon varies...