Related Experiment Video
Updated: Aug 16, 2025

Author Spotlight: Assessment of Visual Acuity in Central Vision Loss Through Motion-Based Peripheral Vision Testing
Published on: February 23, 2024
A Robust Method: Arbitrary Shape Text Detection Combining Semantic and Position Information
Zhenchao Wang1, Wushour Silamu1, Yuze Li1
1Xinjiang Multilingual Information Technology Laboratory, Xinjiang Multilingual Information Technology Research Center, College of Information Science and Engineering, Xinjiang University, Urumqi 830017, China.

Abstract:
There is a growing interest in scene text detection for arbitrary shapes. The effectiveness of text detection has also evolved from horizontal text detection to the ability to perform text detection in multiple directions and arbitrary shapes. However, scene text detection is still a challenging task due to significant differences in size and aspect ratio and diversity in shape, as well as orientation, coarse annotations, and other factors. Regression-based methods are inspired by object detection and have limitations in fitting the edges of arbitrarily shaped text due to the characteristics of their methods. Segmentation-based methods, on the other hand, perform prediction at the pixel level and thus can fit arbitrarily shaped text better. However, the inaccuracy of image text annotations and the distribution characteristics of text pixels, which contain a large number of background pixels and misclassified pixels, degrades the performance of segmentation-based text detection methods to some extent. Usually, considering whether a pixel belongs to a text region is highly dependent on the strength of the semantic information it has and the position of the pixel in the text area. Based on the above two points, we propose an innovative and robust method for scene text detection combining position and semantic information. First, we add position information to the images using a position encoding module (PosEM) to help the model learn the implicit feature relationships associated with the position. Second, we use the semantic enhancement module (SEM) to enhance the model's focus on the semantic information in the image during feature extraction. Then, to minimize the effect of noise due to inaccurate image text annotations and the distribution characteristics of text pixels, we convert the detection results into a probability map that can more reasonably represent the text distribution. Finally, we reconstruct and filter the text instances using a post-processing algorithm to reduce false positives. The experimental results show that our model improves significantly on the Total-Text, MSRA-TD500, and CTW1500 datasets, outperforming most previous advanced algorithms.
More Related Videos
 08:25
Combining Eye-tracking Data with an Analysis of Video Content from Free-viewing a Video of a Walk in an Urban Park Environment
Published on: May 7, 2019
 05:57
Long-term Video Tracking of Cohoused Aquatic Animals: A Case Study of the Daily Locomotor Activity of the Norway Lobster Nephrops norvegicus
Published on: April 8, 2019
Related Concept Videos
 01:25
Shape and Texture of Coarse Aggregate
 01:29
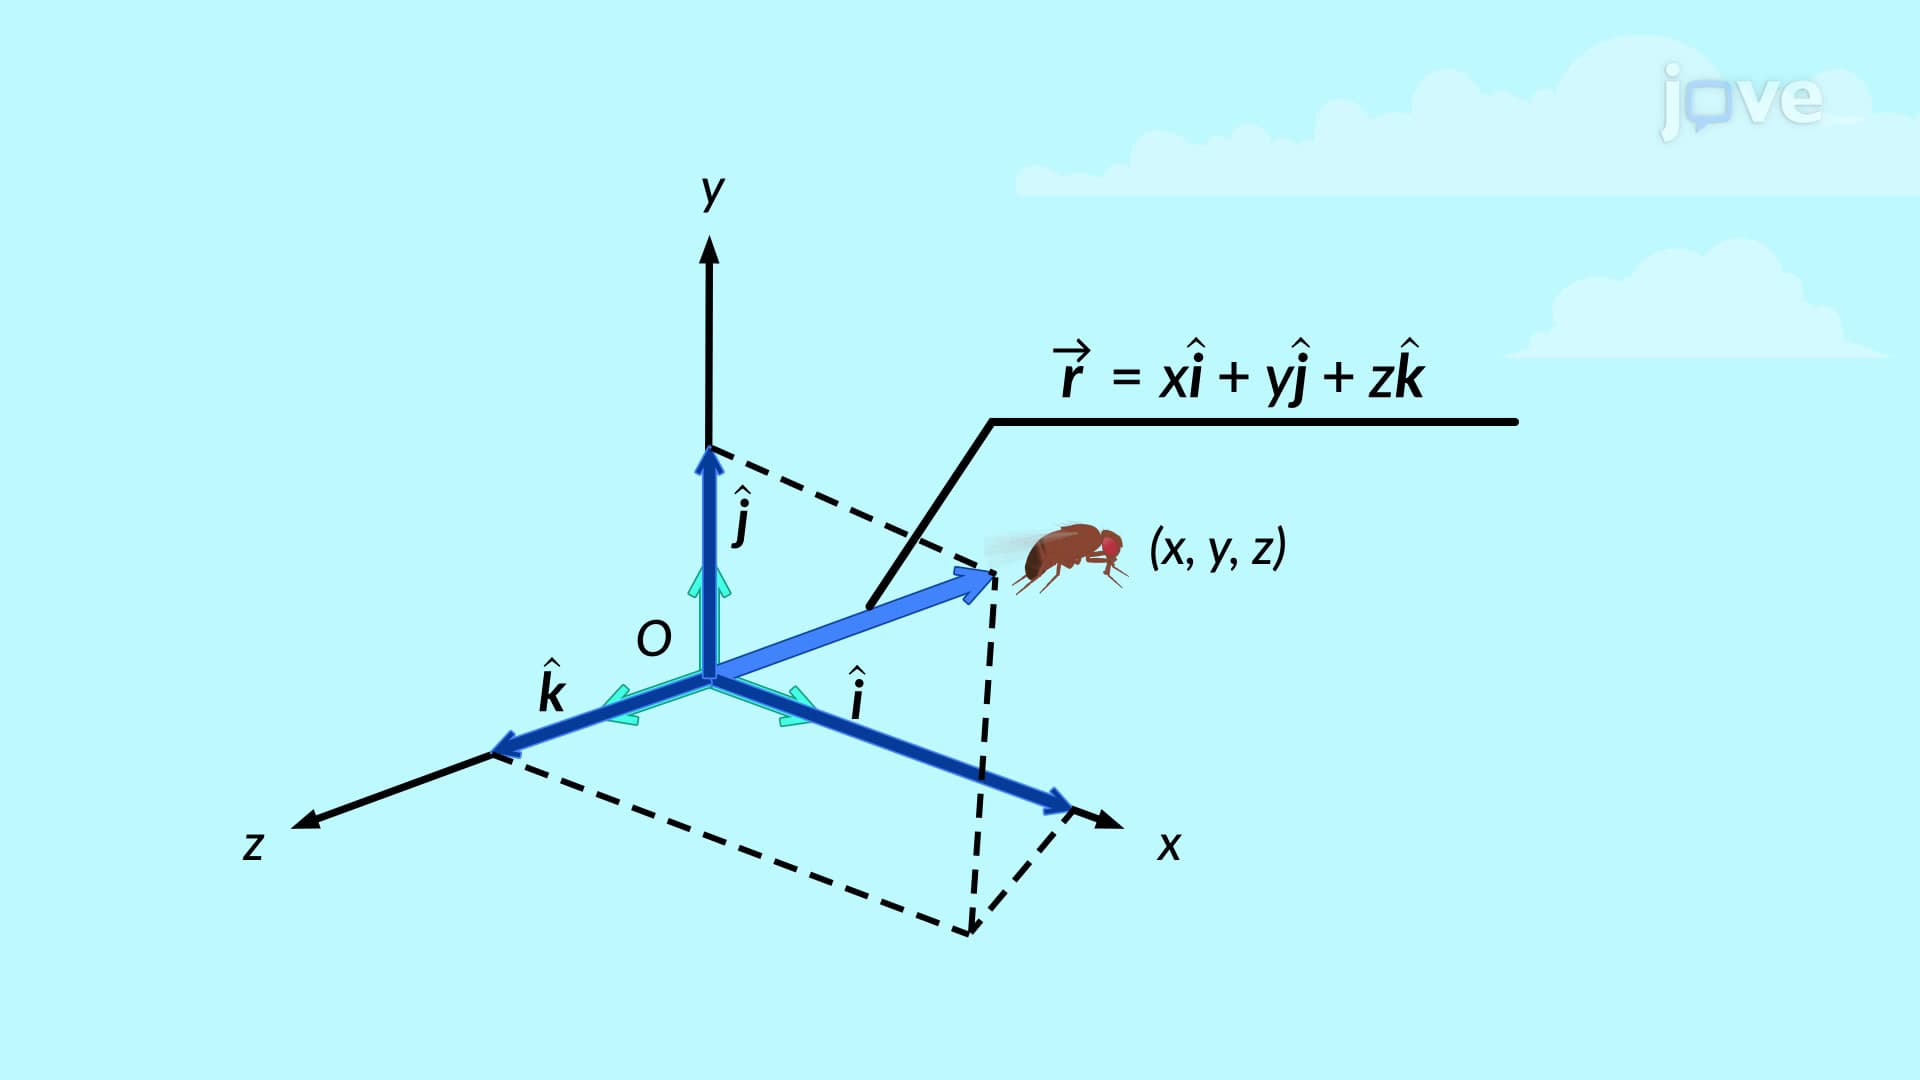
Position Vectors
For instance, we want to locate a point P(x, y, z) relative to the origin of coordinates O. In that case, we can define a position...
 01:00
Position and Displacement Vectors
Further, several important kinds of...
 02:32
Position-effect Variegation
 02:52
VSEPR Theory and the Basic Shapes