An immediate-return reinforcement learning for the atypical Markov decision processes
Related Experiment Video
Updated: Aug 15, 2025
Operant Protocols for Assessing the Cost-benefit Analysis During Reinforced Decision Making by Rodents
Published on: September 10, 2018
Zebang Pan1, Guilin Wen1,2, Zhao Tan1
1State Key Laboratory of Advanced Design and Manufacturing for Vehicle Body, Hunan University, Changsha, Hunan, China.

Abstract:
The atypical Markov decision processes (MDPs) are decision-making for maximizing the immediate returns in only one state transition. Many complex dynamic problems can be regarded as the atypical MDPs, e.g., football trajectory control, approximations of the compound Poincaré maps, and parameter identification. However, existing deep reinforcement learning (RL) algorithms are designed to maximize long-term returns, causing a waste of computing resources when applied in the atypical MDPs. These existing algorithms are also limited by the estimation error of the value function, leading to a poor policy. To solve such limitations, this paper proposes an immediate-return algorithm for the atypical MDPs with continuous action space by designing an unbiased and low variance target Q-value and a simplified network framework. Then, two examples of atypical MDPs considering the uncertainty are presented to illustrate the performance of the proposed algorithm, i.e., passing the football to a moving player and chipping the football over the human wall. Compared with the existing deep RL algorithms, such as deep deterministic policy gradient and proximal policy optimization, the proposed algorithm shows significant advantages in learning efficiency, the effective rate of control, and computing resource usage.
More Related Videos
Related Concept Videos
 01:08
Timing and Consequences on Behavior
Humans, however, can respond to delayed reinforcers. We often make decisions between immediate small rewards and delayed larger rewards. This ability to delay gratification is a significant...
 01:09
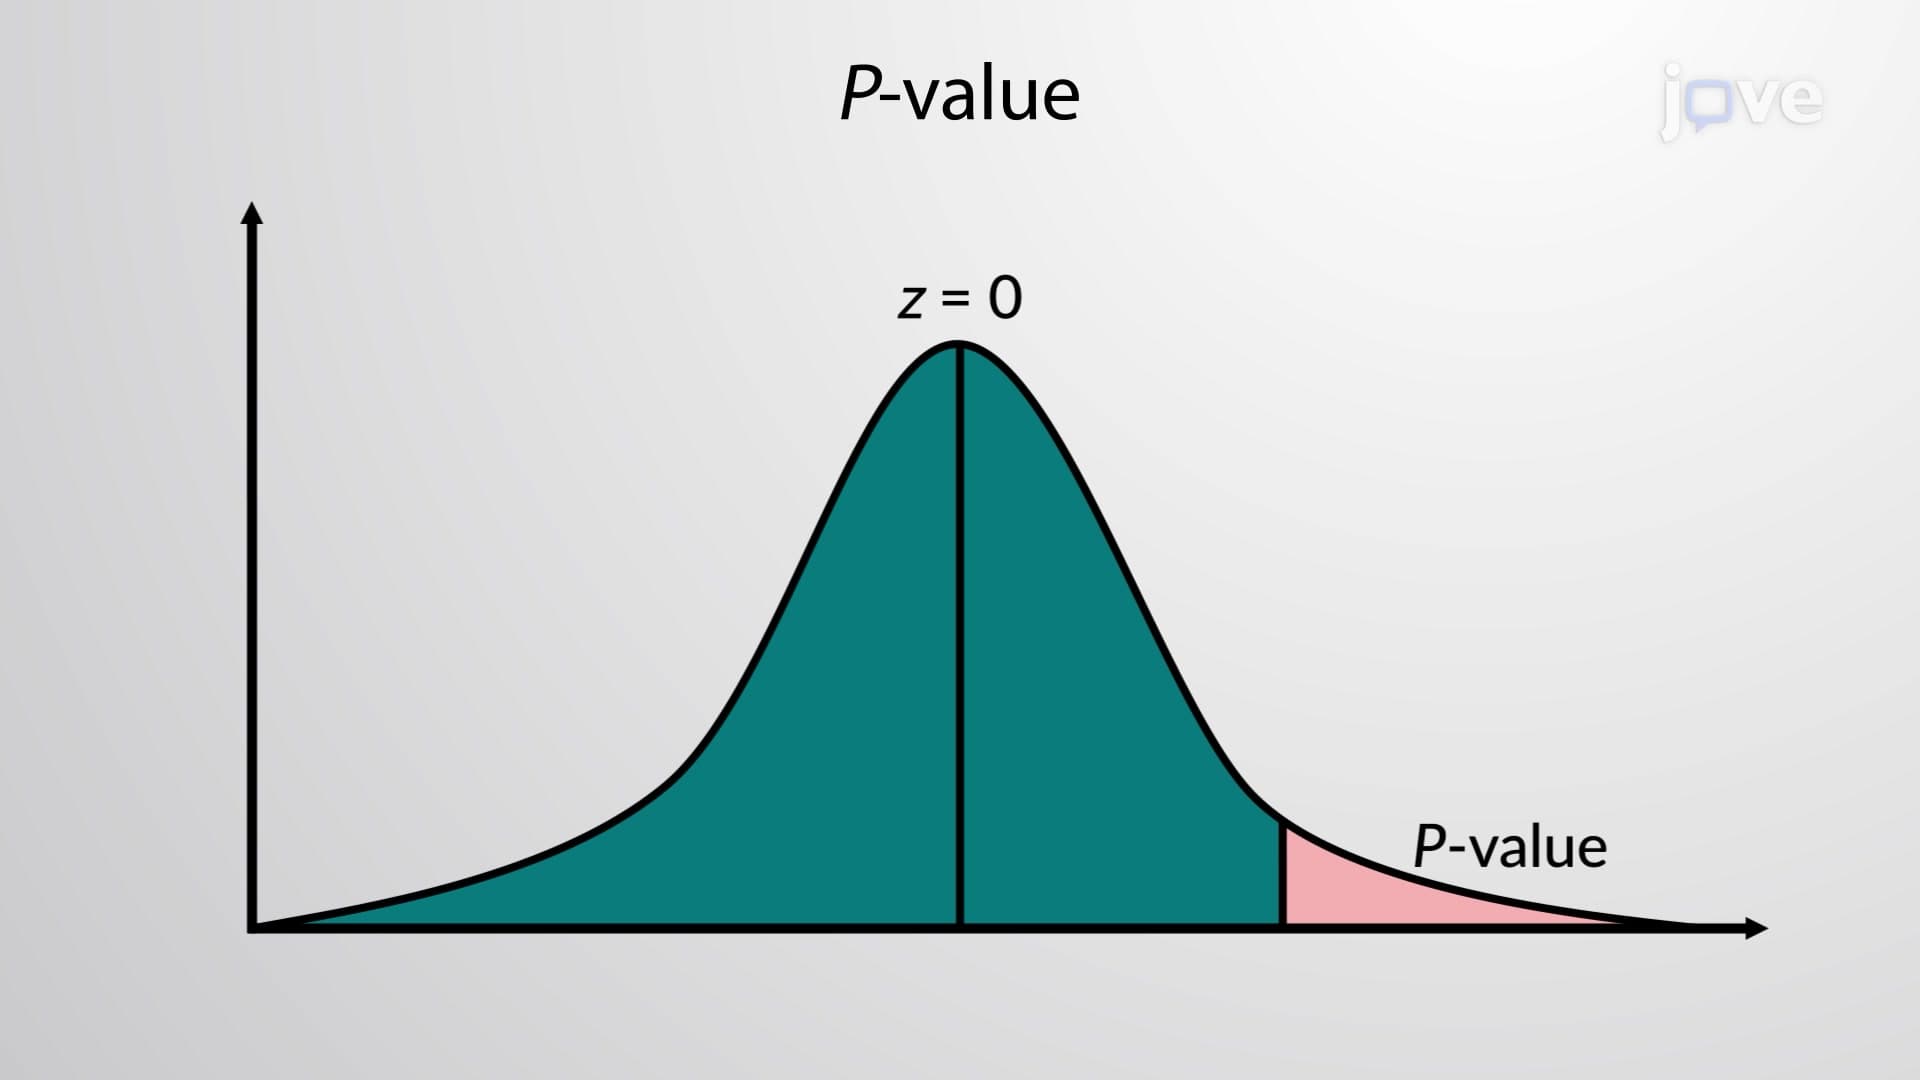
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 01:24
Reinforcement Schedules
Once a behavior is learned,...
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:14
Decision Making: Traditional Method
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...
 01:34
Woodward–Hoffmann Selection Rules and Microscopic Reversibility