Related Experiment Video
Updated: Aug 12, 2025

A Psychophysics Paradigm for the Collection and Analysis of Similarity Judgments
Published on: March 1, 2022
Identification of outlying observations for large-dimensional data
Tao Wang1, Xiaona Yang2, Yunfei Guo3,4
1School of Mathematics and Statistics, Huaiyin Normal University, Huaian City, People's Republic of China.

Abstract:
This work proposes a two-stage procedure for identifying outlying observations in a large-dimensional data set. In the first stage, an outlier identification measure is defined by using a max-normal statistic and a clean subset that contains non-outliers is obtained. The identification of outliers can be deemed as a multiple hypothesis testing problem, then, in the second stage, we explore the asymptotic distribution of the proposed measure, and obtain the threshold of the outlying observations. Furthermore, in order to improve the identification power and better control the misjudgment rate, a one-step refined algorithm is proposed. Simulation results and two real data analysis examples show that, compared with other methods, the proposed procedure has great advantages in identifying outliers in various data situations.
More Related Videos
 14:27
Identification of Disease-related Spatial Covariance Patterns using Neuroimaging Data
Published on: June 26, 2013
 12:27
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
Related Concept Videos
 01:08
Outliers and Influential Points
 01:12
What Are Outliers?
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 01:00
Detection of Gross Error: The Q Test
 00:57
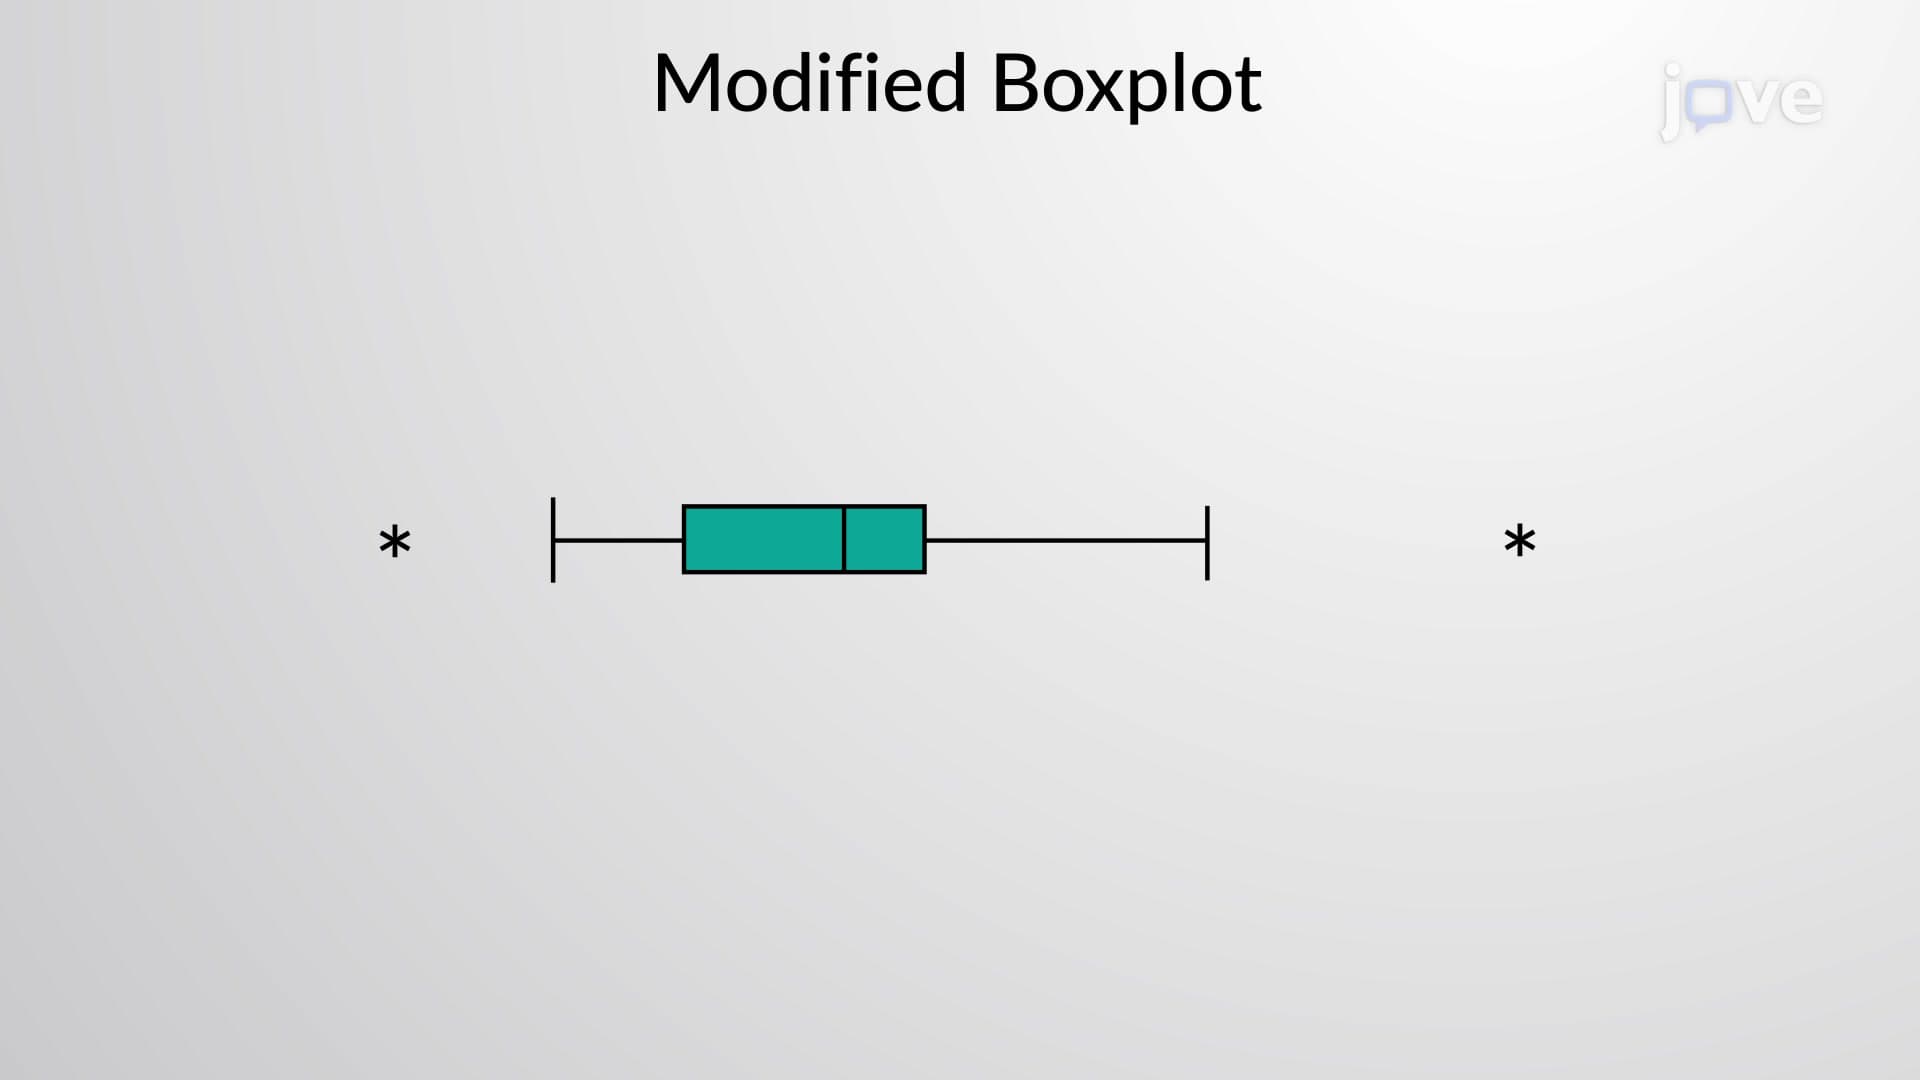
Modified Boxplots
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
 01:16
Unusual Results
According to the range rule of thumb, any value above or below two standard deviations, 2σ from the mean, μ is considered unusual.
Maximum unusual value =...