
Chemical identification and indexing in full-text articles: an overview of the NLM-Chem track at BioCreative VII
Robert Leaman1, Rezarta Islamaj1, Virginia Adams2
1National Center for Biotechnology Information (NCBI), National Library of Medicine, National Institutes of Health, 8600 Rockville Pike, Bethesda, MD 20894, USA.

Abstract:
The BioCreative National Library of Medicine (NLM)-Chem track calls for a community effort to fine-tune automated recognition of chemical names in the biomedical literature. Chemicals are one of the most searched biomedical entities in PubMed, and-as highlighted during the coronavirus disease 2019 pandemic-their identification may significantly advance research in multiple biomedical subfields. While previous community challenges focused on identifying chemical names mentioned in titles and abstracts, the full text contains valuable additional detail. We, therefore, organized the BioCreative NLM-Chem track as a community effort to address automated chemical entity recognition in full-text articles. The track consisted of two tasks: (i) chemical identification and (ii) chemical indexing. The chemical identification task required predicting all chemicals mentioned in recently published full-text articles, both span [i.e. named entity recognition (NER)] and normalization (i.e. entity linking), using Medical Subject Headings (MeSH). The chemical indexing task required identifying which chemicals reflect topics for each article and should therefore appear in the listing of MeSH terms for the document in the MEDLINE article indexing. This manuscript summarizes the BioCreative NLM-Chem track and post-challenge experiments. We received a total of 85 submissions from 17 teams worldwide. The highest performance achieved for the chemical identification task was 0.8672 F-score (0.8759 precision and 0.8587 recall) for strict NER performance and 0.8136 F-score (0.8621 precision and 0.7702 recall) for strict normalization performance. The highest performance achieved for the chemical indexing task was 0.6073 F-score (0.7417 precision and 0.5141 recall). This community challenge demonstrated that (i) the current substantial achievements in deep learning technologies can be utilized to improve automated prediction accuracy further and (ii) the chemical indexing task is substantially more challenging. We look forward to further developing biomedical text-mining methods to respond to the rapid growth of biomedical literature. The NLM-Chem track dataset and other challenge materials are publicly available at https://ftp.ncbi.nlm.nih.gov/pub/lu/BC7-NLM-Chem-track/. Database URL https://ftp.ncbi.nlm.nih.gov/pub/lu/BC7-NLM-Chem-track/.
More Related Videos
 08:20
Systematic Approach to Identify Novel Antimicrobial and Antibiofilm Molecules from Plants' Extracts and Fractions to Prevent Dental Caries
Published on: March 31, 2021
 05:35
An Integrated Workflow of Identification and Quantification on FDR Control-Based Untargeted Metabolome
Published on: September 20, 2022
Related Concept Videos
 02:39
Indicators
 01:27
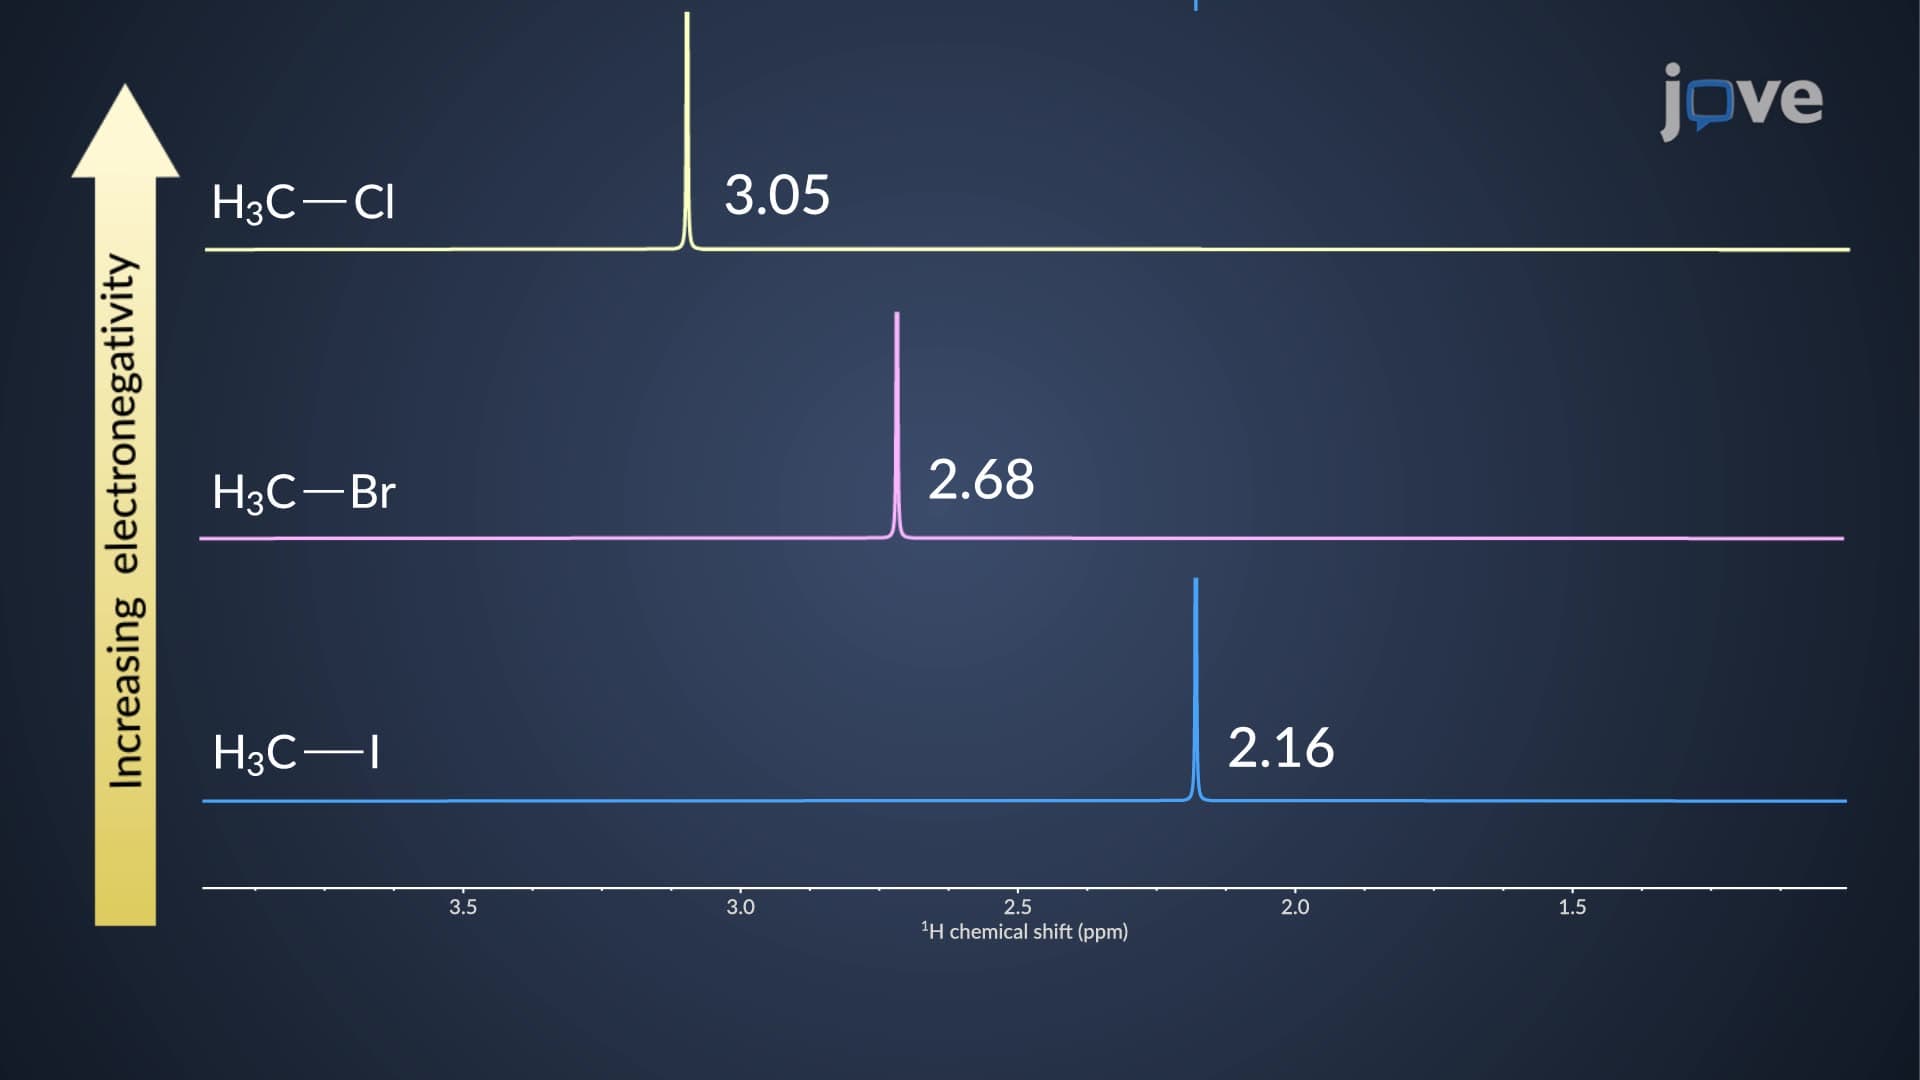
Inductive Effects on Chemical Shift: Overview
 01:19
Mass Spectrometry: Overview
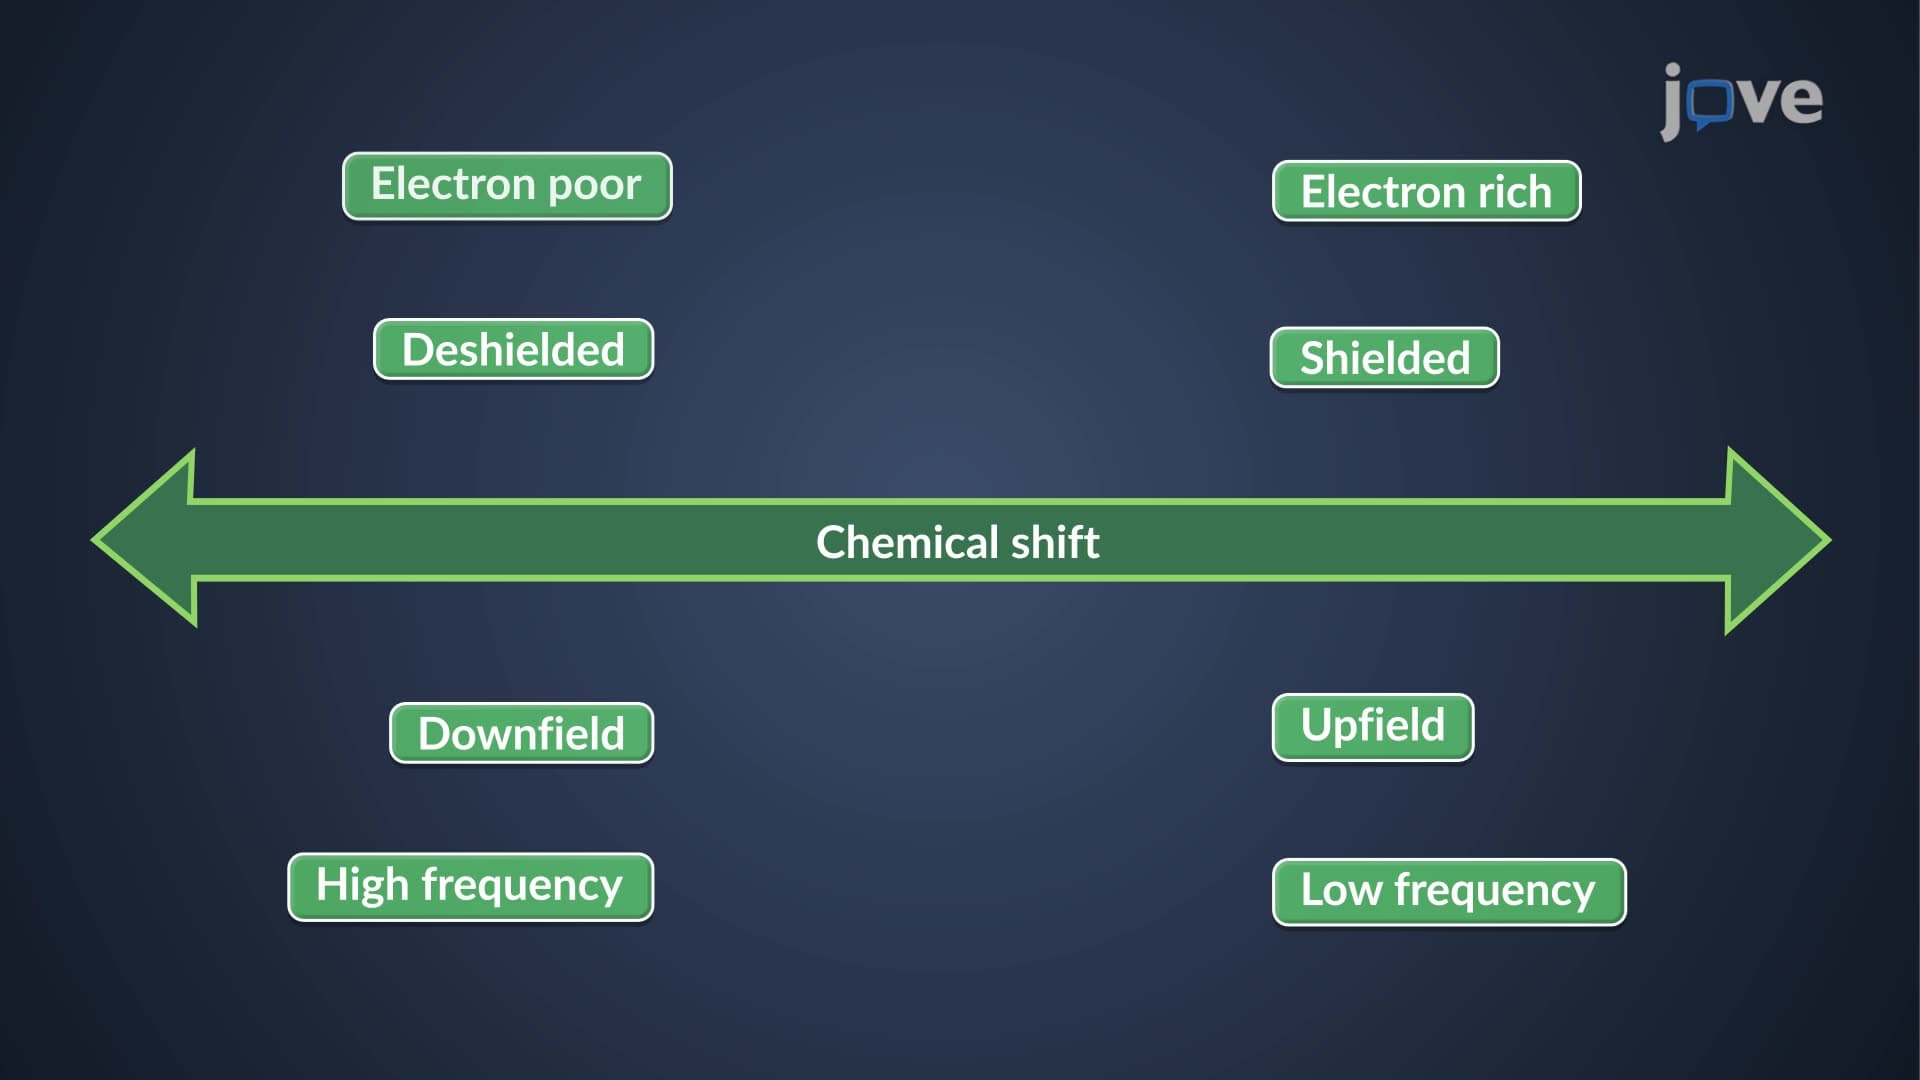 01:15
NMR Spectroscopy: Chemical Shift Overview
For instance, the proton...
 01:19
MALDI-TOF Mass Spectrometry
 01:17
Chemical Shift: Internal References and Solvent Effects
The internal reference compound generally used in NMR spectroscopy is tetramethylsilane (TMS). TMS is preferred because it is chemically inert, soluble in NMR solvents, and easily removable. Also, the highly shielded methyl protons in TMS yield an intense...