Related Experiment Video
Updated: Aug 5, 2025


Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Bayesian clustering of multiple zero-inflated outcomes
Beatrice Franzolini1, Andrea Cremaschi1, Willem van den Boom2
1Singapore Institute for Clinical Sciences (SICS), Agency for Science, Technology and Research (A*STAR), Singapore, Republic of Singapore.

Abstract:
Several applications involving counts present a large proportion of zeros (excess-of-zeros data). A popular model for such data is the hurdle model, which explicitly models the probability of a zero count, while assuming a sampling distribution on the positive integers. We consider data from multiple count processes. In this context, it is of interest to study the patterns of counts and cluster the subjects accordingly. We introduce a novel Bayesian approach to cluster multiple, possibly related, zero-inflated processes. We propose a joint model for zero-inflated counts, specifying a hurdle model for each process with a shifted Negative Binomial sampling distribution. Conditionally on the model parameters, the different processes are assumed independent, leading to a substantial reduction in the number of parameters as compared with traditional multivariate approaches. The subject-specific probabilities of zero-inflation and the parameters of the sampling distribution are flexibly modelled via an enriched finite mixture with random number of components. This induces a two-level clustering of the subjects based on the zero/non-zero patterns (outer clustering) and on the sampling distribution (inner clustering). Posterior inference is performed through tailored Markov chain Monte Carlo schemes. We demonstrate the proposed approach on an application involving the use of the messaging service WhatsApp. This article is part of the theme issue 'Bayesian inference: challenges, perspectives, and prospects'.
More Related Videos


Related Concept Videos
 01:20
Comparing the Survival Analysis of Two or More Groups
 01:09
Truncation in Survival Analysis
Left truncation occurs when individuals who experienced the event of interest before a certain time are not included in the study. This is often due to a "delayed entry" into the study where only those who survive until a certain entry point are...
 01:15
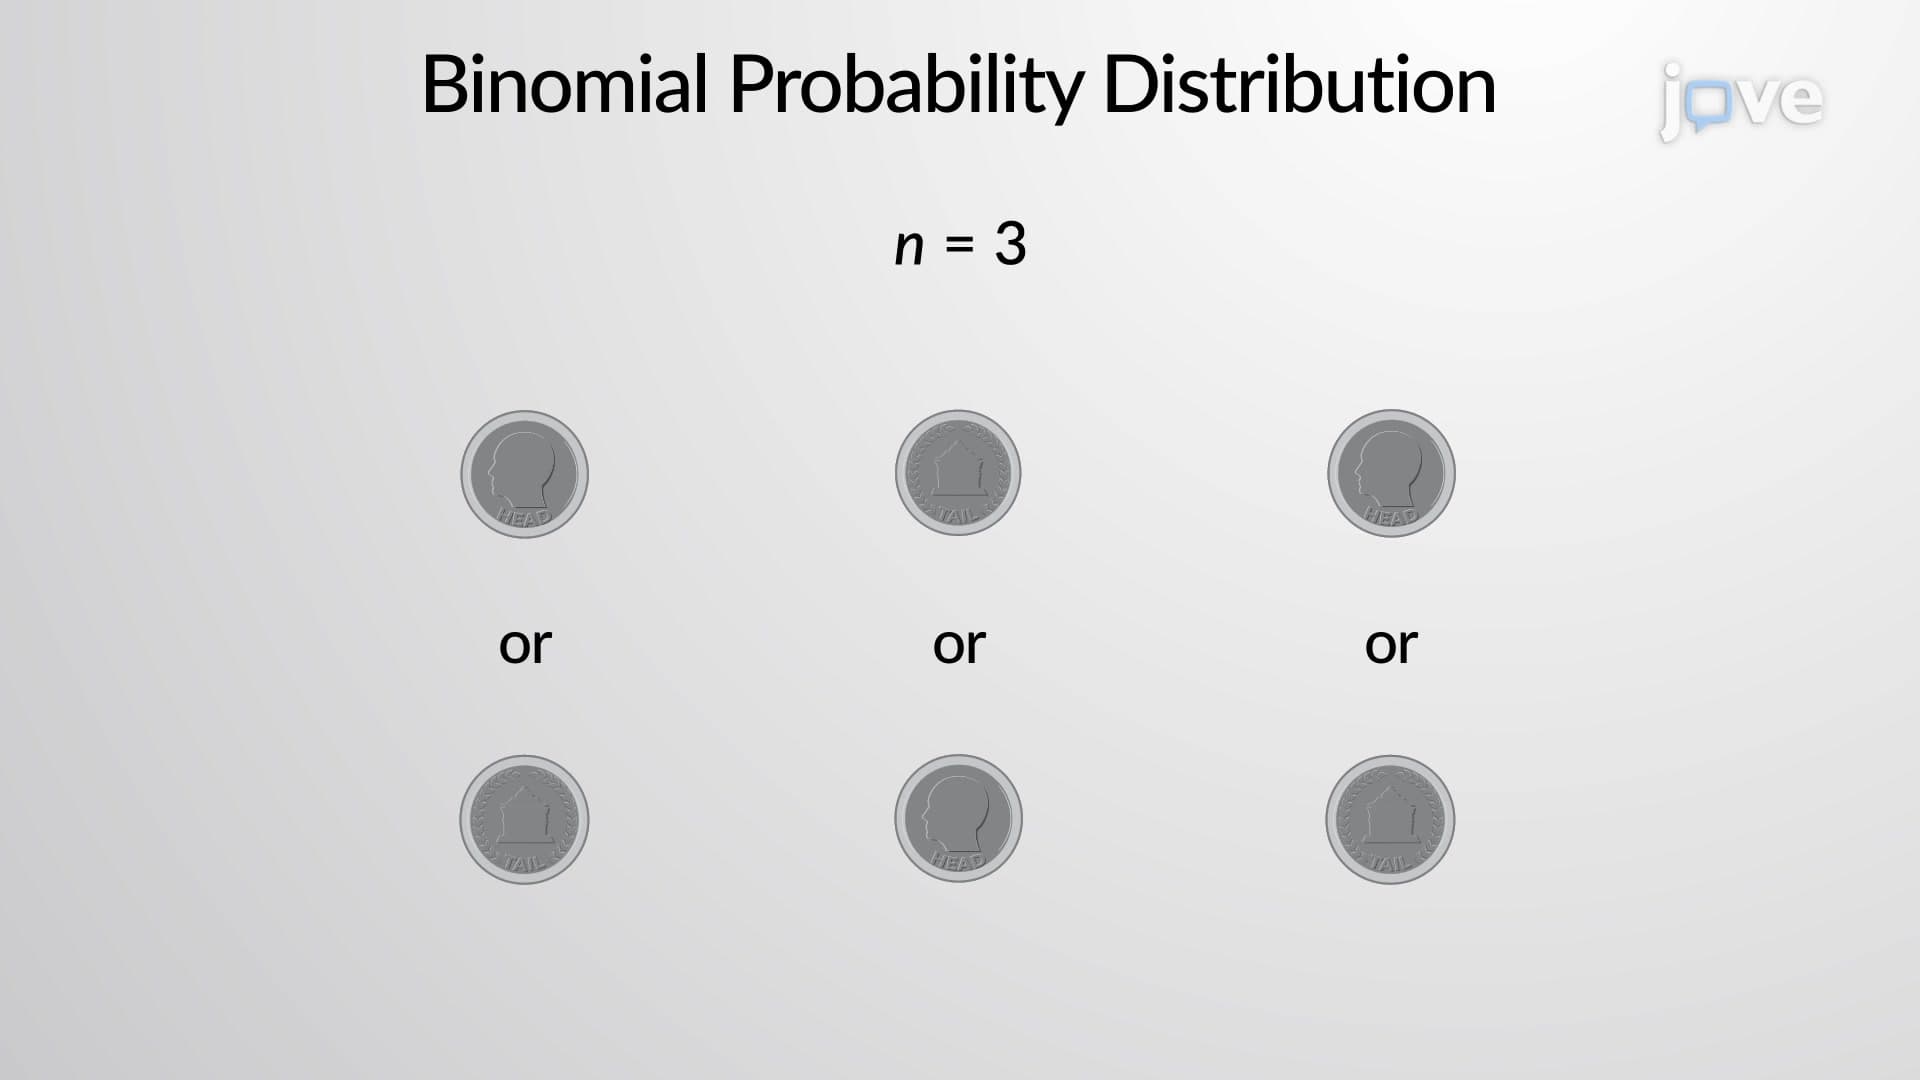
Binomial Probability Distribution
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
 01:29
Contingency Table
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:21
Friedman Two-way Analysis of Variance by Ranks