K-Means Clustering With Natural Density Peaks for Discovering Arbitrary-Shaped Clusters
Related Experiment Video
Updated: Aug 3, 2025
Determination of Aggregate Surface Morphology at the Interfacial Transition Zone ITZ
Published on: December 16, 2019

Abstract:
Due to simplicity, K-means has become a widely used clustering method. However, its clustering result is seriously affected by the initial centers and the allocation strategy makes it hard to identify manifold clusters. Many improved K-means are proposed to accelerate it and improve the quality of initialize cluster centers, but few researchers pay attention to the shortcoming of K-means in discovering arbitrary-shaped clusters. Using graph distance (GD) to measure the dissimilarity between objects is a good way to solve this problem, but computing the GD is time-consuming. Inspired by the idea that granular ball uses a ball to represent the local data, we select representatives from a local neighborhood, called natural density peaks (NDPs). On the basis of NDPs, we propose a novel K-means algorithm for identifying arbitrary-shaped clusters, called NDP-Kmeans. It defines neighbor-based distance between NDPs and takes advantage of the neighbor-based distance to compute the GD between NDPs. Afterward, an improved K-means with high-quality initial centers and GD is used to cluster NDPs. Finally, each remaining object is assigned according to its representative. The experimental results show that our algorithms can not only recognize spherical clusters but also manifold clusters. Therefore, NDP-Kmeans has more advantages in detecting arbitrary-shaped clusters than other excellent algorithms.
More Related Videos
 12:27
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
 05:12
ExCYT: A Graphical User Interface for Streamlining Analysis of High-Dimensional Cytometry Data
Published on: January 16, 2019
Related Concept Videos
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 00:56
Density
 01:24
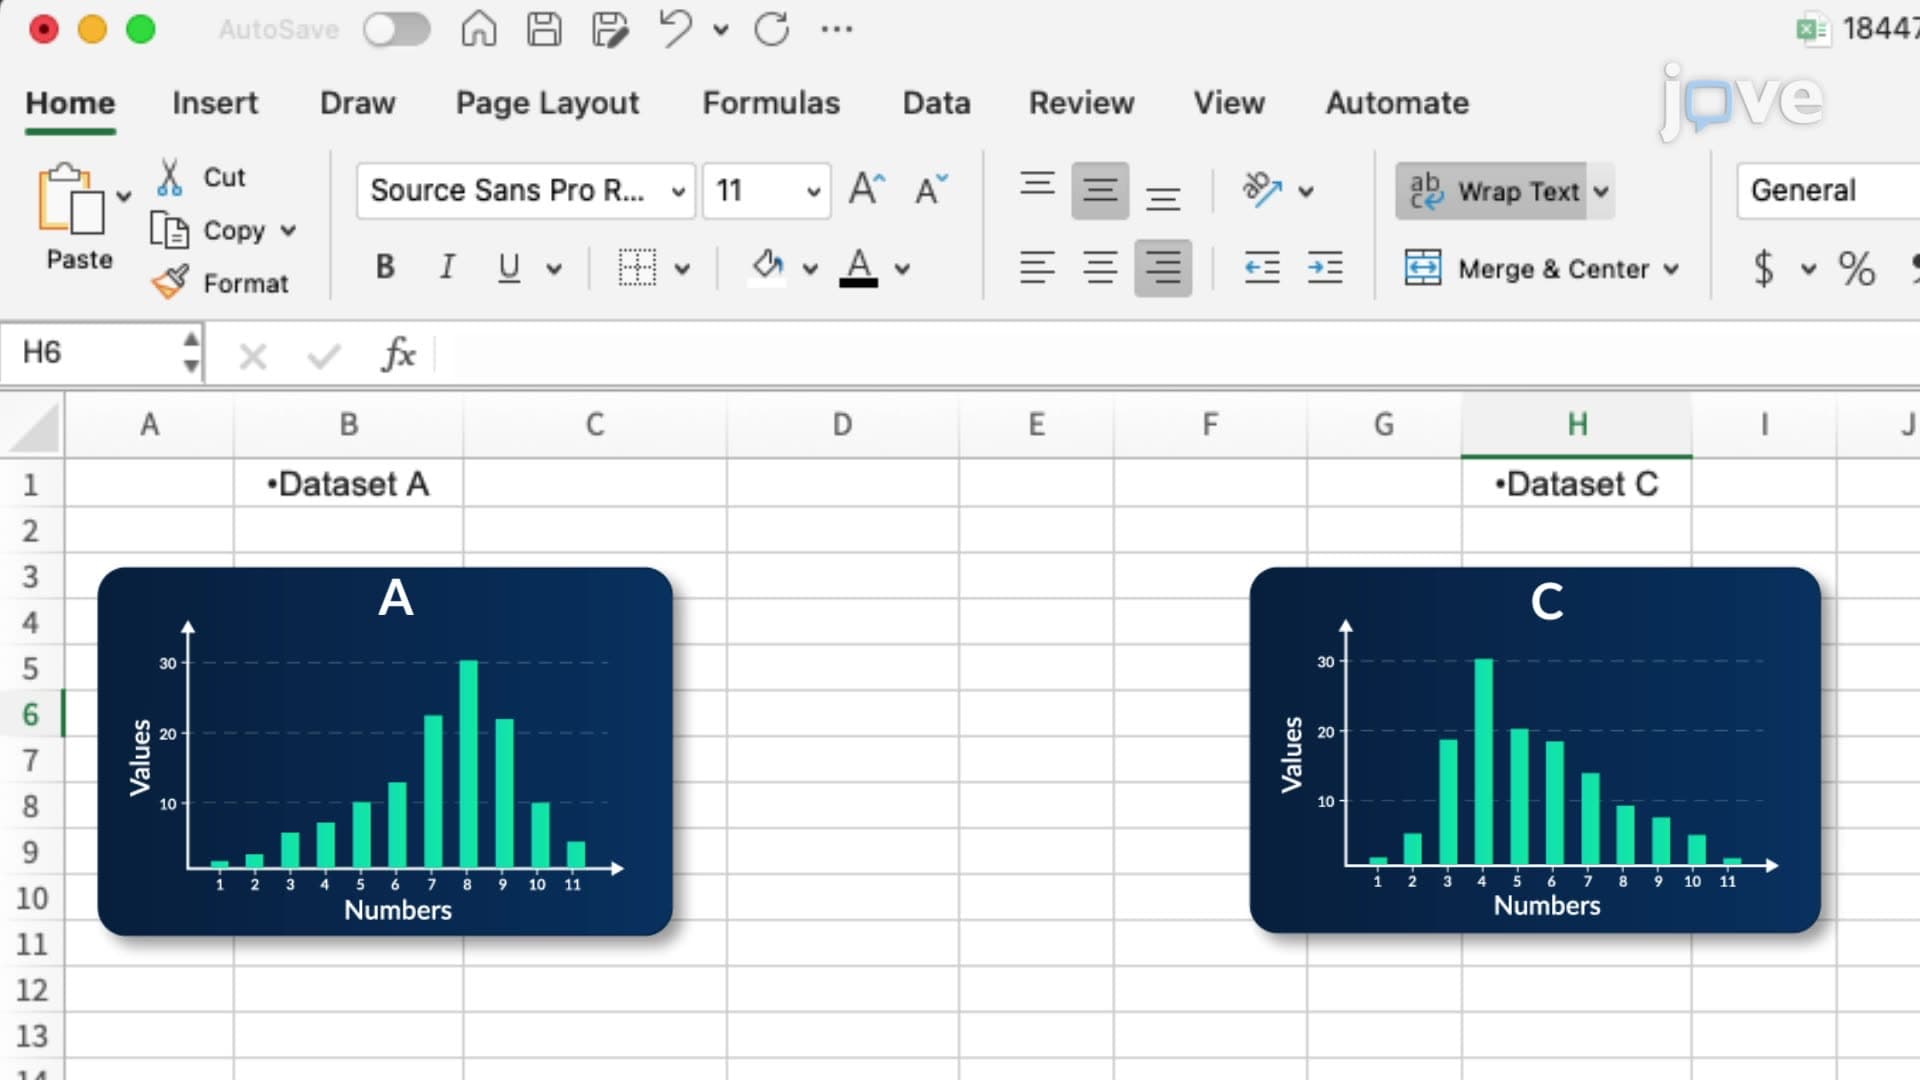
Microsoft Excel: Finding Central Tendency, Skew, and Kurtosis
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
 01:03
Centroid of a Body: Problem Solving
The x-coordinates and y-coordinates of each element's...
 01:20
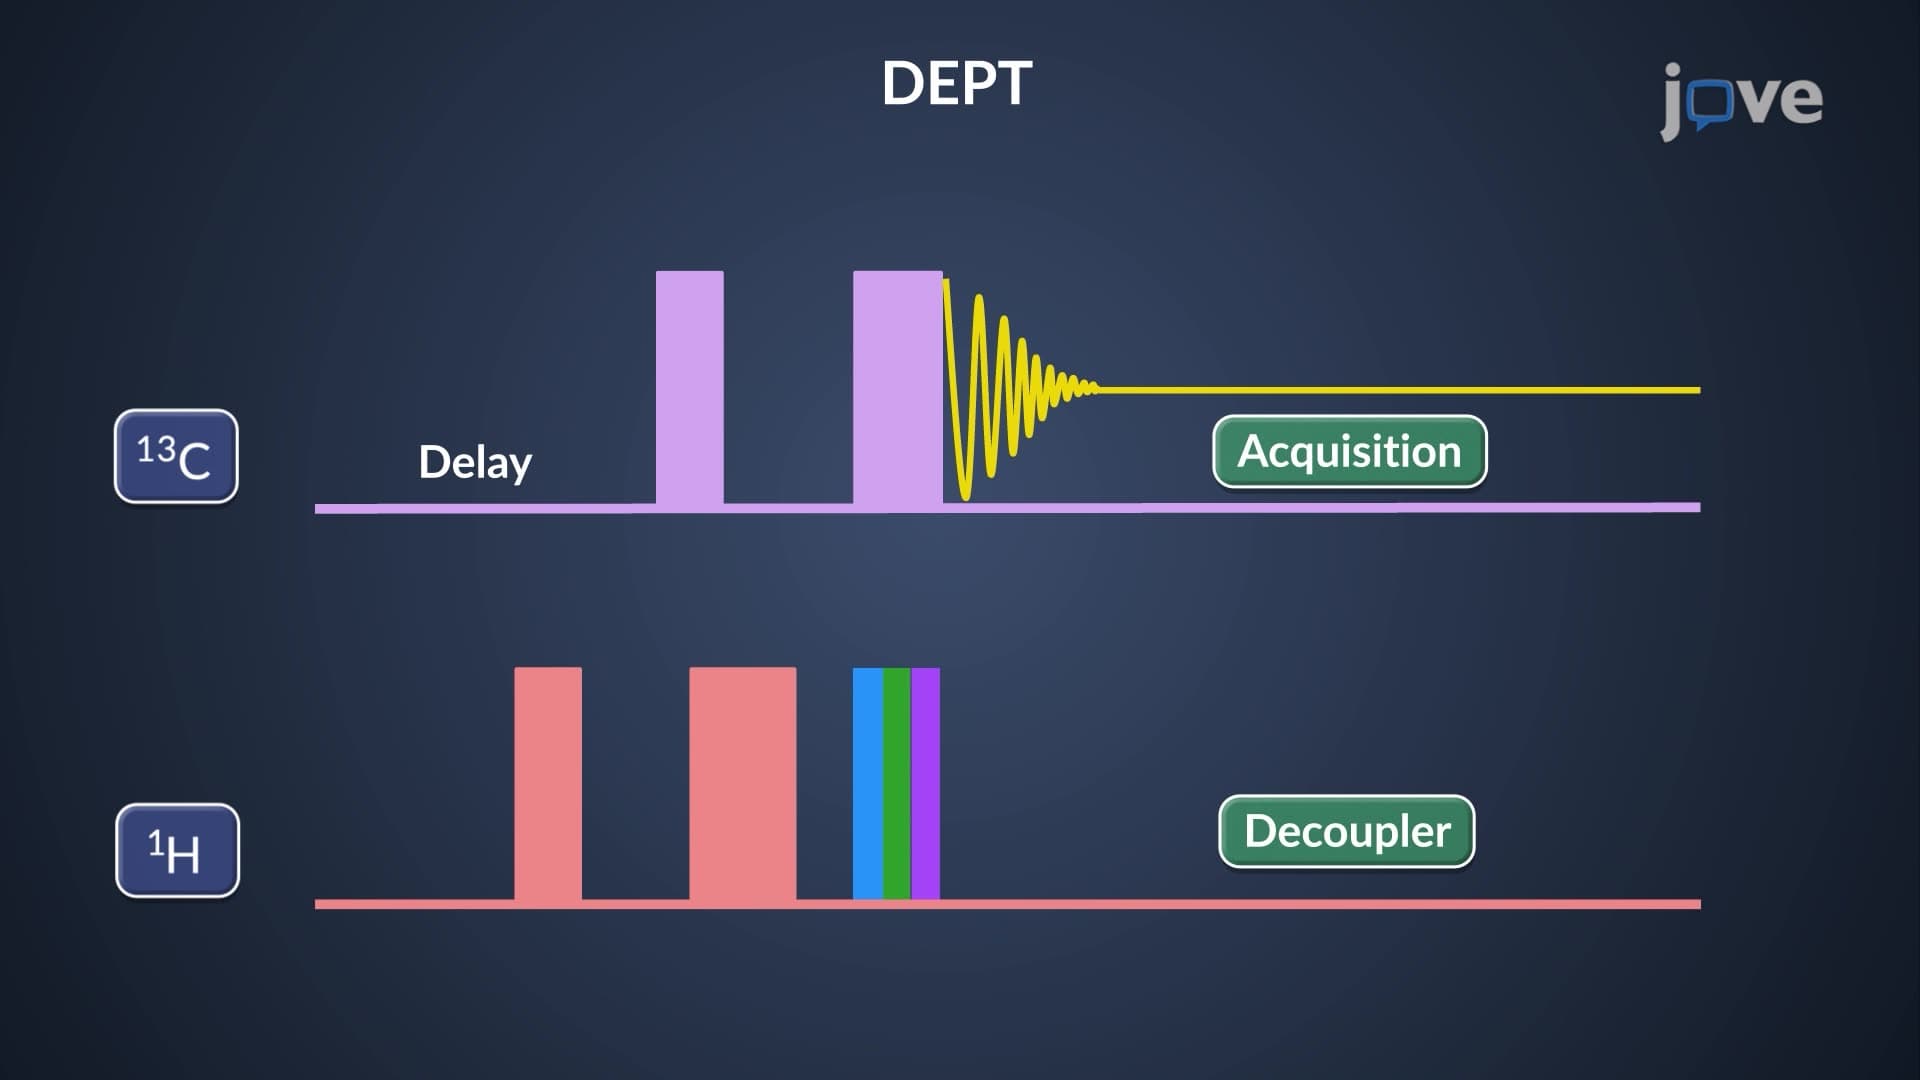
¹³C NMR: Distortionless Enhancement by Polarization Transfer (DEPT)
 01:08
Outliers and Influential Points