Related Experiment Video
Updated: Aug 3, 2025
Swin-PSAxialNet: An Efficient Multi-Organ Segmentation Technique
Published on: July 5, 2024
Dynamic Spatial Sparsification for Efficient Vision Transformers and Convolutional Neural Networks

Abstract:
In this paper, we present a new approach for model acceleration by exploiting spatial sparsity in visual data. We observe that the final prediction in vision Transformers is only based on a subset of the most informative regions, which is sufficient for accurate image recognition. Based on this observation, we propose a dynamic token sparsification framework to prune redundant tokens progressively and dynamically based on the input to accelerate vision Transformers. Specifically, we devise a lightweight prediction module to estimate the importance of each token given the current features. The module is added to different layers to prune redundant tokens hierarchically. While the framework is inspired by our observation of the sparse attention in vision Transformers, we find that the idea of adaptive and asymmetric computation can be a general solution for accelerating various architectures. We extend our method to hierarchical models including CNNs and hierarchical vision Transformers as well as more complex dense prediction tasks. To handle structured feature maps, we formulate a generic dynamic spatial sparsification framework with progressive sparsification and asymmetric computation for different spatial locations. By applying lightweight fast paths to less informative features and expressive slow paths to important locations, we can maintain the complete structure of feature maps while significantly reducing the overall computations. Extensive experiments on diverse modern architectures and different visual tasks demonstrate the effectiveness of our proposed framework. By hierarchically pruning 66% of the input tokens, our method greatly reduces 31% ∼ 35% FLOPs and improves the throughput by over 40% while the drop of accuracy is within 0.5% for various vision Transformers. By introducing asymmetric computation, a similar acceleration can be achieved on modern CNNs and Swin Transformers. Moreover, our method achieves promising results on more complex tasks including semantic segmentation and object detection. Our results clearly demonstrate that dynamic spatial sparsification offers a new and more effective dimension for model acceleration. Code is available at https://github.com/raoyongming/DynamicViT.

Related Concept Videos
 01:15
Depth Perception and Spatial Vision
 01:17
Convolution Properties II
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...
 01:24
Convolution: Math, Graphics, and Discrete Signals
To simplify the convolution integral, it is assumed that both the input signal and impulse response are zero for negative time values. The graphical convolution process...
 01:20
Convolution Properties I
The commutative property reveals that the input and the impulse response of an LTI (Linear Time-Invariant) system can be interchanged without affecting the output:
 01:20
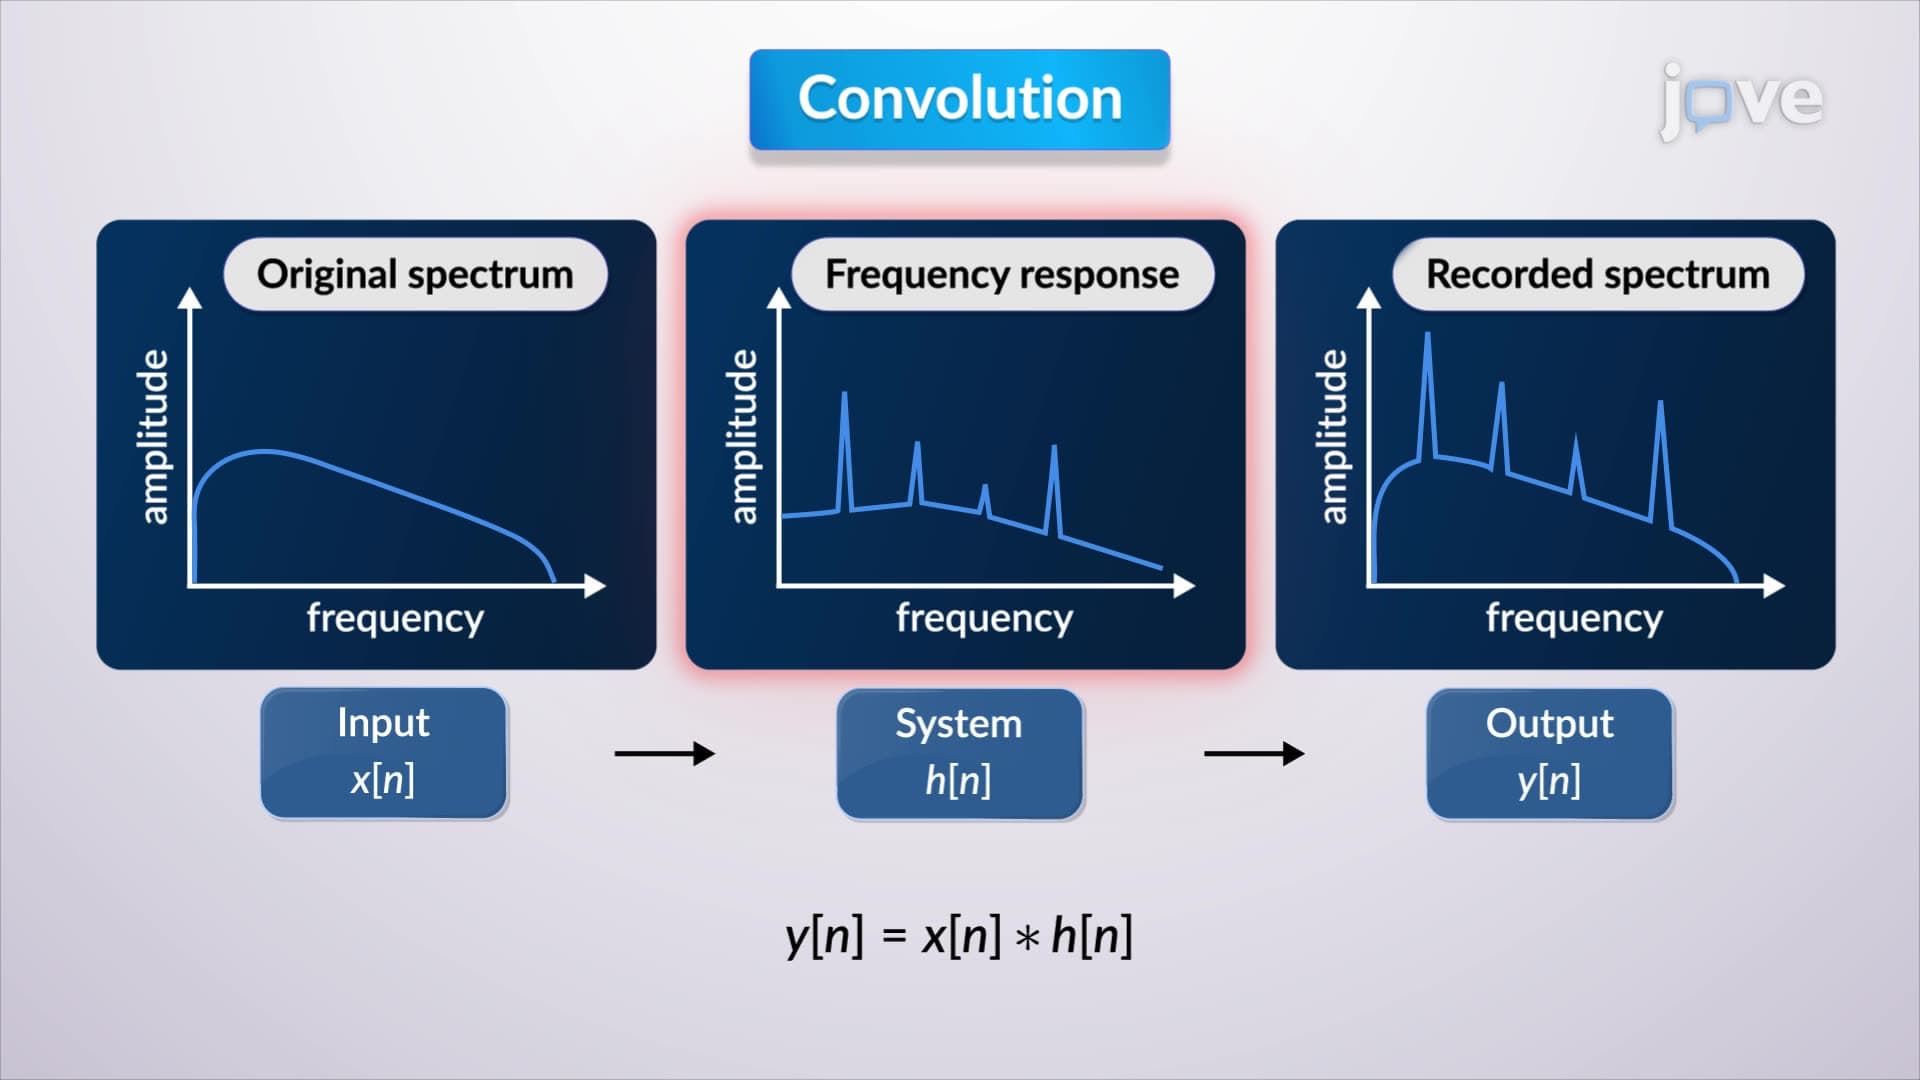
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:26
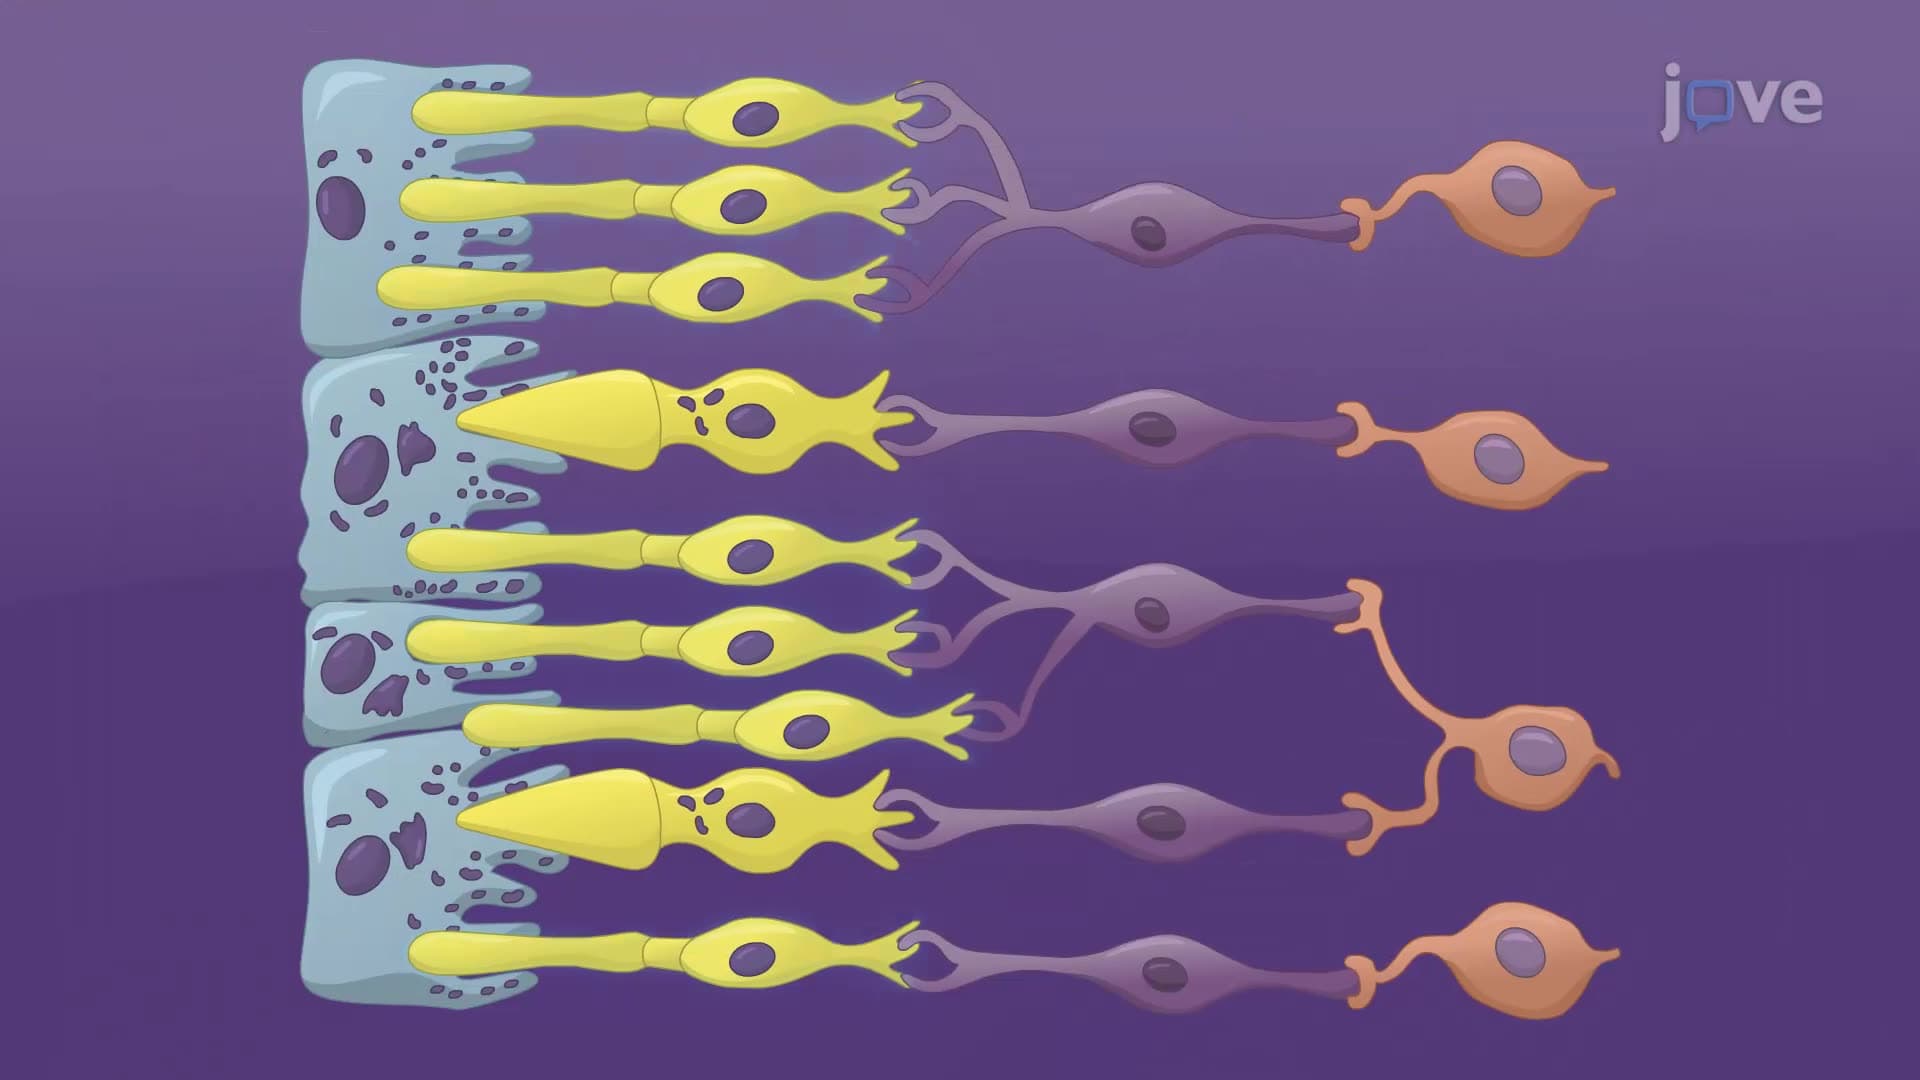
Visual System
Once through the pupil, the light passes through the lens, a...