Related Experiment Video
Updated: Aug 2, 2025

Author Spotlight: Cost-Effective Transcriptomic Drug Screening - Unlocking New Targets
Published on: February 23, 2024
MF-PCBA: Multifidelity High-Throughput Screening Benchmarks for Drug Discovery and Machine Learning
David Buterez1, Jon Paul Janet2, Steven J Kiddle3
1Department of Computer Science and Technology, University of Cambridge, Cambridge CB3 0FD, U.K.

Abstract:
High-throughput screening (HTS), as one of the key techniques in drug discovery, is frequently used to identify promising drug candidates in a largely automated and cost-effective way. One of the necessary conditions for successful HTS campaigns is a large and diverse compound library, enabling hundreds of thousands of activity measurements per project. Such collections of data hold great promise for computational and experimental drug discovery efforts, especially when leveraged in combination with modern deep learning techniques, and can potentially lead to improved drug activity predictions and cheaper and more effective experimental design. However, existing collections of machine-learning-ready public datasets do not exploit the multiple data modalities present in real-world HTS projects. Thus, the largest fraction of experimental measurements, corresponding to hundreds of thousands of "noisy" activity values from primary screening, are effectively ignored in the majority of machine learning models of HTS data. To address these limitations, we introduce Multifidelity PubChem BioAssay (MF-PCBA), a curated collection of 60 datasets that includes two data modalities for each dataset, corresponding to primary and confirmatory screening, an aspect that we call multifidelity. Multifidelity data accurately reflect real-world HTS conventions and present a new, challenging task for machine learning: the integration of low- and high-fidelity measurements through molecular representation learning, taking into account the orders-of-magnitude difference in size between the primary and confirmatory screens. Here we detail the steps taken to assemble MF-PCBA in terms of data acquisition from PubChem and the filtering steps required to curate the raw data. We also provide an evaluation of a recent deep-learning-based method for multifidelity integration across the introduced datasets, demonstrating the benefit of leveraging all HTS modalities, and a discussion in terms of the roughness of the molecular activity landscape. In total, MF-PCBA contains over 16.6 million unique molecule-protein interactions. The datasets can be easily assembled by using the source code available at https://github.com/davidbuterez/mf-pcba.
More Related Videos
 08:43
A Fluorescence-based Lymphocyte Assay Suitable for High-throughput Screening of Small Molecules
Published on: March 10, 2017
 08:31
Biosensor-based High Throughput Biopanning and Bioinformatics Analysis Strategy for the Global Validation of Drug-protein Interactions
Published on: December 1, 2020
Related Concept Videos
 01:26
Drug Discovery: Overview
 01:18
Patch Clamp
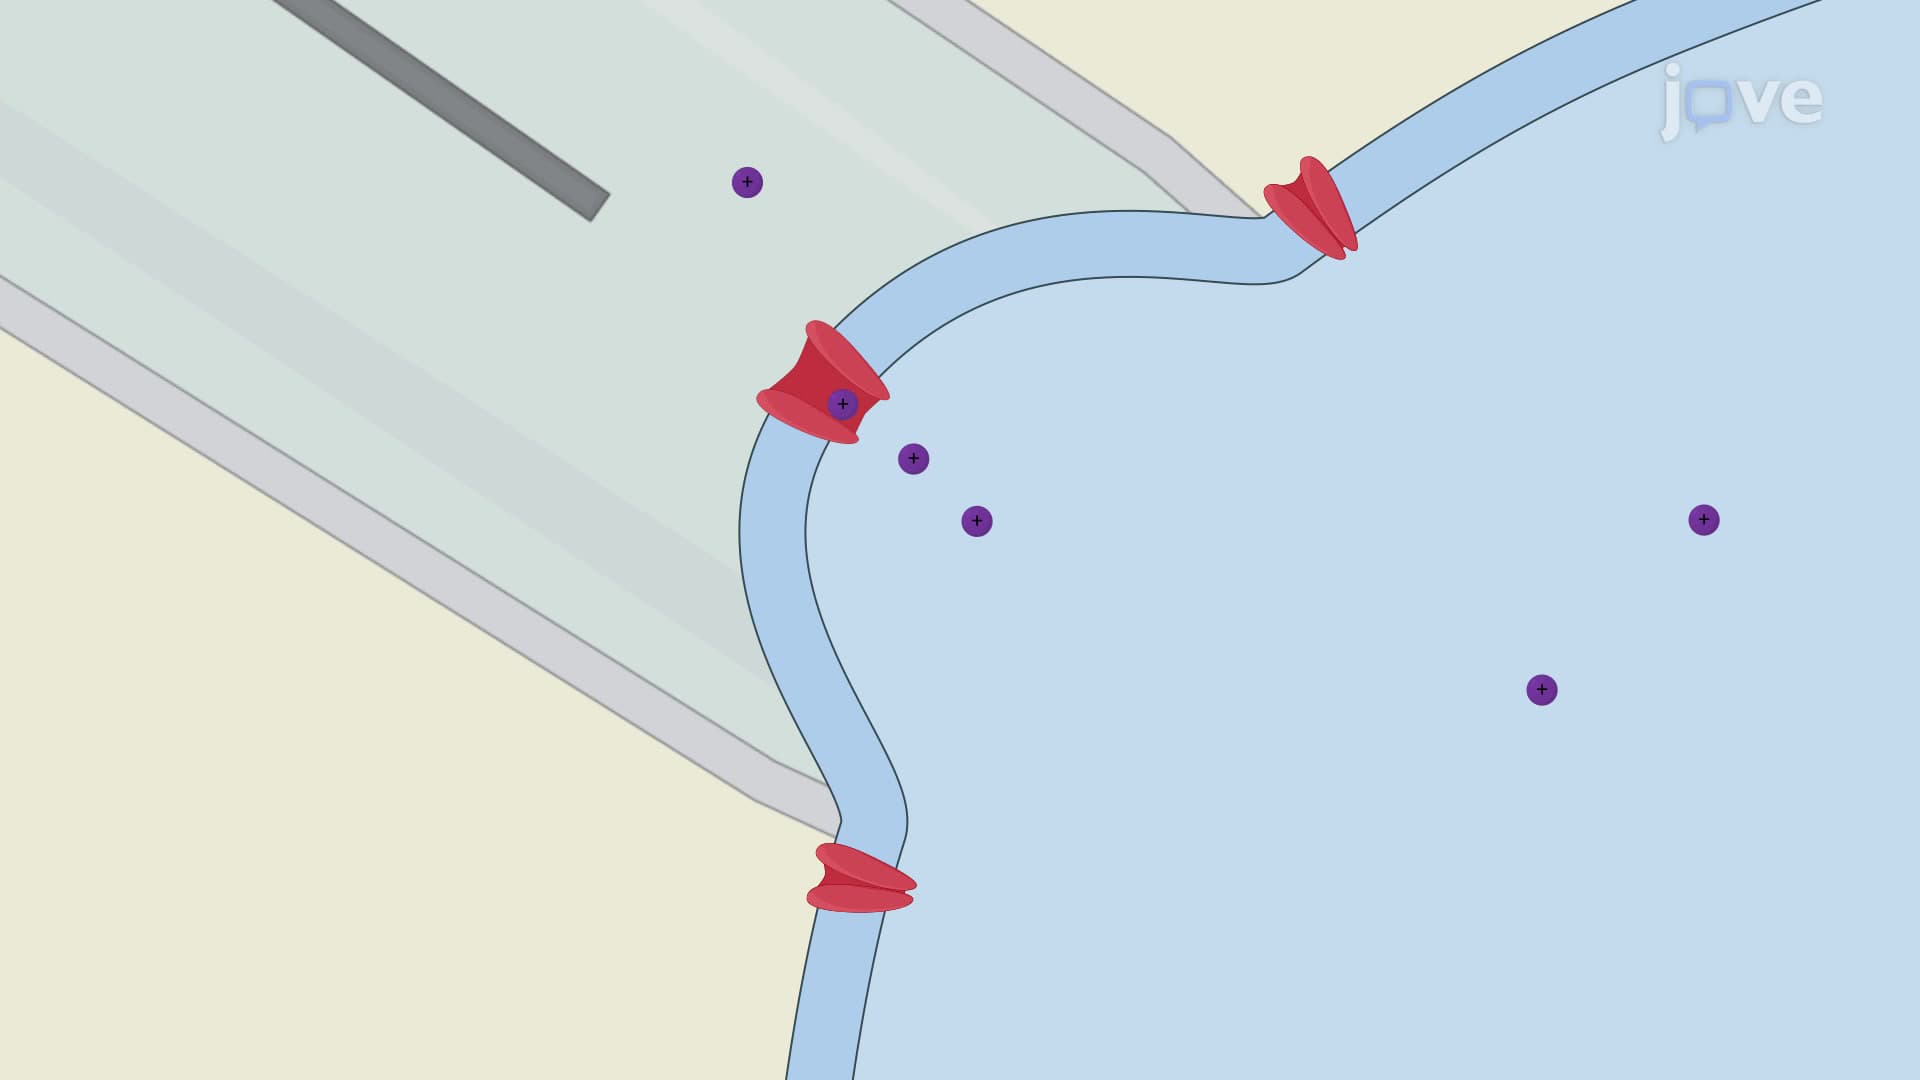
In this method, a glass micropipette containing electrolyte solution is tightly sealed against a small portion of the cell membrane. As a result, a patch of the cell...