Related Experiment Video
Updated: Aug 2, 2025
Determination of Aggregate Surface Morphology at the Interfacial Transition Zone ITZ
Published on: December 16, 2019
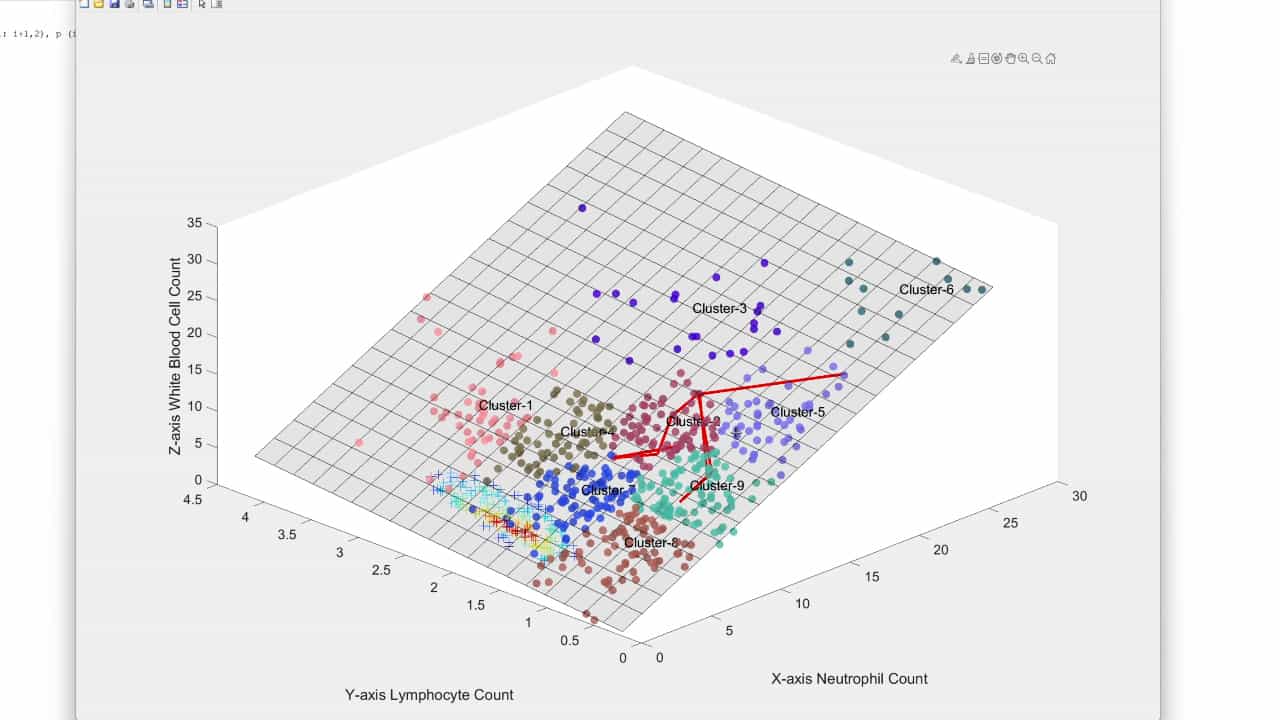
An investigation into epidemiological situations of COVID-19 with fuzzy K-means and K-prototype clustering methods
1Biostatistics Department, Faculty of Medicine, Bezmialem University, Fatih, Istanbul, Turkey. opasin@bezmialem.edu.tr.

Abstract:
The ten countries with the highest population during the pandemic were analyzed for clustering based on the quantitative numbers of COVID-19 and policy plans. The Fuzzy K-Means (FKM) and K-prototype algorithms were used for clustering, and various performance indices such as Partition Coefficient (PC), Partition Entropy (PE), Xie-Beni (XB), and Silhouette Fuzzy (SIL.F) were used for evaluating the clusters. The analysis included variables such as confirmed cases, tests, vaccines, school and workplace closures, event cancellations, gathering restrictions, transport closures, stay-at-home restrictions, international movement restrictions, testing policies, facial coverings, and vaccination policy statuses. PC, PE, XB, and SIL.F indices were used to analyze the performance indices of the clusters. The Elbow method was used to analyze the performance evaluations for the K-prototype. The K-prototype algorithm's performance evaluations were analyzed using the Elbow method, and the optimum number of clusters for both methods was found to be two. The first cluster included Brazil, Mexico, Nigeria, Bangladesh, US, Indonesia, Russia, and Pakistan, while the second cluster comprised India and China. The analysis also examined the relationship between population and confirmed tests and vaccines, and standardization was made for the country with the largest population for significant correlations. The results showed that the FKM method was superior to the K-prototype method in terms of clustering. In conclusion, it is crucial to accurately evaluate COVID-19 data for countries and develop appropriate policies. The clustering analysis using the FKM and K-prototype algorithms provides valuable insights into identifying groups of countries with similar COVID-19 data and policy plans.
Related Concept Videos
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 00:52
Pareto Chart
The Pareto chart is named after the Italian economist Vilfredo Pareto, who described the Pareto...
 01:18
Steps in Outbreak Investigation
 01:26
Introduction to Epidemiology
 01:21
Causality in Epidemiology