Related Experiment Video
Updated: Jul 28, 2025
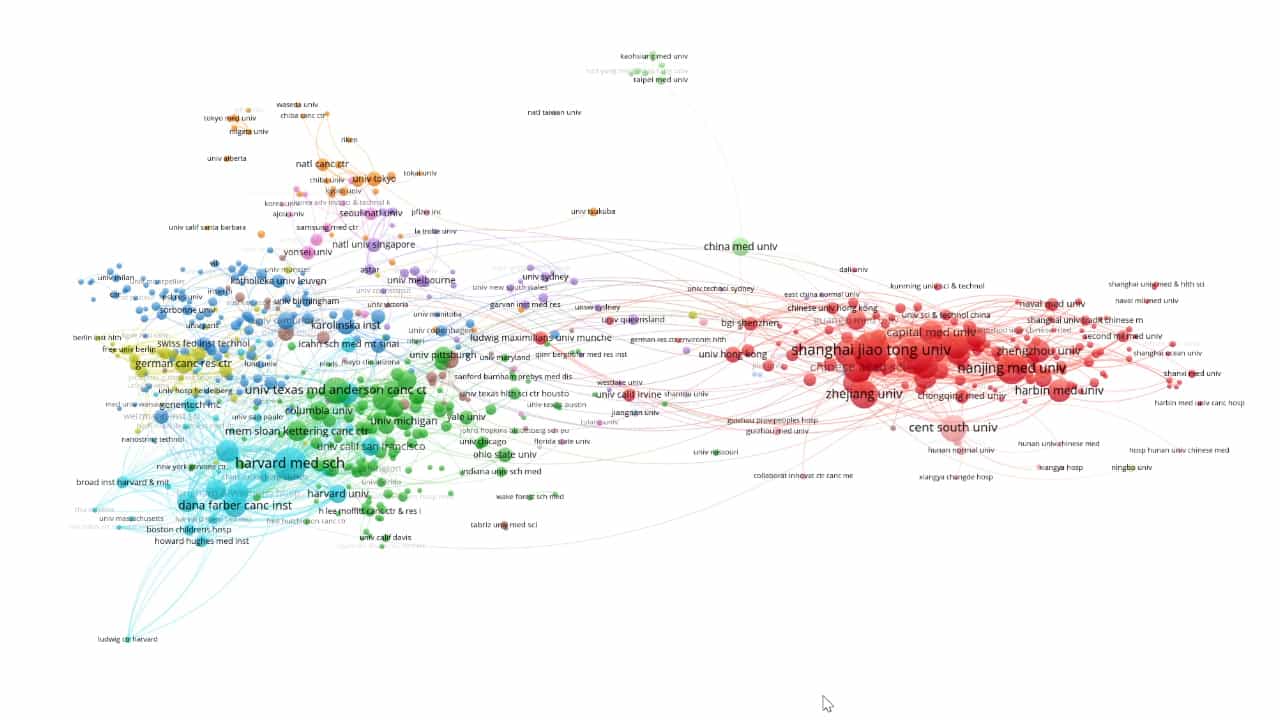

Global and Current Research Trends of Single-Cell Sequencing in Cancer: A Bibliometric and Visualization Study
Published on: April 18, 2025
gosset: An R package for analysis and synthesis of ranking data in agricultural experimentation
Kauê de Sousa1,2, David Brown3,4,5, Jonathan Steinke2,6
1Department of Agricultural Sciences, Inland Norway University of Applied Sciences, 2318 Hamar, Norway.

Abstract:
To derive insights from data, researchers working on agricultural experiments need appropriate data management and analysis tools. To ensure that workflows are reproducible and can be applied on a routine basis, programmatic tools are needed. Such tools are increasingly necessary for rank-based data, a type of data that is generated in on-farm experimentation and data synthesis exercises, among others. To address this need, we developed the R package gosset, which provides functionality for rank-based data and models. The gosset package facilitates data preparation, modeling and results presentation stages. It introduces novel functions not available in existing R packages for analyzing ranking data. This paper demonstrates the package functionality using the case study of a decentralized on-farm trial of common bean (Phaseolus vulgaris L.) varieties in Nicaragua.
More Related Videos
 06:46
Competing-Risk Nomogram for Predicting Cancer-Specific Survival in Multiple Primary Colorectal Cancer Patients after Surgery
Published on: September 27, 2024
 09:35
A Protocol for Using Gene Set Enrichment Analysis to Identify the Appropriate Animal Model for Translational Research
Published on: August 16, 2017
Related Concept Videos
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:02
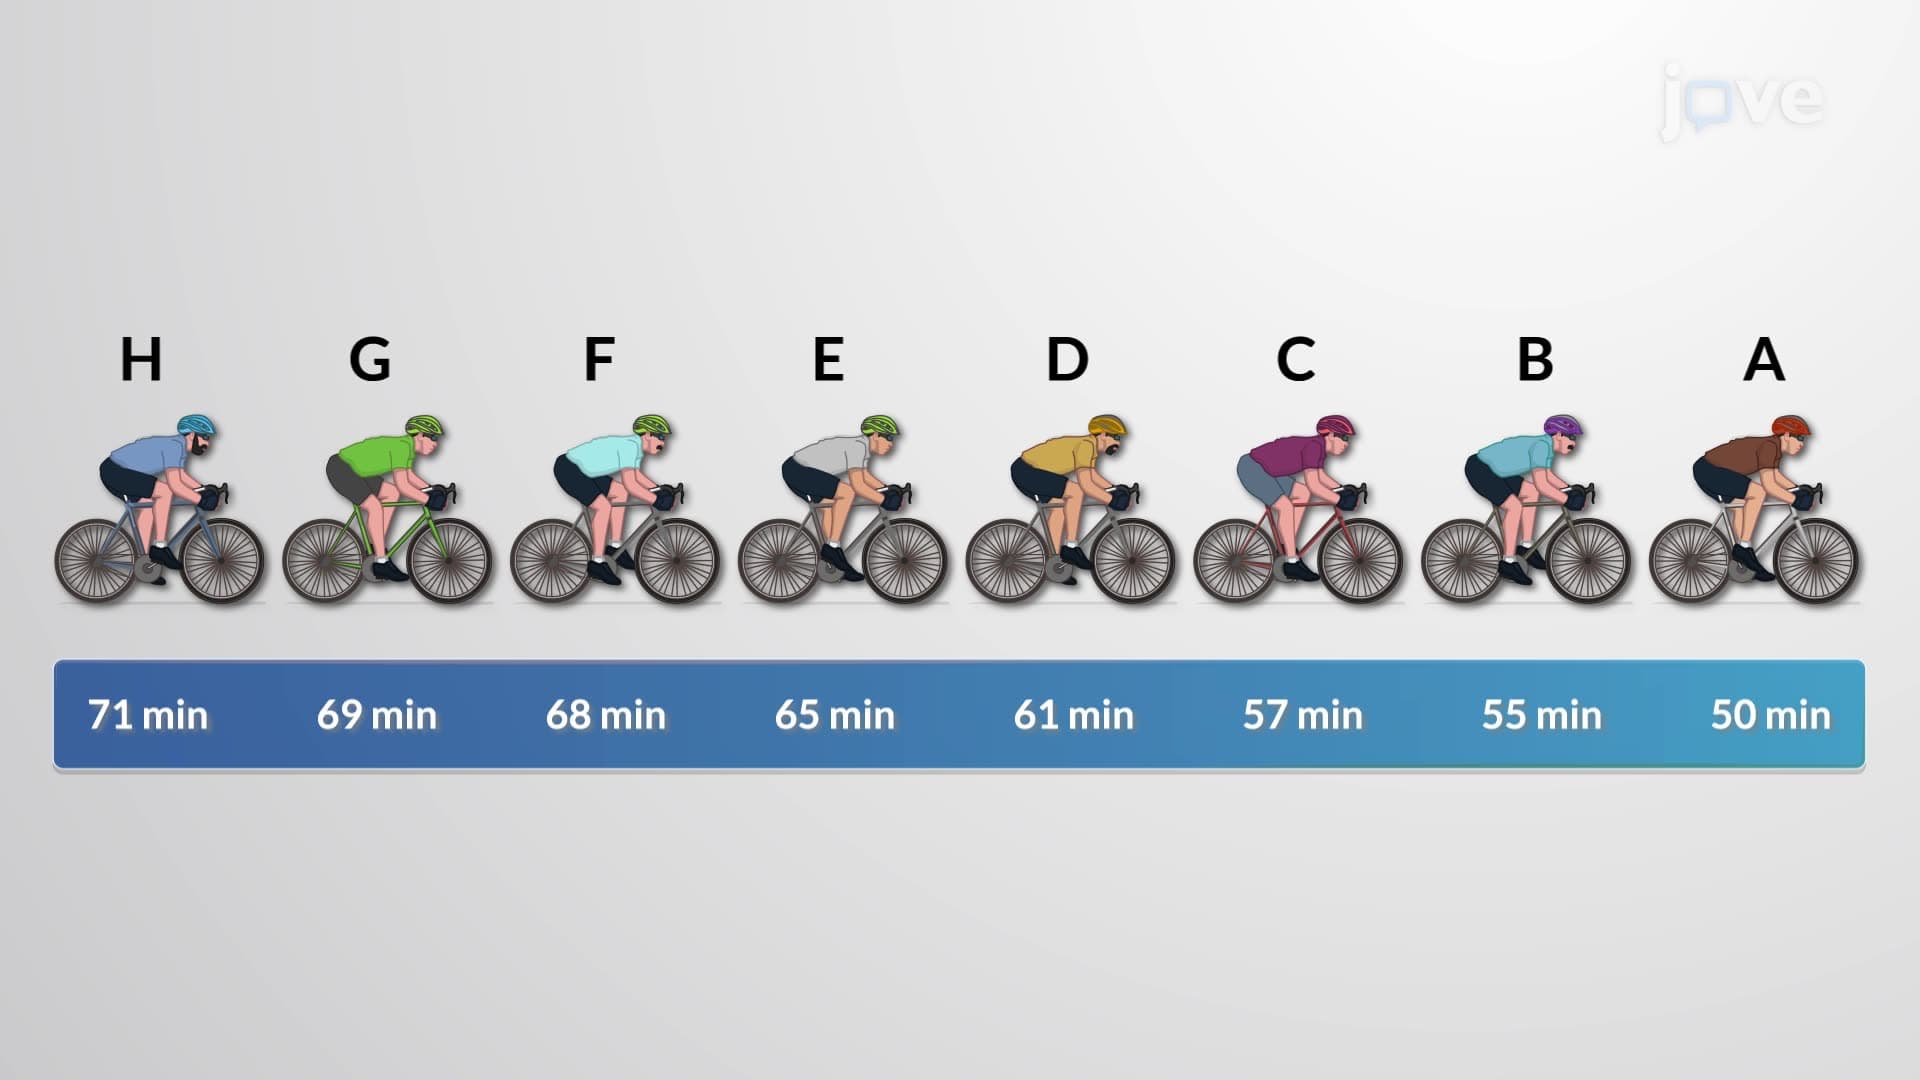
Ranks
 01:11
Introduction to R
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:14
Statistical Analysis System (SAS)
Applications: SAS finds applications in numerous fields, including healthcare for clinical trial analysis, finance for risk assessment, marketing for customer data analysis, and...