Related Experiment Video
Updated: Jul 27, 2025

Methods for Presenting Real-world Objects Under Controlled Laboratory Conditions
Published on: June 21, 2019
Do poverty and wealth look the same the world over? A comparative study of 12 cities from five high-income countries
Esra Suel1,2,3, Emily Muller2,3, James E Bennett2,3
1London, UK Centre for Advanced Spatial Analysis (CASA), University College London.

Abstract:
Urbanization and inequalities are two of the major policy themes of our time, intersecting in large cities where social and economic inequalities are particularly pronounced. Large scale street-level images are a source of city-wide visual information and allow for comparative analyses of multiple cities. Computer vision methods based on deep learning applied to street images have been shown to successfully measure inequalities in socioeconomic and environmental features, yet existing work has been within specific geographies and have not looked at how visual environments compare across different cities and countries. In this study, we aim to apply existing methods to understand whether, and to what extent, poor and wealthy groups live in visually similar neighborhoods across cities and countries. We present novel insights on similarity of neighborhoods using street-level images and deep learning methods. We analyzed 7.2 million images from 12 cities in five high-income countries, home to more than 85 million people: Auckland (New Zealand), Sydney (Australia), Toronto and Vancouver (Canada), Atlanta, Boston, Chicago, Los Angeles, New York, San Francisco, and Washington D.C. (United States of America), and London (United Kingdom). Visual features associated with neighborhood disadvantage are more distinct and unique to each city than those associated with affluence. For example, from what is visible from street images, high density poor neighborhoods located near the city center (e.g., in London) are visually distinct from poor suburban neighborhoods characterized by lower density and lower accessibility (e.g., in Atlanta). This suggests that differences between two cities is also driven by historical factors, policies, and local geography. Our results also have implications for image-based measures of inequality in cities especially when trained on data from cities that are visually distinct from target cities. We showed that these are more prone to errors for disadvantaged areas especially when transferring across cities, suggesting more attention needs to be paid to improving methods for capturing heterogeneity in poor environment across cities around the world.
Supplementary Information:
The online version contains supplementary material available at 10.1140/epjds/s13688-023-00394-6.
More Related Videos
Related Concept Videos
 01:25
Selected Data About Geographic Locations
 01:50
Cross-Sectional Research
 01:11
Observational Studies
There are three types of observational studies – Prospective, retrospective, and cross-sectional.
Prospective Study
Prospective studies, also known as longitudinal or cohort studies, are carried out by collecting future data from groups sharing similar characteristics. One...
 01:06
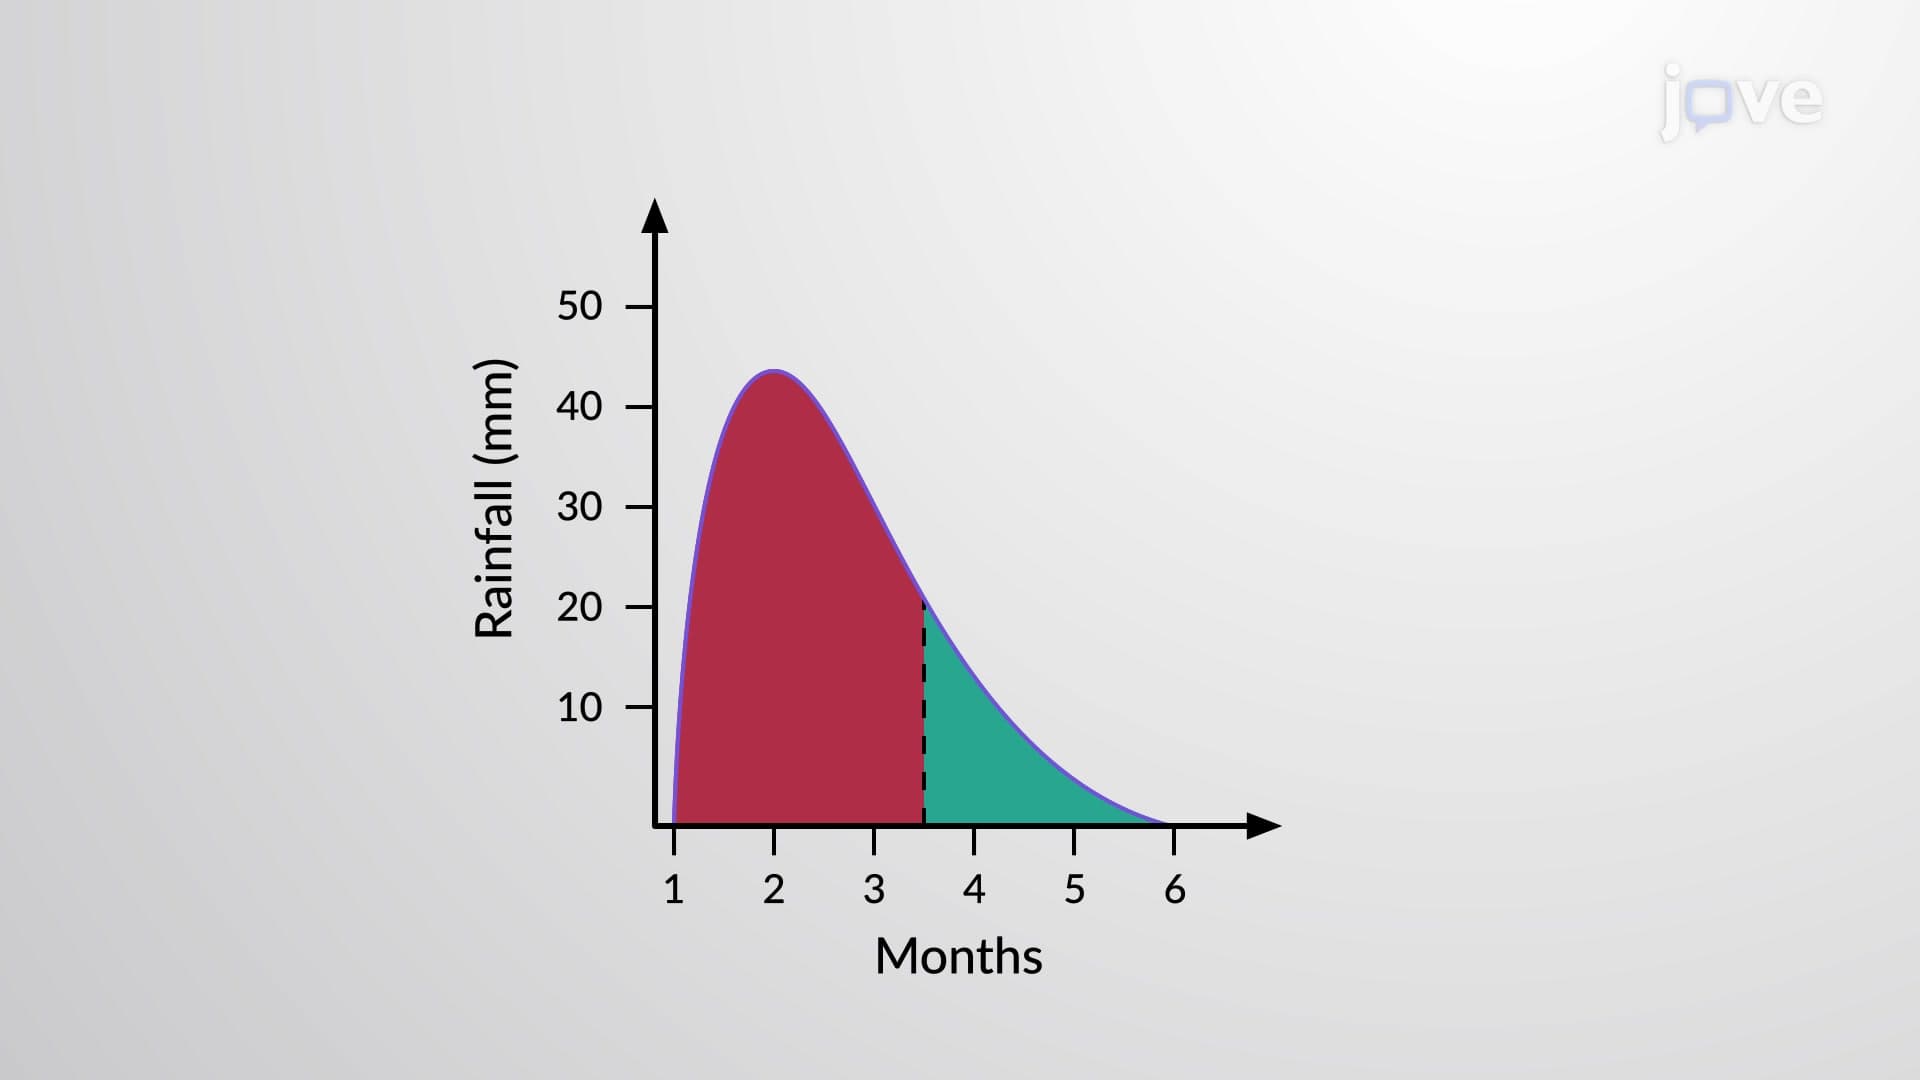
Skewness
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
 01:08
Outliers and Influential Points
 01:14
Wilcoxon Signed-Ranks Test for Median of Single Population