Related Experiment Video
Updated: Jul 26, 2025

Semiconductor Sequencing for Preimplantation Genetic Testing for Aneuploidy
Published on: August 25, 2019
Learned pseudo-random number generator: WGAN-GP for generating statistically robust random numbers
Kiyoshiro Okada1,2, Katsuhiro Endo1, Kenji Yasuoka1
1Department of Mechanical Engineering, Keio University, Yokohama, Japan.

Abstract:
Pseudo-random number generators (PRNGs) are software algorithms generating a sequence of numbers approximating the properties of random numbers. They are critical components in many information systems that require unpredictable and nonarbitrary behaviors, such as parameter configuration in machine learning, gaming, cryptography, and simulation. A PRNG is commonly validated through a statistical test suite, such as NIST SP 800-22rev1a (NIST test suite), to evaluate its robustness and the randomness of the numbers. In this paper, we propose a Wasserstein distance-based generative adversarial network (WGAN) approach to generating PRNGs that fully satisfy the NIST test suite. In this approach, the existing Mersenne Twister (MT) PRNG is learned without implementing any mathematical programming code. We remove the dropout layers from the conventional WGAN network to learn random numbers distributed in the entire feature space because the nearly infinite amount of data can suppress the overfitting problems that occur without dropout layers. We conduct experimental studies to evaluate our learned pseudo-random number generator (LPRNG) by adopting cosine-function-based numbers with poor random number properties according to the NIST test suite as seed numbers. The experimental results show that our LPRNG successfully converted the sequence of seed numbers to random numbers that fully satisfy the NIST test suite. This study opens the way for the "democratization" of PRNGs through the end-to-end learning of conventional PRNGs, which means that PRNGs can be generated without deep mathematical know-how. Such tailor-made PRNGs will effectively enhance the unpredictability and nonarbitrariness of a wide range of information systems, even if the seed numbers can be revealed by reverse engineering. The experimental results also show that overfitting was observed after about 450,000 trials of learning, suggesting that there is an upper limit to the number of learning counts for a fixed-size neural network, even when learning with unlimited data.
Related Concept Videos
 01:17
Wald-Wolfowitz Runs Test II
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
 01:09
Random Sampling Method
 01:17
Wald-Wolfowitz Runs Test I
The test works...
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:09
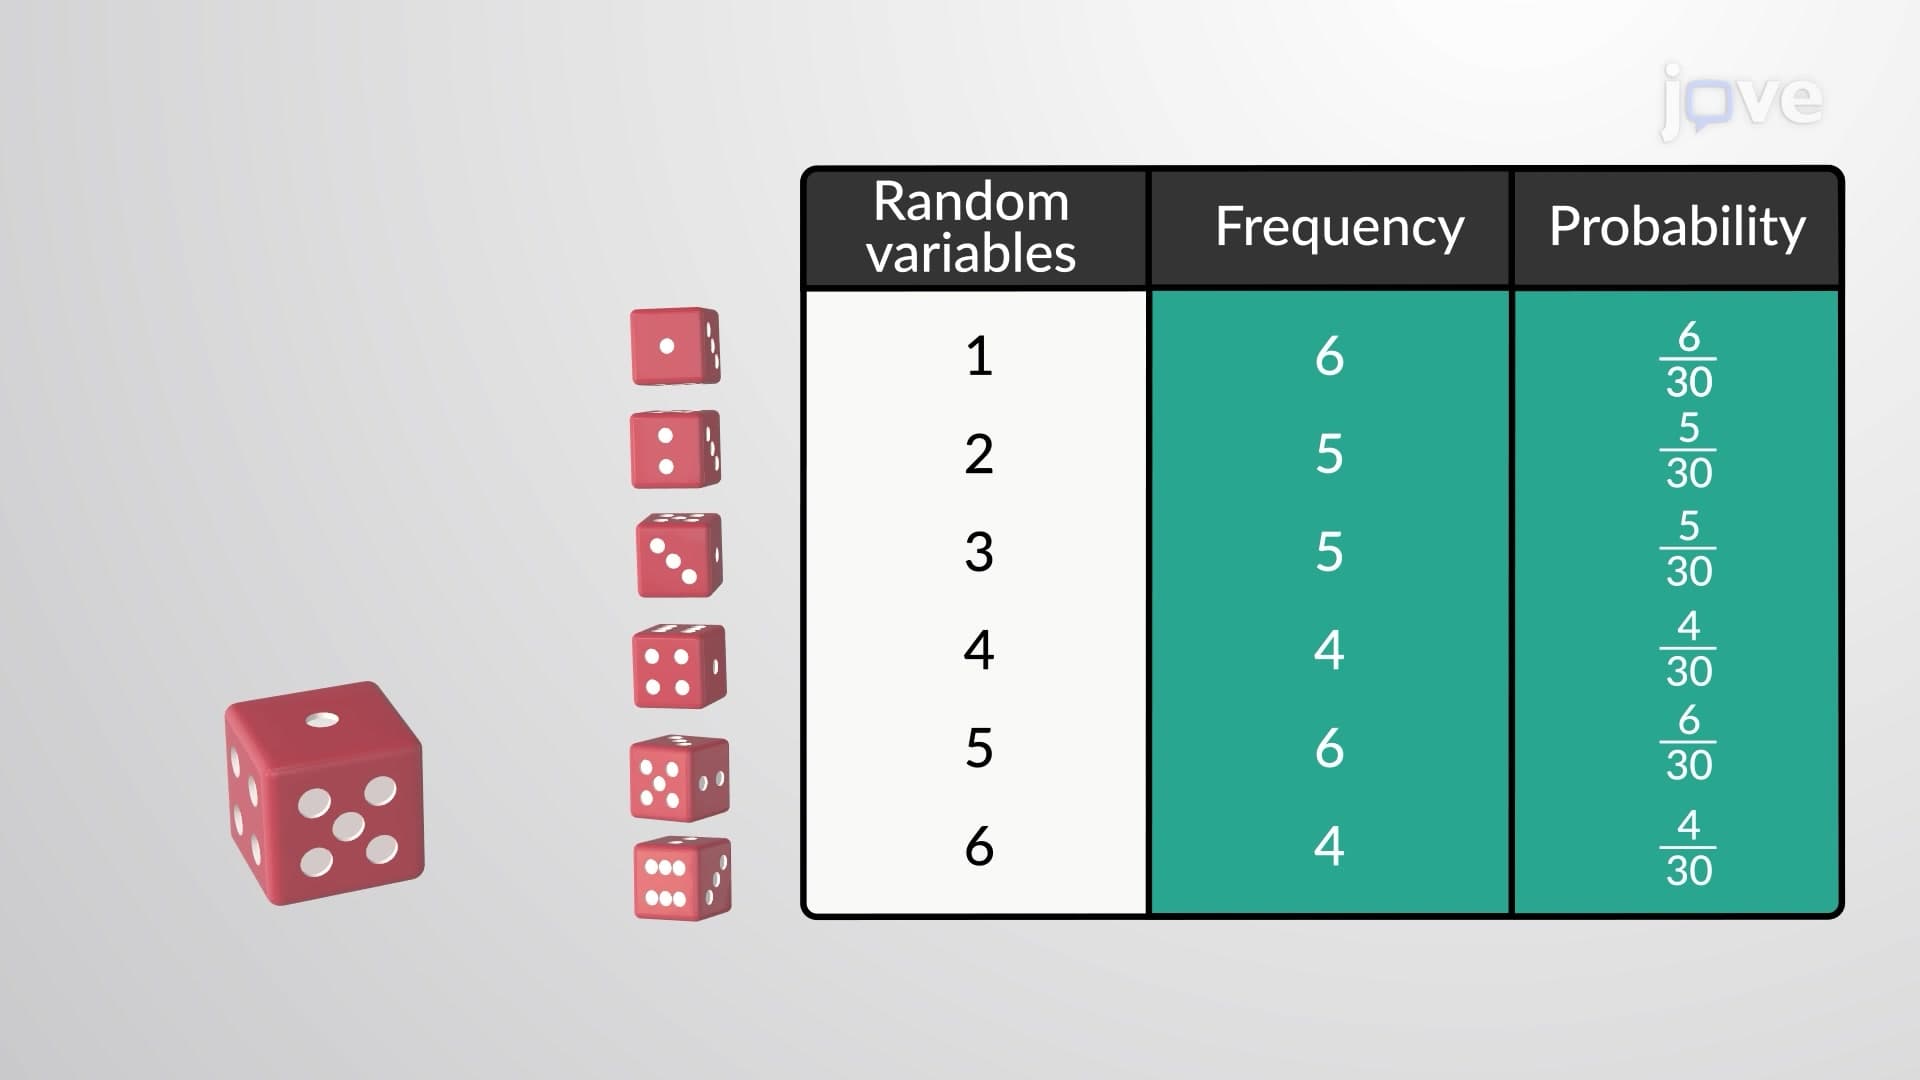
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:20
Random and Systematic Errors