Related Experiment Video
Updated: Jul 26, 2025


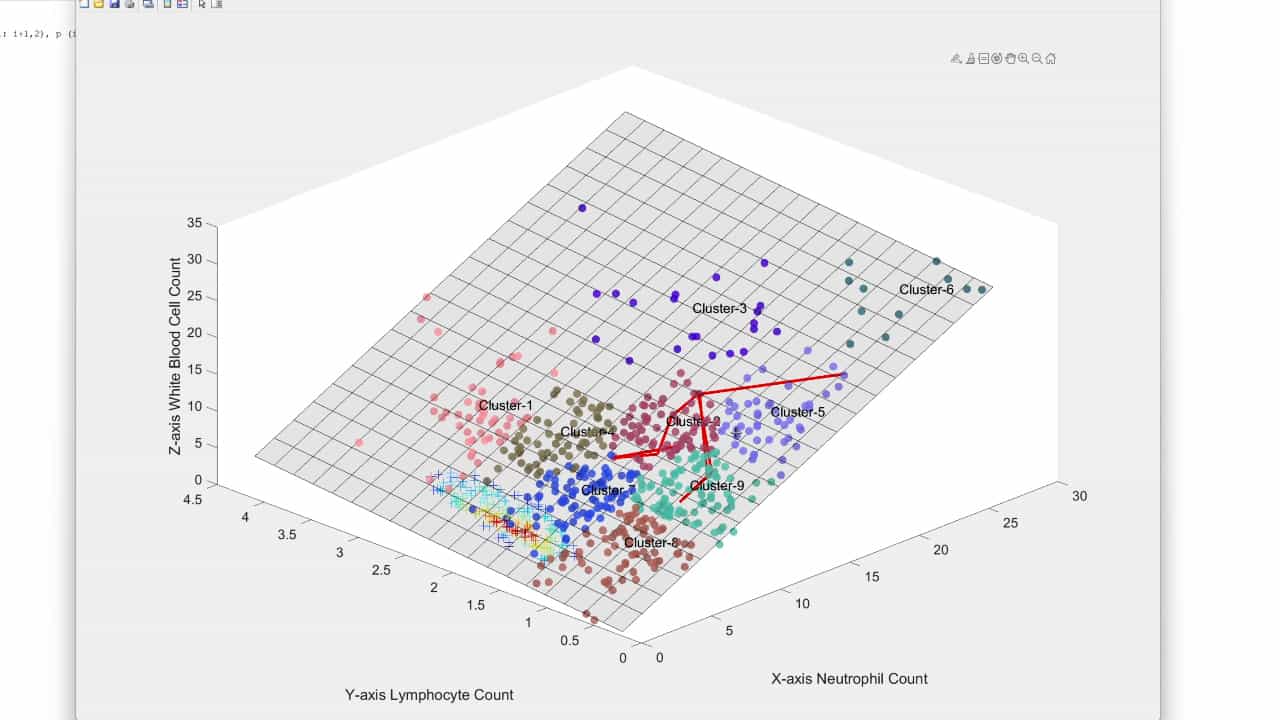
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
Pseudo-value regression of clustered multistate current status data with informative cluster sizes
Samuel Anyaso-Samuel1, Dipankar Bandyopadhyay2, Somnath Datta1
1Department of Biostatistics, University of Florida, Gainesville, FL, USA.

Abstract:
Multistate current status data presents a more severe form of censoring due to the single observation of study participants transitioning through a sequence of well-defined disease states at random inspection times. Moreover, these data may be clustered within specified groups, and informativeness of the cluster sizes may arise due to the existing latent relationship between the transition outcomes and the cluster sizes. Failure to adjust for this informativeness may lead to a biased inference. Motivated by a clinical study of periodontal disease, we propose an extension of the pseudo-value approach to estimate covariate effects on the state occupation probabilities for these clustered multistate current status data with informative cluster or intra-cluster group sizes. In our approach, the proposed pseudo-value technique initially computes marginal estimators of the state occupation probabilities utilizing nonparametric regression. Next, the estimating equations based on the corresponding pseudo-values are reweighted by functions of the cluster sizes to adjust for informativeness. We perform a variety of simulation studies to study the properties of our pseudo-value regression based on the nonparametric marginal estimators under different scenarios of informativeness. For illustration, the method is applied to the motivating periodontal disease dataset, which encapsulates the complex data-generation mechanism.
Related Concept Videos
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:52
Regression Toward the Mean
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:26
Estimating Population Standard Deviation
 01:22
Estimating Population Mean with Unknown Standard Deviation
William S. Gosset (1876–1937) of the...
 01:11
Testing a Claim about Mean: Known Population SD
Estimating a population mean requires the samples to be distributed normally. The data should be collected from the randomly selected samples having no sampling bias. The sample size needed to be higher than 30, and most importantly, the population standard deviation should be already known.
In most realistic situations, the population standard deviation is often unknown, but in rare circumstances, when it...