Related Experiment Video
Updated: Jul 24, 2025

Divergence of Root Microbiota in Different Habitats based on Weighted Correlation Networks
Published on: September 25, 2021
An Information-Theoretic Bound on p-Values for Detecting Communities Shared between Weighted Labeled Graphs
Predrag Obradovic1, Vladimir Kovačević1, Xiqi Li2
1School of Electrical Engineering, University of Belgrade, 11000 Belgrade, Serbia.

Abstract:
Extraction of subsets of highly connected nodes ("communities" or modules) is a standard step in the analysis of complex social and biological networks. We here consider the problem of finding a relatively small set of nodes in two labeled weighted graphs that is highly connected in both. While many scoring functions and algorithms tackle the problem, the typically high computational cost of permutation testing required to establish the p-value for the observed pattern presents a major practical obstacle. To address this problem, we here extend the recently proposed CTD ("Connect the Dots") approach to establish information-theoretic upper bounds on the p-values and lower bounds on the size and connectedness of communities that are detectable. This is an innovation on the applicability of CTD, broadening its use to pairs of graphs.
More Related Videos
 07:11
Author Spotlight: Emerging Technologies and Advanced Tools for Decoding Metabolomics Data Analysis
Published on: November 10, 2023
 09:38
Generalized Psychophysiological Interaction PPI Analysis of Memory Related Connectivity in Individuals at Genetic Risk for Alzheimer's Disease
Published on: November 14, 2017
Related Concept Videos
 01:09
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
 01:10
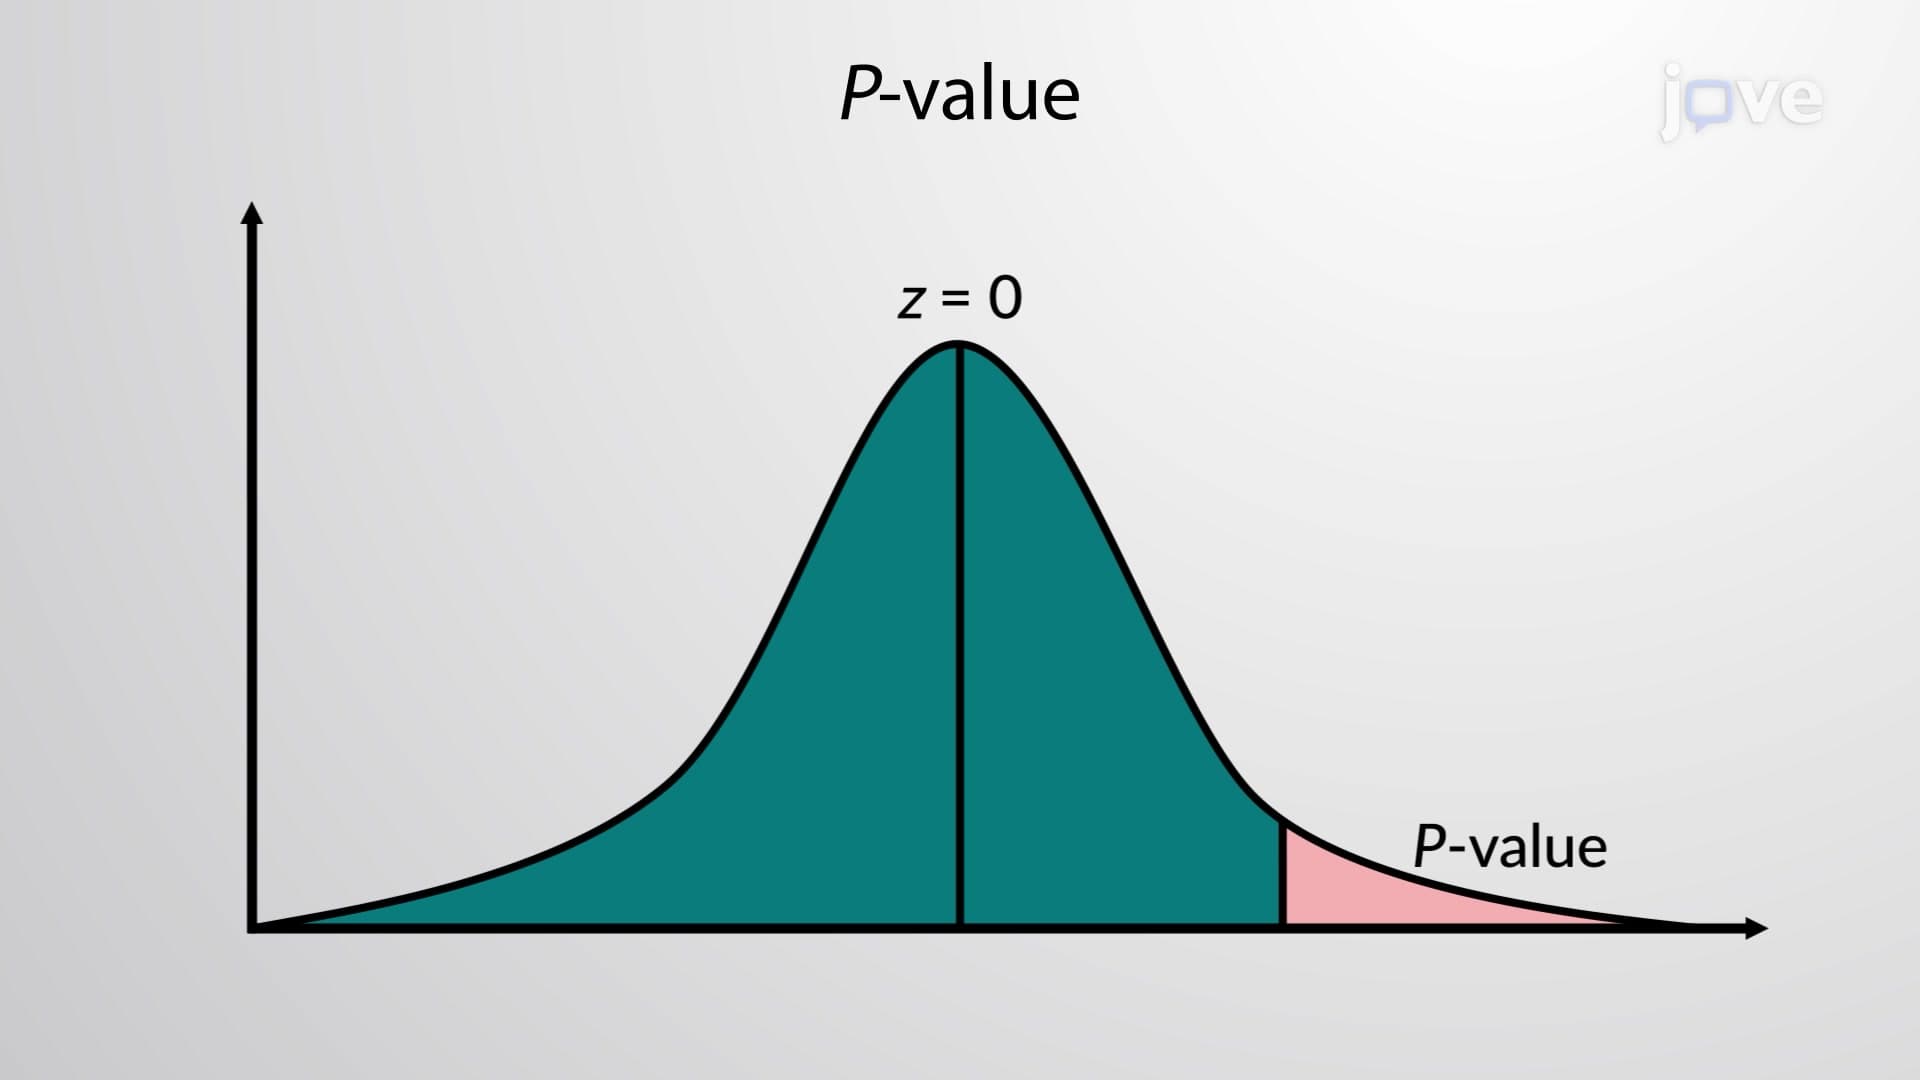
P-value
P-value stands for the probability value. P-value is the probability that, if the null hypothesis is true, the results from another randomly selected sample will be as extreme or more extreme as the results obtained from the given sample.
A large P-value calculated from the data indicates to not reject the null hypothesis. But a higher P-value does not mean that the null hypothesis is true. The smaller the P-value, the more...
 01:16
Critical Region, Critical Values and Significance Level
In hypothesis testing, a sample statistic is converted to a test statistic using z, t, or chi-square distribution. A critical region is an area under the curve in probability distributions demarcated by the critical value. When the test statistic falls in this region, it suggests that the null hypothesis must be rejected. As this region contains all those values of the...
 01:50
Statistical Significance