Discrete and Balanced Spectral Clustering With Scalability
Related Experiment Video
Updated: Jul 17, 2025

ExCYT: A Graphical User Interface for Streamlining Analysis of High-Dimensional Cytometry Data
Published on: January 16, 2019

Abstract:
Spectral Clustering (SC) has been the main subject of intensive research due to its remarkable clustering performance. Despite its successes, most existing SC methods suffer from several critical issues. First, they typically involve two independent stages, i.e., learning the continuous relaxation matrix followed by the discretization of the cluster indicator matrix. This two-stage approach can result in suboptimal solutions that negatively impact the clustering performance. Second, these methods are hard to maintain the balance property of clusters inherent in many real-world data, which restricts their practical applicability. Finally, these methods are computationally expensive and hence unable to handle large-scale datasets. In light of these limitations, we present a novel Discrete and Balanced Spectral Clustering with Scalability (DBSC) model that integrates the learning the continuous relaxation matrix and the discrete cluster indicator matrix into a single step. Moreover, the proposed model also maintains the size of each cluster approximately equal, thereby achieving soft-balanced clustering. What's more, the DBSC model incorporates an anchor-based strategy to improve its scalability to large-scale datasets. The experimental results demonstrate that our proposed model outperforms existing methods in terms of both clustering performance and balance performance. Specifically, the clustering accuracy of DBSC on CMUPIE data achieved a 17.93% improvement compared with that of the SOTA methods (LABIN, EBSC, etc.).
More Related Videos
 07:11
ARL Spectral Fitting as an Application to Augment Spectral Data via Franck-Condon Lineshape Analysis and Color Analysis
Published on: August 19, 2021
 12:27
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
Related Concept Videos
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:14
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:15
Discrete Fourier Transform
 01:08
IR Spectrum Peak Splitting: Symmetric vs Asymmetric Vibrations
 01:15
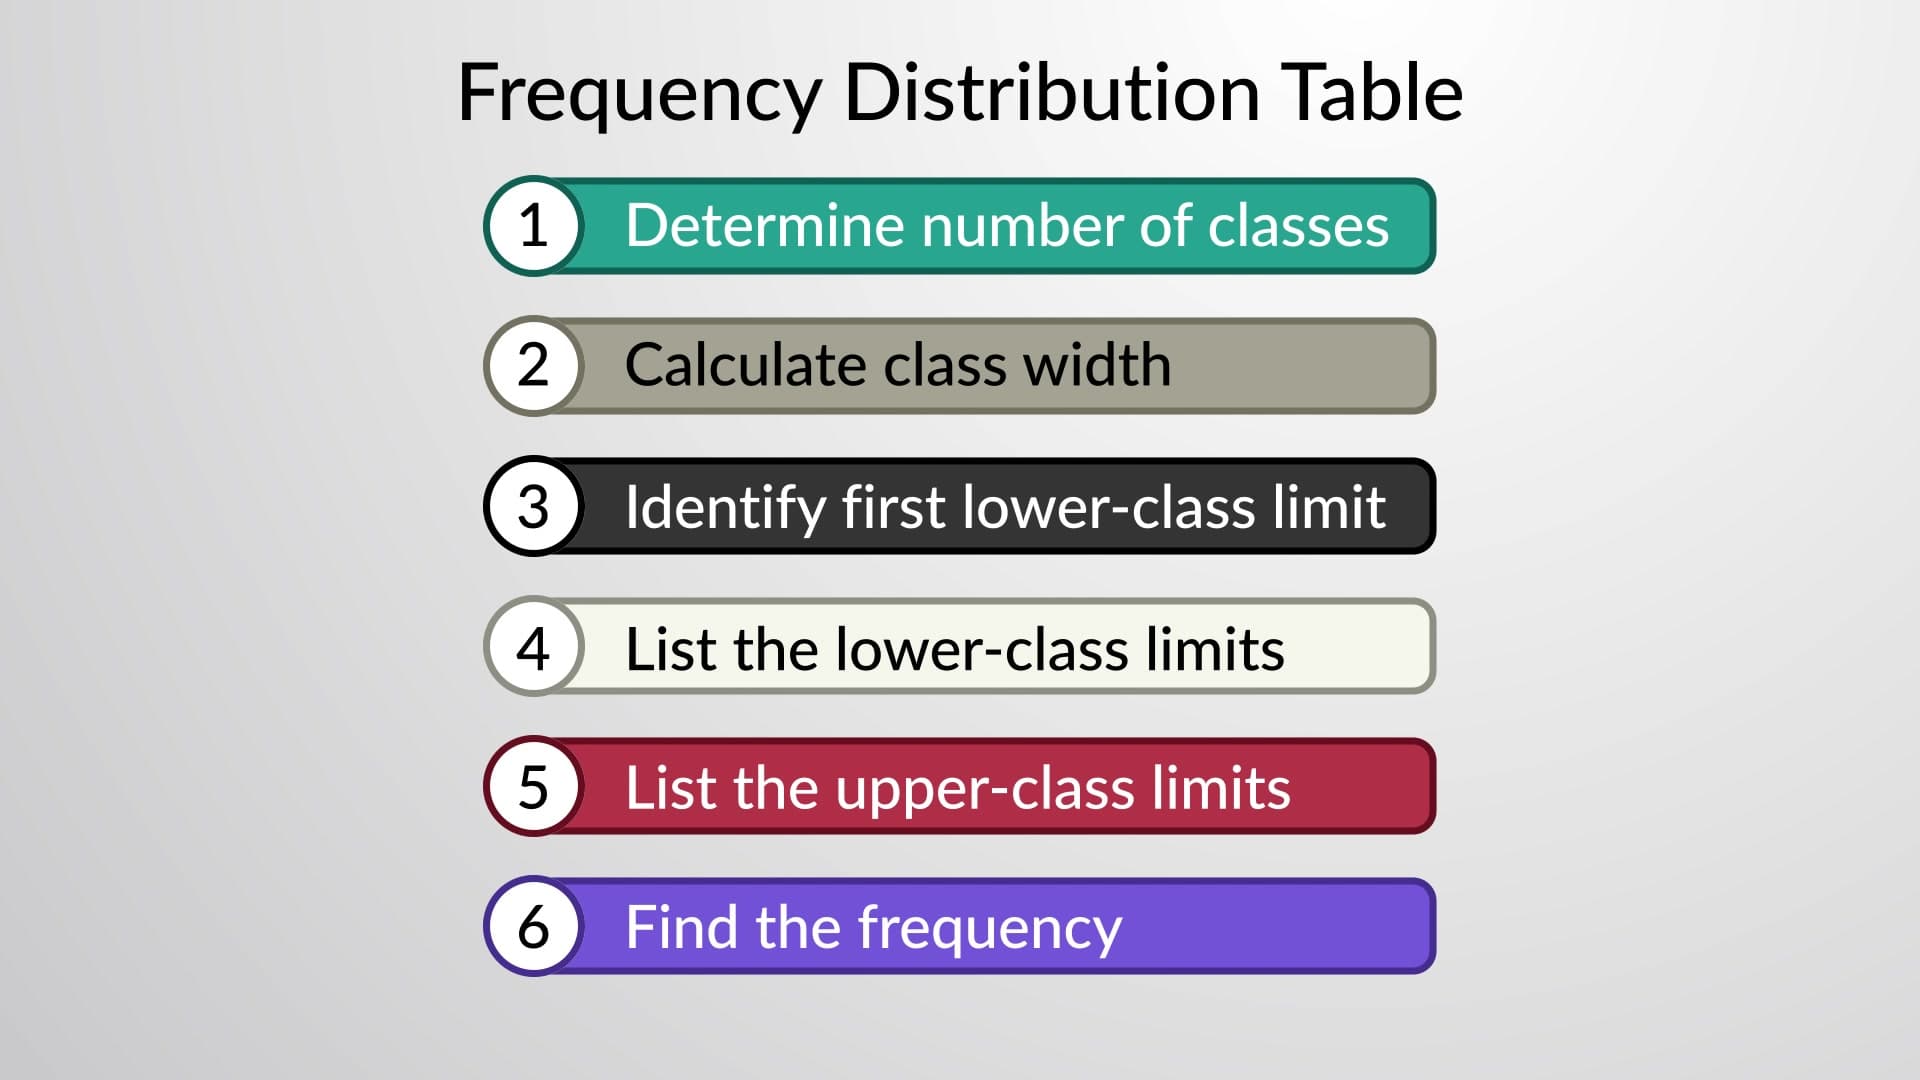
Construction of Frequency Distribution
First, make a table with two columns—one with the title of the data that needs to be organized, and the other column for frequency. [Draw a third column for tally marks if needed]. Then, take a look at the items given in the data set and decide if an ungrouped frequency distribution table or a grouped frequency distribution table would be more suitable. If there are large sets of different values, then it is...