Related Experiment Video
Updated: Jul 16, 2025
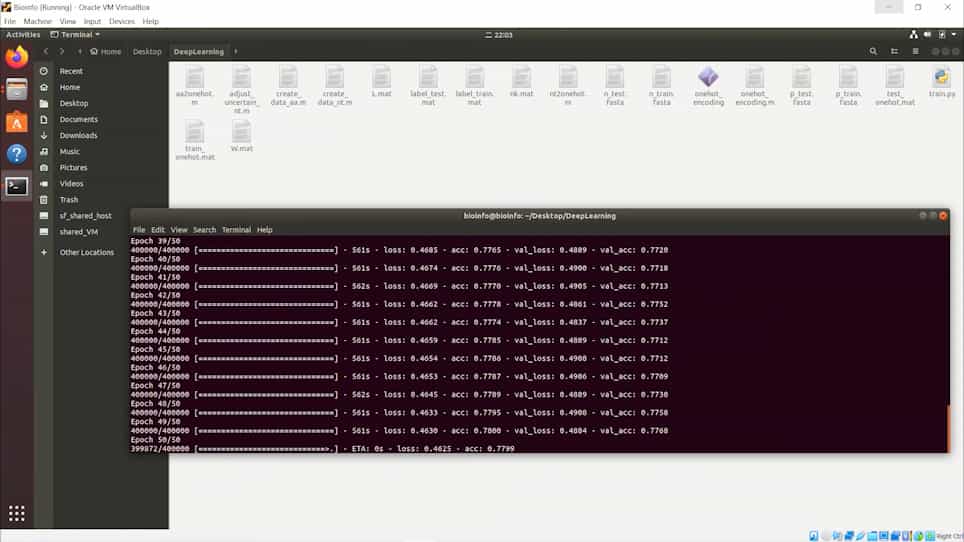

A Virtual Machine Platform for Non-Computer Professionals for Using Deep Learning to Classify Biological Sequences of Metagenomic Data
Published on: September 25, 2021
A self-supervised deep learning method for data-efficient training in genomics
Hüseyin Anil Gündüz1,2, Martin Binder1,2, Xiao-Yin To1,2,3,4
1Department of Statistics, LMU Munich, Munich, Germany.

Abstract:
Deep learning in bioinformatics is often limited to problems where extensive amounts of labeled data are available for supervised classification. By exploiting unlabeled data, self-supervised learning techniques can improve the performance of machine learning models in the presence of limited labeled data. Although many self-supervised learning methods have been suggested before, they have failed to exploit the unique characteristics of genomic data. Therefore, we introduce Self-GenomeNet, a self-supervised learning technique that is custom-tailored for genomic data. Self-GenomeNet leverages reverse-complement sequences and effectively learns short- and long-term dependencies by predicting targets of different lengths. Self-GenomeNet performs better than other self-supervised methods in data-scarce genomic tasks and outperforms standard supervised training with ~10 times fewer labeled training data. Furthermore, the learned representations generalize well to new datasets and tasks. These findings suggest that Self-GenomeNet is well suited for large-scale, unlabeled genomic datasets and could substantially improve the performance of genomic models.
Related Concept Videos
 02:54
Evolutionary Relationships through Genome Comparisons
 02:02
Genomics
 02:07
Improving Translational Accuracy